9 Oct 2026
LLM agents' capabilities depend not only on their underlying models but also on their execution harnesses. Recursive self-improvement (RSI) offers a promising approach to automatically evolve these harnesses.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,688 papers.
9 Oct 2026
LLM agents' capabilities depend not only on their underlying models but also on their execution harnesses. Recursive self-improvement (RSI) offers a promising approach to automatically evolve these harnesses.
8 Oct 2026
Reinforcement learning (RL) is the central training paradigm for advancing large foundation models towards self-improvement. This report introduces the MiMo-V2.6 series, an omni-modal family that pushes the frontier of model intelligence by scaling RL compute.
20 Oct 2026
Large Language Model (LLM) agents can handle increasingly complex tasks, navigating long trajectories of observations and actions. As these trajectories grow, key-value (KV) cache I/O and storage become the dominant cost.
17 Sep 2026
The widespread adoption of long-horizon agents has made model workloads increasingly input-heavy. Although prior work has substantially reduced the cost of long-context computation, prefill remains computationally expensive, and large KV caches continue to strain HBM and SSD…
Yifan Yang, Ziyang Gong, Weiquan Huang et al. · 22 May 2026
Agent skills today are hand-crafted, generated one-shot, or evolved through loosely controlled self-revision, none of which behaves like a deep-learning optimizer for the skill, and none of which reliably improves over its starting point under feedback.
15 Jun 2026
Personalized presentation generation requires more than conditioning on a current prompt or template: agents must preserve stable user preferences across tasks, retain newly introduced preferences and constraints during multi-turn revision, and carry out local edits reliably.
19 Oct 2026
Multimodal large language models (MLLMs) have made rapid progress on visual reasoning, yet many tasks require evidence that is difficult to obtain through internal reasoning alone: our controlled study on 22 benchmarks shows that simply increasing the inference budget of the…
19 Oct 2026
Memory-native evolution requires making memory an intrinsic capability of foundation models, enabling them to continuously accumulate and utilize information. To this end, we introduce MemT-1.0, a new architecture of memory foundation models that internalize memory as part of…
6 Oct 2026
Assistants from 2011 answered and waited, and agents from 2023 did a task and stopped. In September 2026 Meta's Muse showed an agent for one person, with accounts, devices, memory and a conversation that lasts, closed, in a vendor's cloud, in one country.
15 Oct 2026
Training language agents is bottlenecked by the high cost of long-horizon rollouts, yet standard agentic reinforcement learning (RL) learns only from a terminal scalar reward, leaving the supervision in intermediate steps largely unused.
27 Jul 2026
We introduce Kimi K3, a 2.8T parameter Mixture-of-Experts model with 104 billion activated parameters, native vision capabilities, and a 1-million-token context window. Kimi K3 is built on Kimi Delta Attention and Attention Residuals, which improve information flow across…
20 Oct 2026
In this report, we introduce Sage-A1.5, a 35B Mixture-of-Experts agentic model that builds on A1 to advance long-horizon problem solving through adaptive capability composition.
25 Aug 2026
Scientific agents increasingly analyze data, execute code, and produce research artifacts, yet most benchmarks emphasize final answers, isolated programs, or a single domain. We introduce FrontierChallenge, a cross-domain benchmark comprising 300 end-to-end scientific workflows.
12 Jun 2026
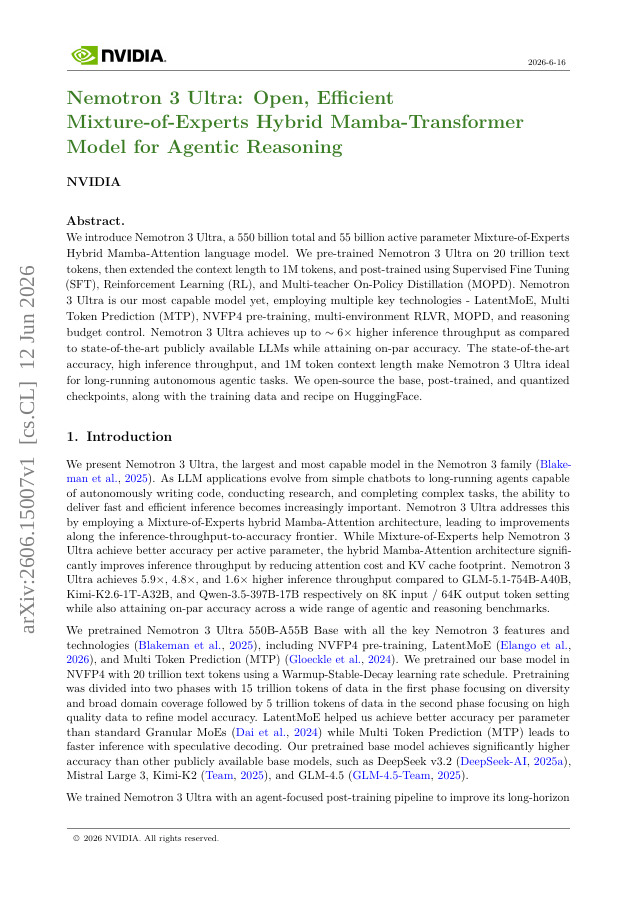
We introduce Nemotron 3 Ultra, a 550 billion total and 55 billion active parameter Mixture-of-Experts Hybrid Mamba-Attention language model. We pre-trained Nemotron 3 Ultra on 20 trillion text tokens, then extended the context length to 1M tokens, and post-trained using…
5 Jul 2026
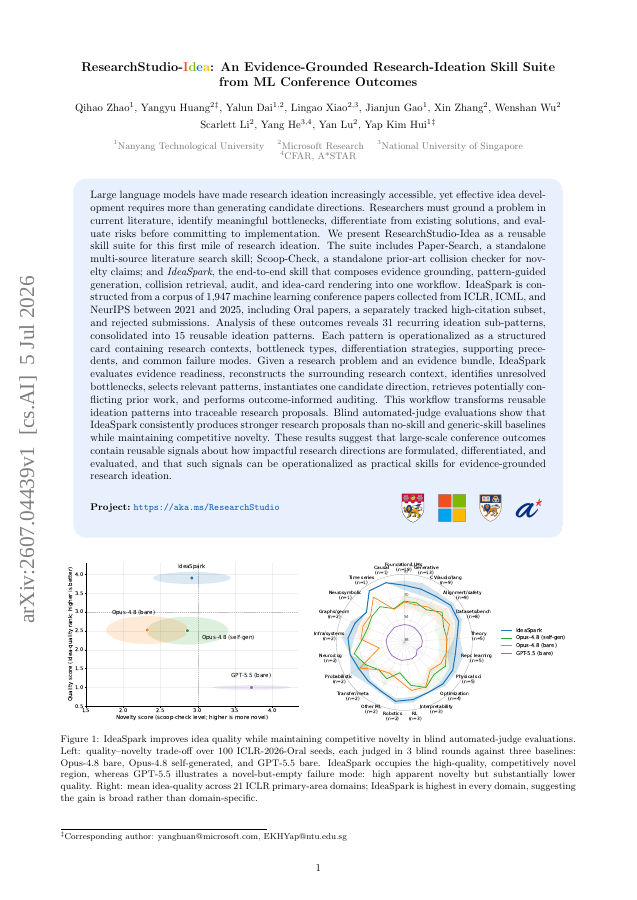
Large language models have made research ideation increasingly accessible, yet effective idea development requires more than generating candidate directions. Researchers must ground a problem in current literature, identify meaningful bottlenecks, differentiate from existing…
1 Jun 2026
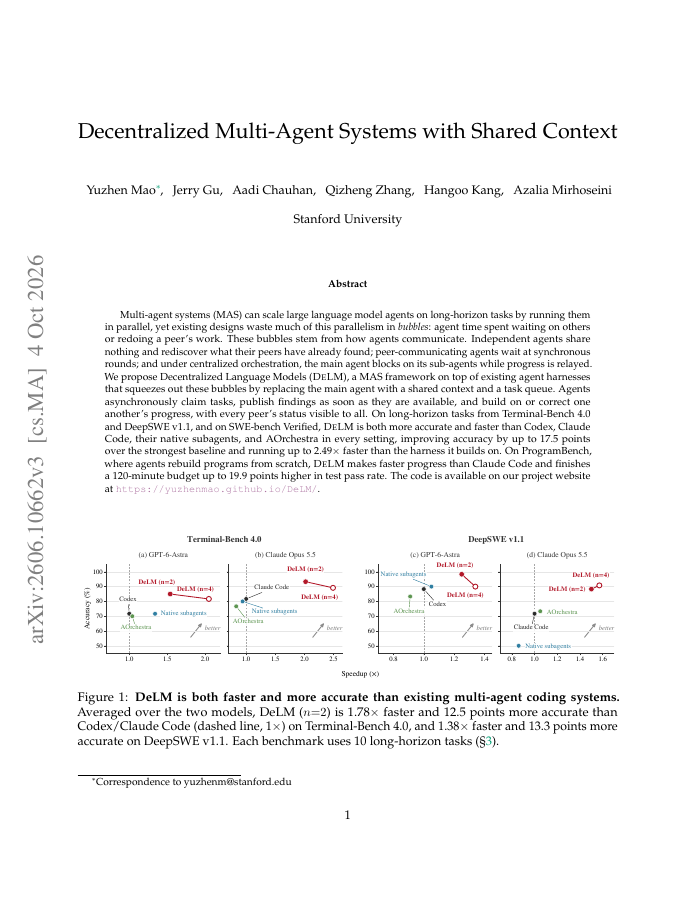
Multi-agent systems (MAS) can scale large language model agents on long-horizon tasks by running them in parallel, yet existing designs waste much of this parallelism in bubbles: agent time spent waiting on others or redoing a peer's work.
4 Sep 2026
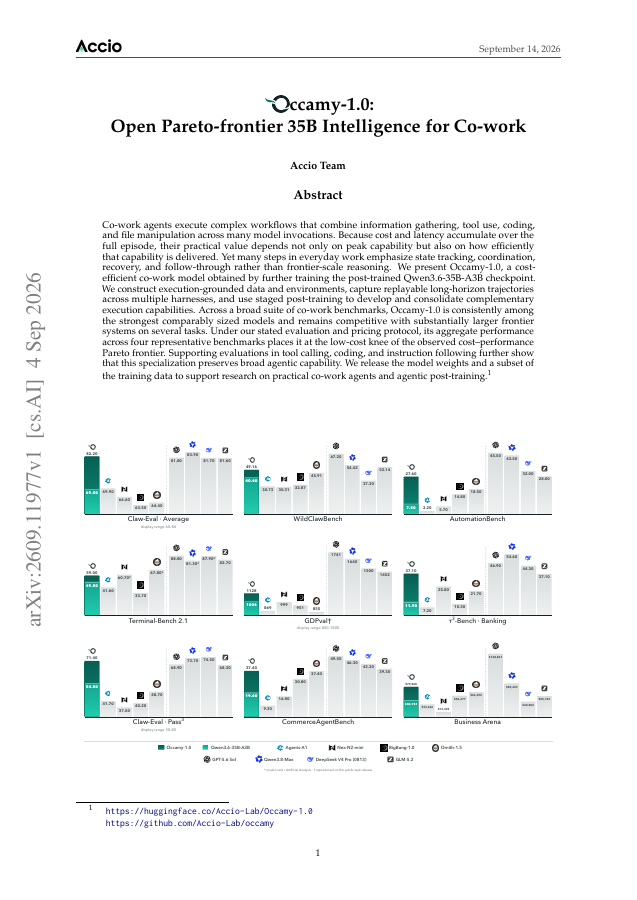
Co-work agents execute complex workflows that combine information gathering, tool use, coding, and file manipulation across many model invocations. Because cost and latency accumulate over the full episode, their practical value depends not only on peak capability but also on…
31 Aug 2026
We describe the architecture and ablations of Qwen3.8-Flash-Next, a sparse mixture-of-experts model with 125B parameters, 6B activated per token, and additional 51B parameters of n-gram embedding tables held off the accelerator.
19 Oct 2026
Harness development plays a crucial role in building capable AI agents. Recent approaches improve harnesses through recursive self-improvement (RSI), but their performance gains often come with higher execution costs.
15 Oct 2026
Data agents use code to process heterogeneous files and derive analytical insights. Scaling their training faces costly environment curation, privacy and intellectual-property restrictions, and difficulty verifying open-ended findings without known generative truth.
27 Sep 2026
As large language models advance, AI agents are moving beyond isolated, domain-specific tasks toward long-horizon, cross-domain workflows. This transition exposes two challenges: increasing harness complexity makes manual design difficult to scale, while tighter coupling to…
20 Oct 2026
Scaling data, diversity and model capacity has improved embodied learning in physical environments, where diverse experiences remain grounded in shared physical laws. Whether these gains extend to virtual worlds with different visual styles, dynamics, controls, and objectives…
21 Oct 2026
Most contemporary artificial intelligence (AI) systems are released with frozen parameters and improve through external updates, whereas an ideal system would keep improving from its own experience, a capacity we call recursive self-improvement (RSI).
21 Oct 2026
Agent harnesses have become a central component of modern agentic systems, shaping how models use tools, manage context, and coordinate long-horizon interaction. Realizing the benefits of these harnesses depends on how effectively the underlying model can make use of them,…