29 Sep 2026
We introduce Context Language Models (CLMs), language models that natively manage their own context. We implement this by treating the context as a file and allowing the model to make unrestricted updates to this file.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,332 papers.
29 Sep 2026
We introduce Context Language Models (CLMs), language models that natively manage their own context. We implement this by treating the context as a file and allowing the model to make unrestricted updates to this file.
17 Sep 2026
World modeling enables intelligence to anticipate consequences, guide interventions, and learn from interaction. Yet predictive models remain domain-specific: can a common learning principle support world modeling across radically different systems? We introduce JEPA-Anything, a…
27 Sep 2026
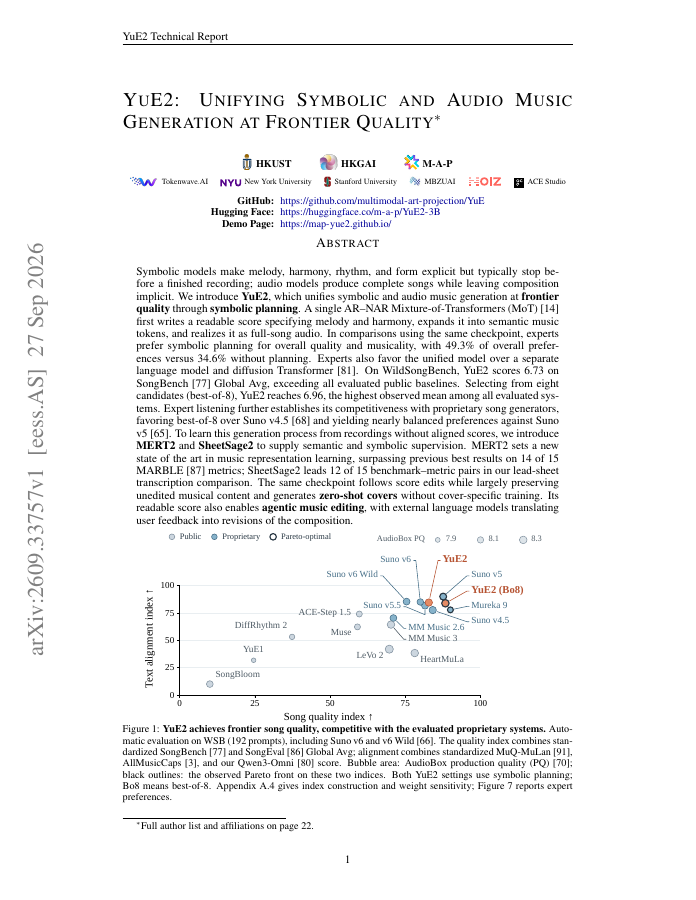
Symbolic models make melody, harmony, rhythm, and form explicit but typically stop before a finished recording; audio models produce complete songs while leaving composition implicit.
29 Sep 2026
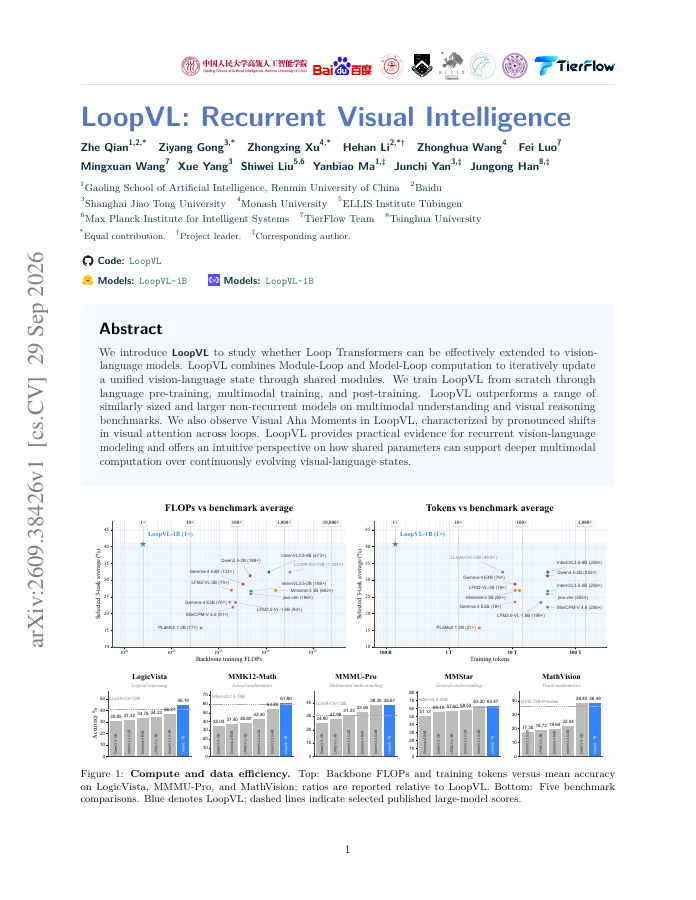
We introduce LoopVL to study whether Loop Transformers can be effectively extended to vision- language models. LoopVL combines Module-Loop and Model-Loop computation to iteratively update a unified vision-language state through shared modules.
2 Oct 2026
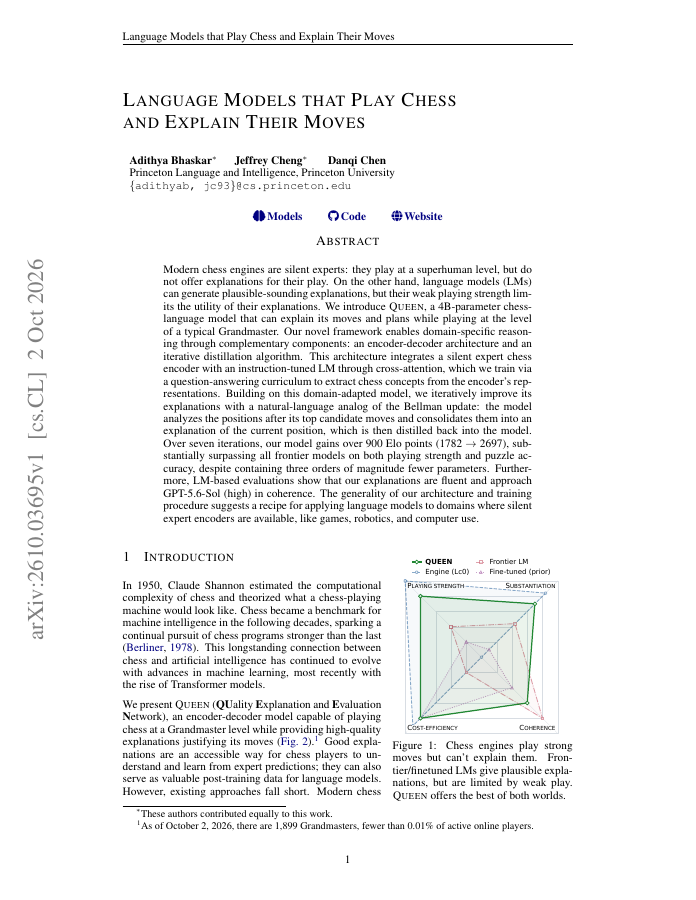
Modern chess engines are silent experts: they play at a superhuman level, but do not offer explanations for their play. On the other hand, language models (LMs) can generate plausible-sounding explanations, but their weak playing strength limits the utility of their…
8 Sep 2026
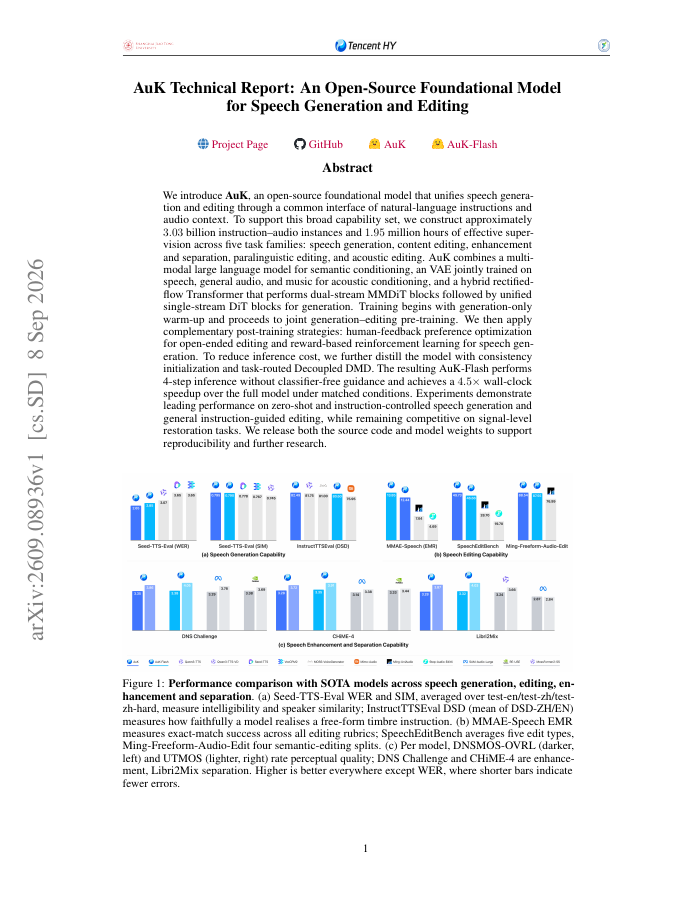
We introduce AuK, an open-source foundational model that unifies speech generation and editing through a common interface of natural-language instructions and audio context.
17 Sep 2026
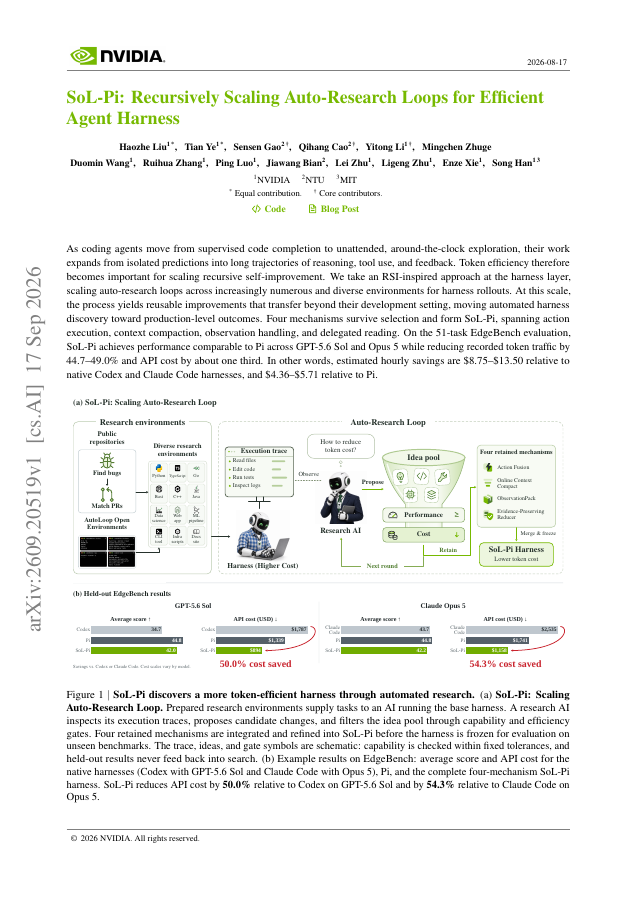
As coding agents move from supervised code completion to unattended, around-the-clock exploration, their work expands from isolated predictions into long trajectories of reasoning, tool use, and feedback.
14 Sep 2026
Recursive self-improvement is becoming increasingly vital for autonomous AI agents, where progress hinges on discovering high-value solutions across complex domains. The driver of this process is effective exploration, however, managing and improving exploration strategies…
9 Sep 2026
We study how model post-training and test-time inference design affect natural-language proof generation for hard olympiad mathematics. Starting from Nemotron 3 Ultra, we train two specialist checkpoints using supervised fine-tuning and reinforcement learning, and evaluate…
15 Sep 2026
Foundation models, alongside advances in learned game-world models, are reshaping AI across the game lifecycle. Beyond playing games, recent systems model players and game dynamics, support design and development, adapt player-facing experiences at runtime, and evaluate…
25 Sep 2026
General-purpose agents can plan, reason, and act over long horizons, yet their production capabilities remain fragmented across text, images, audio, video, documents, 3D assets, and code.
10 Sep 2026
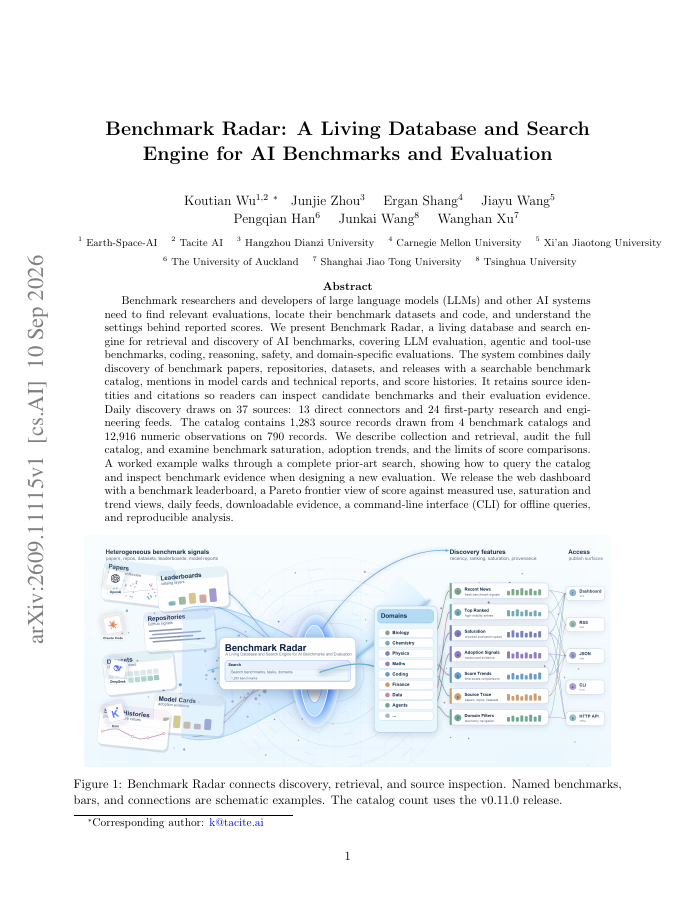
Benchmark researchers and developers of large language models (LLMs) and other AI systems need to find relevant evaluations, locate their benchmark datasets and code, and understand the settings behind reported scores.
1 Oct 2026
Scientific progress emerges from a longitudinal ecosystem in which researchers, institutions, funding agencies, collaboration networks, and the scientific literature co-evolve.
1 Oct 2026
Real-world enterprise data science and analytics workflows require reasoning across dozens of tables, performing statistical analyses, and acting on the results. Established text-to-SQL benchmarks evaluate query generation alone, and audits have found their answer keys…
27 Sep 2026
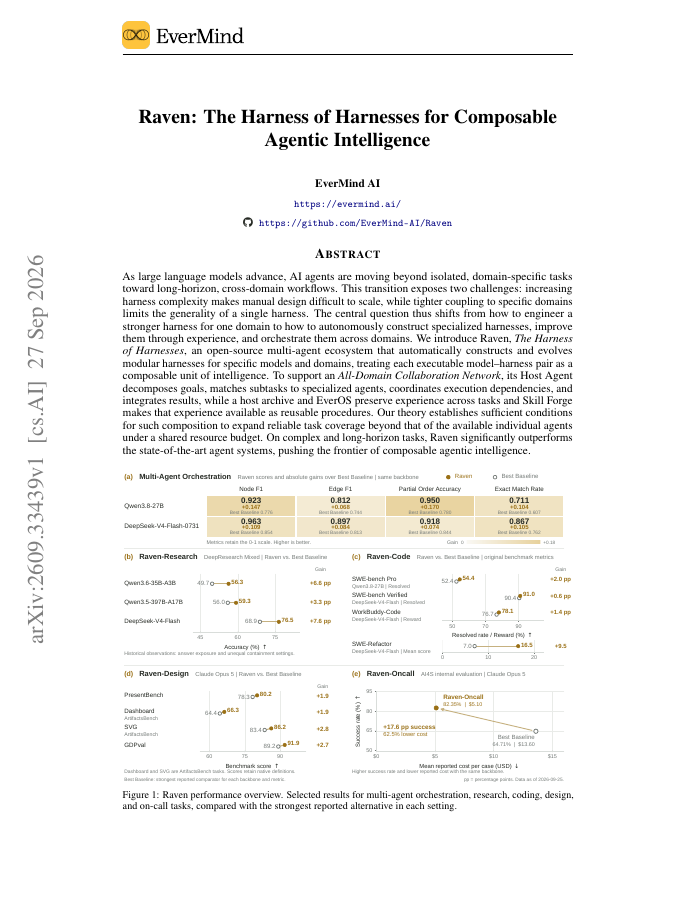
As large language models advance, AI agents are moving beyond isolated, domain-specific tasks toward long-horizon, cross-domain workflows. This transition exposes two challenges: increasing harness complexity makes manual design difficult to scale, while tighter coupling to…
26 Sep 2026
Smaller activation outliers do not necessarily imply better low-bit quantization: their alignment with the quantizer matters. We introduce PrismQuant, a quantizer-aware rotation framework that aligns the leading activation eigenspace with the constant group subspace of…
21 Sep 2026
An LLM agent's capability is largely magnified by its harness, namely the prompts, control flow, tooling, memory, and context management surrounding the frozen backbone model.
28 Sep 2026
Latent visual reasoning (LVR) enables multimodal large language models (MLLMs) to perform intermediate computation in continuous latent tokens rather than expressing every reasoning step in words.
8 Sep 2026
In this work, we present Gander, a native multimodal duplex interaction model that builds on MiniCPM-o 4.5 and is further adapted for realtime interaction with an asynchronous agent loop.
1 Oct 2026
What makes great scientists great? Even as AI systems start to make progress on open problems, scientists remain far ahead of them at sensing which prior idea, buried in an ever-growing archive of research, a new problem needs.
16 Sep 2026
Mixture-of-experts (MoE) inference on consumer hardware is bounded by weight memory: a 35B-class model is 19.5GB at 4-bit, and sparsity shrinks the compute per token, not the bytes that must be held.
2 Oct 2026
LLM-guided evolutionary methods, such as AlphaEvolve, have emerged as powerful approaches for challenging computational optimization problems, such as circle packing. However, prior work typically optimizes performance gain over a fixed number of iterations.
24 Sep 2026
Existing point tracking models face a fundamental tradeoff: they can either track a sparse set of query points over long horizons, or track all points across only short clips.
18 Sep 2026
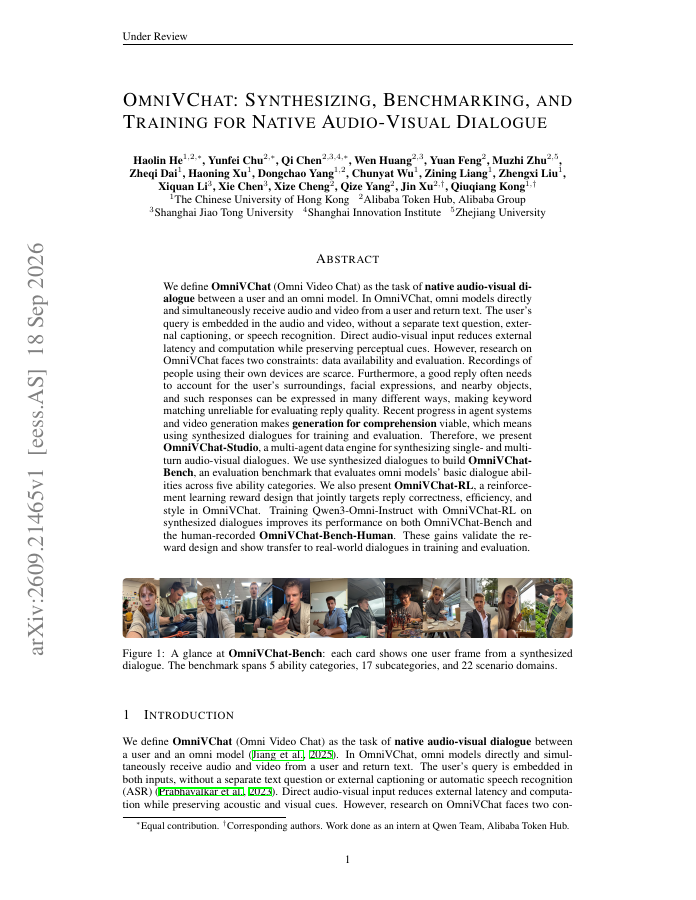
We define OmniVChat (Omni Video Chat) as the task of native audio-visual dialogue between a user and an omni model. In OmniVChat, omni models directly and simultaneously receive audio and video from a user and return text.