1 Mar 2026
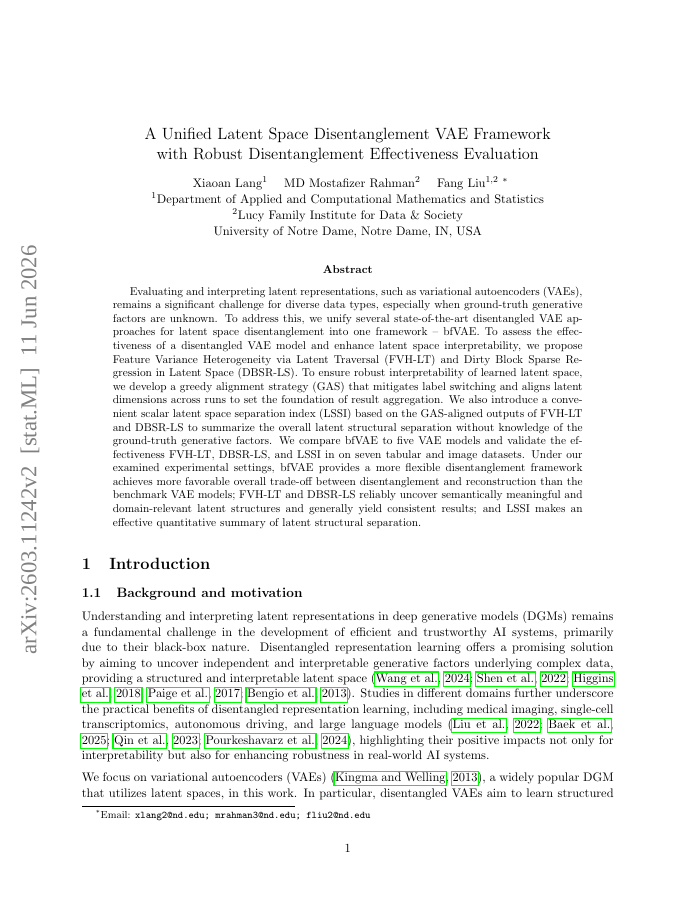
Evaluating and interpreting latent representations, such as variational autoencoders (VAEs), remains a significant challenge for diverse data types, especially when ground-truth generative factors are unknown.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,213 papers.
1 Mar 2026
Evaluating and interpreting latent representations, such as variational autoencoders (VAEs), remains a significant challenge for diverse data types, especially when ground-truth generative factors are unknown.
1 Mar 2026
While multilingual language models successfully transfer factual and syntactic knowledge across languages, it remains unclear whether they process culture-specific pragmatic registers, such as slang, as isolated language-specific memorizations or as unified, abstract concepts.
1 Mar 2026
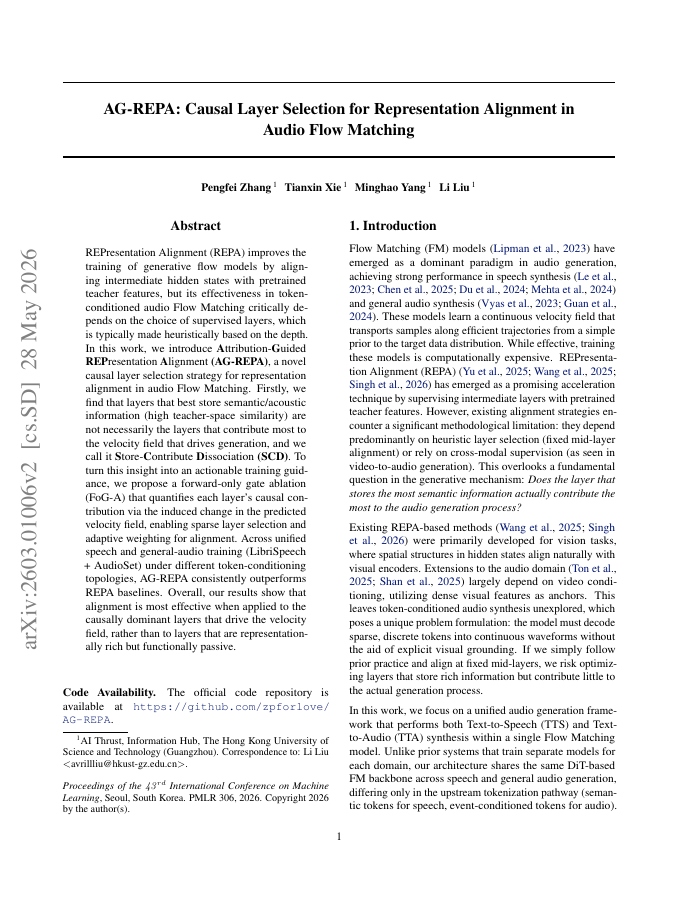
REPresentation Alignment (REPA) improves the training of generative flow models by aligning intermediate hidden states with pretrained teacher features, but its effectiveness in token-conditioned audio Flow Matching critically depends on the choice of supervised layers, which is…
1 Mar 2026
Large language model-based AI agents are now able to autonomously execute substantial portions of a high energy physics (HEP) analysis pipeline with minimal expert-curated input.
1 Mar 2026
Conversational AI systems are increasingly used for personal reflection and emotional disclosure, raising concerns about their effects on vulnerable users. Recent anecdotal reports suggest that prolonged interactions with AI may reinforce delusional thinking---a phenomenon…
1 Mar 2026
Predictive maintenance for connected vehicles offers the potential to reduce unexpected breakdowns and improve fleet reliability, but most existing systems rely exclusively on internal diagnostic signals and are validated on simulated or industrial benchmark data.
1 Mar 2026
Mixture-of-Experts (MoE) language models increase parameter capacity without proportional per-token computation, yet deployment still requires storing the full expert pool, making expert pruning important for reducing memory and serving overhead.
27 Feb 2026
Large language model (LLM) agents, such as OpenAI's Operator and Claude's Computer Use, can automate workflows but unable to handle payment tasks. Existing agentic solutions have gained significant attention; however, even the latest approaches face challenges in implementing…
Dahua Lin, Xin Wang, Shiqi He · 27 Feb 2026
AIDABench is a comprehensive benchmark evaluating AI systems on complex document analysis tasks that span multiple capability dimensions and reflect real-world analytical demands across diverse industries.
Danyang Zhang, Dahua Lin, Ziqiao Ma · 23 Feb 2026
Rapid progress in video models has largely focused on visual quality, leaving their reasoning capabilities underexplored. Video reasoning grounds intelligence in spatiotemporally consistent visual environments that go beyond what text can naturally capture, enabling intuitive…
Yousof Gheisari, Mohammadreza Ghaffarzadeh-Esfahani · 21 Feb 2026
AAVGen is a generative AI framework that designs AAV capsids with improved traits through protein language models, supervised fine-tuning, and reinforcement learning techniques.
Gabriel Mongaras, Eric C. Larson · 19 Feb 2026
Researchers enhance linear attention by simplifying Mamba-2 and improving its architectural components to achieve near-softmax accuracy while maintaining memory efficiency for long sequences.
Johannes Kirmayr, Lukas Stappen, Elisabeth André · 17 Feb 2026
Users prefer adaptive feedback mechanisms in in-car AI assistants, starting with high transparency to build trust and then reducing verbosity as reliability increases, particularly in attention-critical driving scenarios.
Nihal V. Nayak, Sara Beery, David Alvarez-Melis · 16 Feb 2026
Instruction fine-tuning of large language models (LLMs) often involves selecting a subset of instruction training data from a large candidate pool, using a small query set from the target task.
Dongrui Liu, Xia Hu, Jingyi Yu · 16 Feb 2026
Clawdbot, a self-hosted AI agent with diverse tool capabilities, exhibits varying safety performance across different risk dimensions, particularly struggling with ambiguous or adversarial inputs despite consistent reliability in specified tasks.
15 Feb 2026
Predicting links in sparse, continuously evolving networks is a central challenge in network science. Conventional heuristic methods and deep learning models, including Graph Neural Networks (GNNs), are typically designed for static graphs and thus struggle to capture temporal…
Matteo Fasulo, Luca Tedeschini · 13 Feb 2026
A hierarchical approach for detecting reclaimed slurs combines weakly supervised LLM annotation with BERT-like models to incorporate LGBTQ+ community identity and sociolinguistic context into hate speech detection.
Xin Liu, Ye He, Jiawei Han · 12 Feb 2026
Embodied navigation has long been fragmented by task-specific architectures.
11 Feb 2026
Many real-world datasets contain hidden structure that cannot be detected by simple linear correlations between input features. For example, latent factors may influence the data in a coordinated way, even though their effect is invisible to covariance-based methods such as PCA.
Mu Xu, Feng Xiong, Shuang Zeng · 11 Feb 2026
Building general-purpose embodied agents across diverse hardware remains a central challenge in robotics, often framed as the ''one-brain, many-forms'' paradigm.
Shangchen Zhou, Chen Change Loy, Yihang Luo · 10 Feb 2026
4RC presents a unified feed-forward framework for 4D reconstruction from monocular videos that learns holistic scene geometry and motion dynamics through a transformer-based encoder-decoder architecture with conditional querying capabilities.
9 Feb 2026
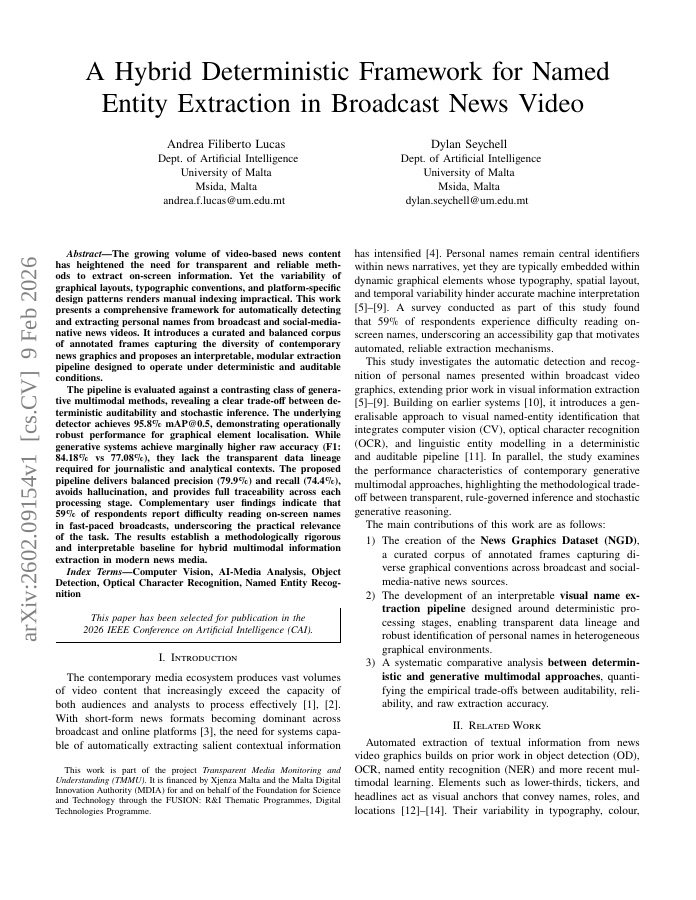
The growing volume of video-based news content has heightened the need for transparent and reliable methods to extract on-screen information. Yet the variability of graphical layouts, typographic conventions, and platform-specific design patterns renders manual indexing…
Jakob Foerster, Tatiana Shavrina, Amar Budhiraja · 6 Feb 2026
AIRS-Bench presents a comprehensive benchmark suite for evaluating LLM agents across diverse scientific domains, demonstrating current limitations while providing open-source resources for advancement.
Zhendong Mao, Benfeng Xu, Mingxuan Du · 3 Feb 2026
Frontier language models have demonstrated strong reasoning and long-horizon tool-use capabilities.