13 Oct 2026
We introduce Fish Audio Drama 3, an open-source speech generation model that turns text into directed performances, built on a 35B-parameter mixture-of-experts backbone that activates 3B parameters per token.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,656 papers.
13 Oct 2026
We introduce Fish Audio Drama 3, an open-source speech generation model that turns text into directed performances, built on a 35B-parameter mixture-of-experts backbone that activates 3B parameters per token.
27 Sep 2026
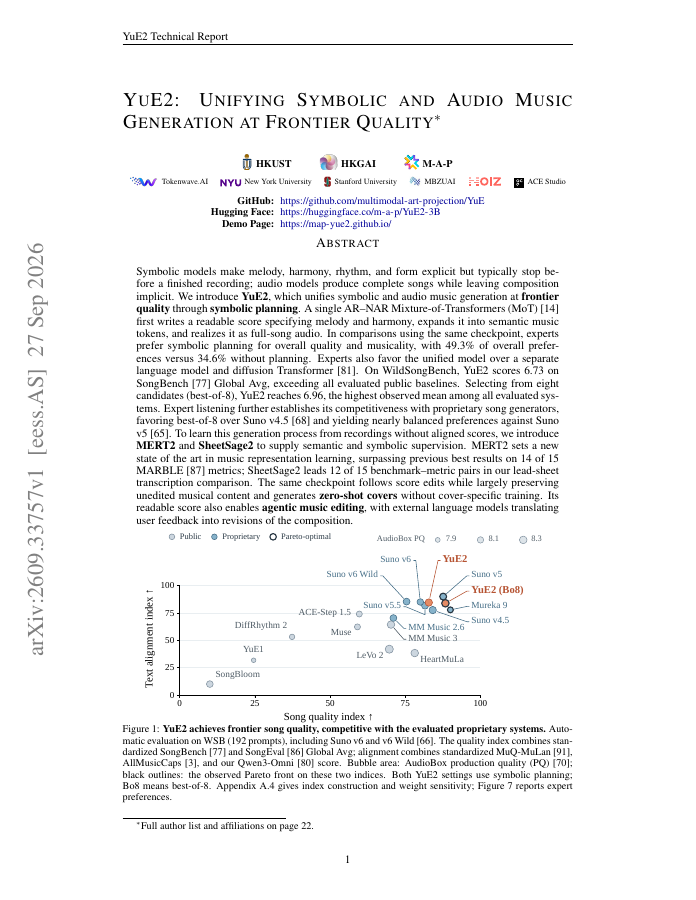
Symbolic models make melody, harmony, rhythm, and form explicit but typically stop before a finished recording; audio models produce complete songs while leaving composition implicit.
8 Sep 2026
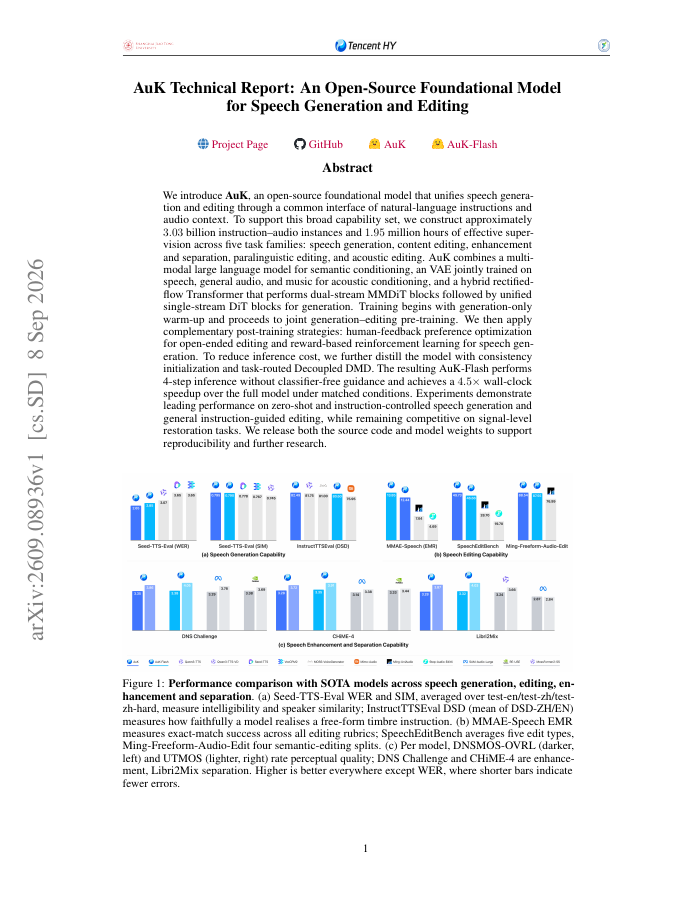
We introduce AuK, an open-source foundational model that unifies speech generation and editing through a common interface of natural-language instructions and audio context.