9 Oct 2026
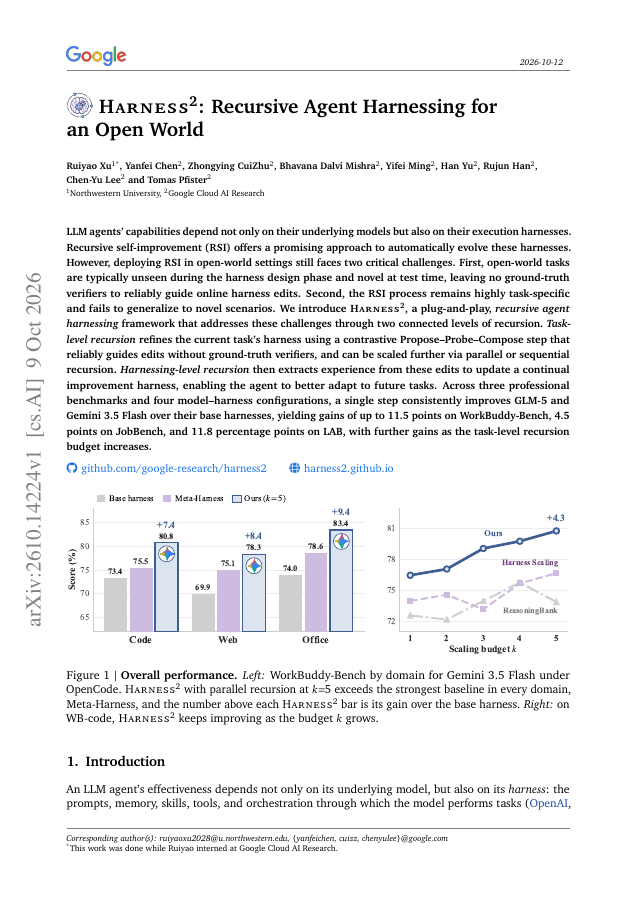
LLM agents' capabilities depend not only on their underlying models but also on their execution harnesses. Recursive self-improvement (RSI) offers a promising approach to automatically evolve these harnesses.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,736 papers.
9 Oct 2026
LLM agents' capabilities depend not only on their underlying models but also on their execution harnesses. Recursive self-improvement (RSI) offers a promising approach to automatically evolve these harnesses.
25 Aug 2026
Scientific agents increasingly analyze data, execute code, and produce research artifacts, yet most benchmarks emphasize final answers, isolated programs, or a single domain. We introduce FrontierChallenge, a cross-domain benchmark comprising 300 end-to-end scientific workflows.
21 Sep 2026
An LLM agent's capability is largely magnified by its harness, namely the prompts, control flow, tooling, memory, and context management surrounding the frozen backbone model.
17 Sep 2026
As coding agents move from supervised code completion to unattended, around-the-clock exploration, their work expands from isolated predictions into long trajectories of reasoning, tool use, and feedback.
19 Oct 2026
GPT-6-Astra demonstrates a level of competence in robotic manipulation and navigation that challenges the conventional paradigm of building specialized models for individual tasks and embodiments.
23 Oct 2026
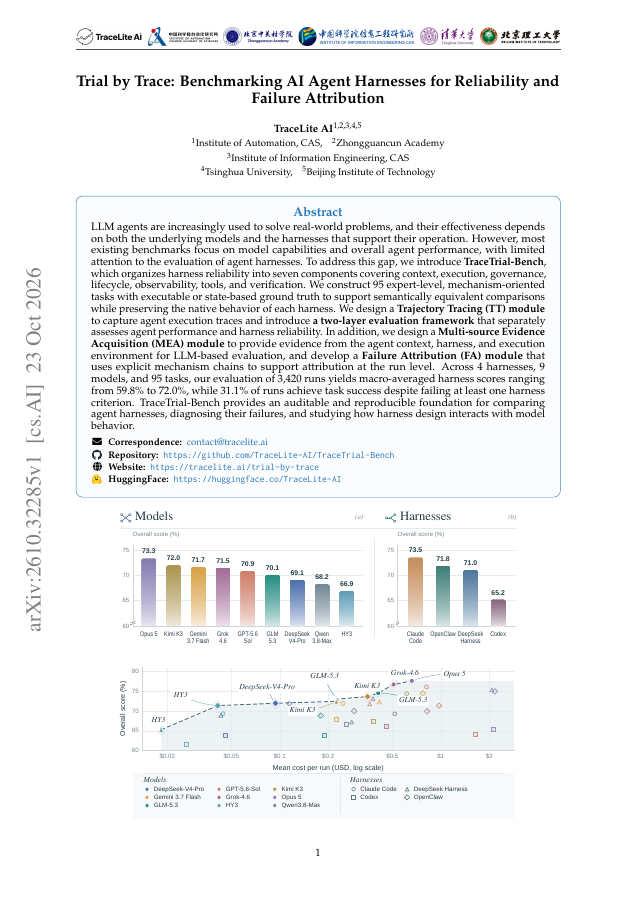
LLM agents are increasingly used to solve real-world problems, and their effectiveness depends on both the underlying models and the harnesses that support their operation.