9 Oct 2026
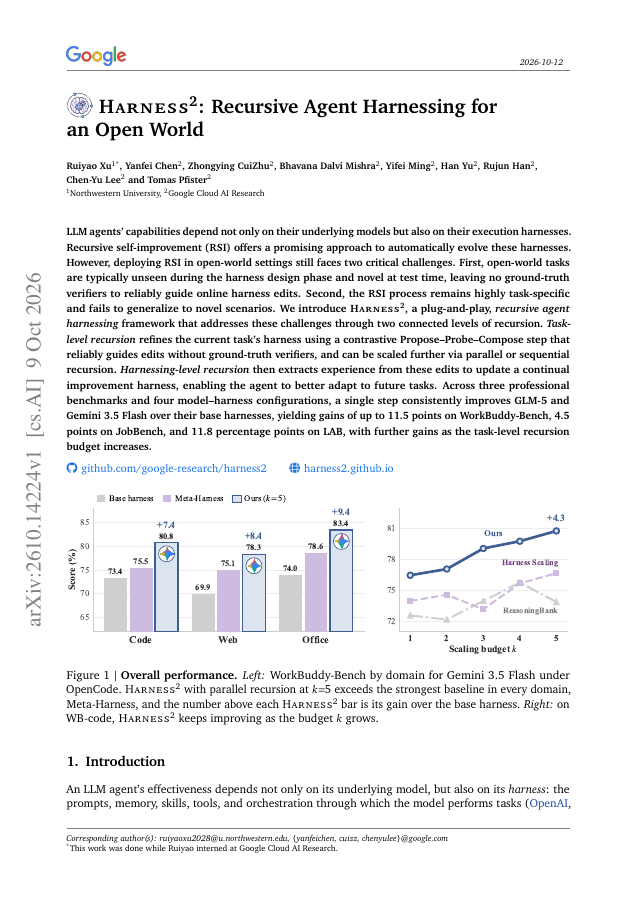
LLM agents' capabilities depend not only on their underlying models but also on their execution harnesses. Recursive self-improvement (RSI) offers a promising approach to automatically evolve these harnesses.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,997 papers.
9 Oct 2026
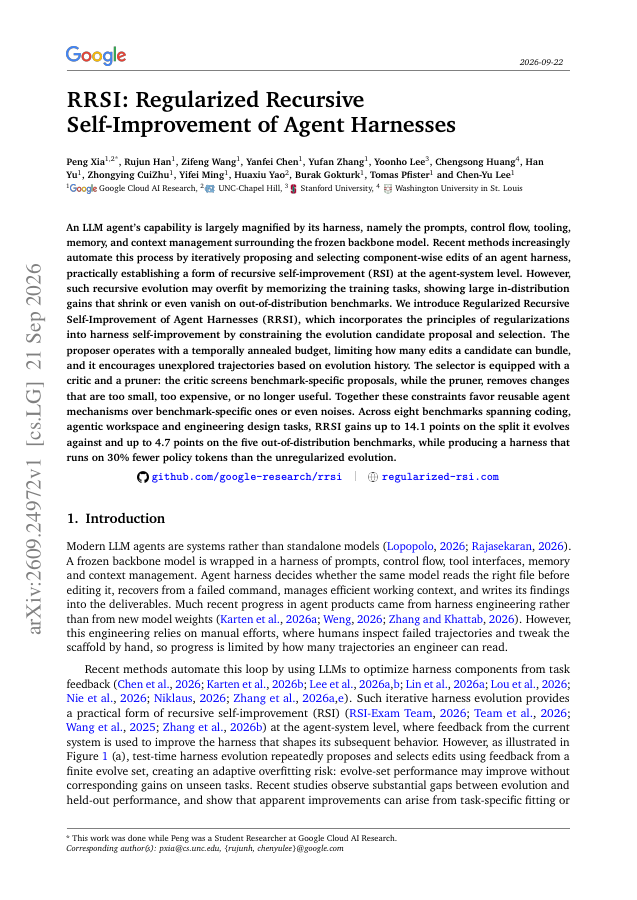
LLM agents' capabilities depend not only on their underlying models but also on their execution harnesses. Recursive self-improvement (RSI) offers a promising approach to automatically evolve these harnesses.
21 Sep 2026
An LLM agent's capability is largely magnified by its harness, namely the prompts, control flow, tooling, memory, and context management surrounding the frozen backbone model.
30 Oct 2026
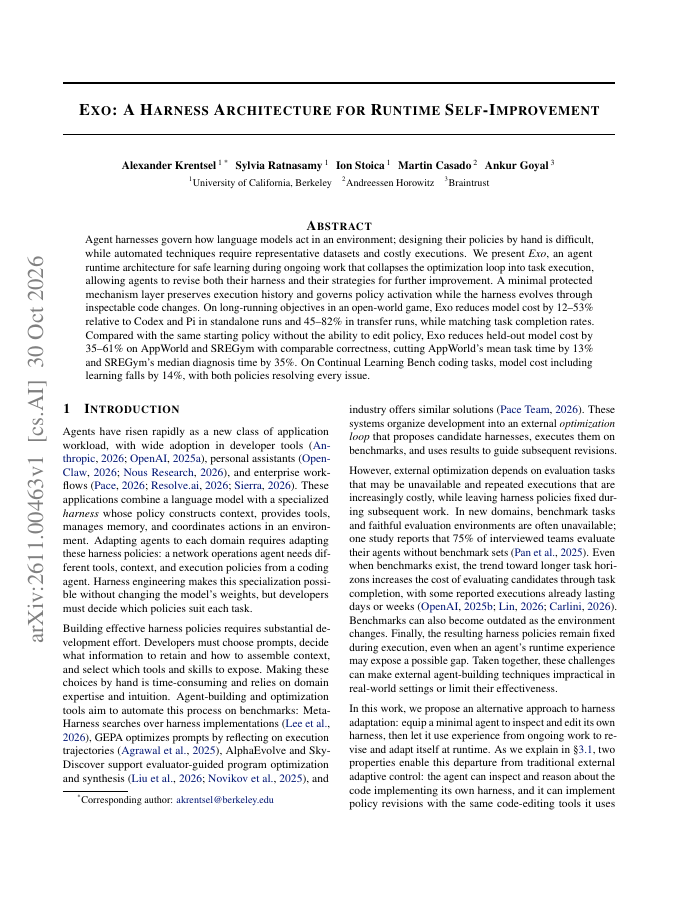
Agent harnesses govern how language models act in an environment; designing their policies by hand is difficult, while automated techniques require representative datasets and costly executions.
12 Nov 2026
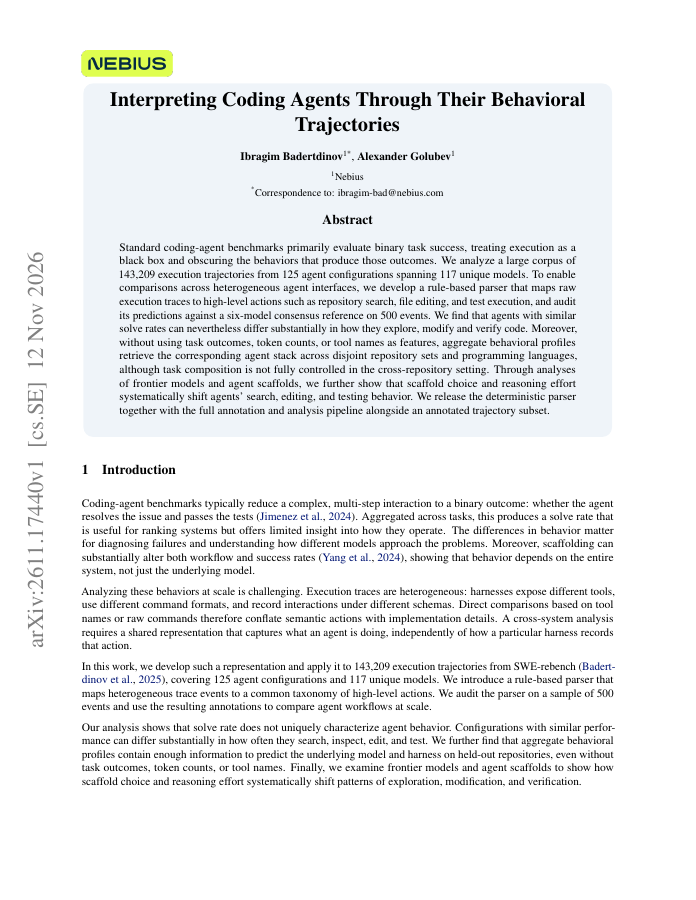
Standard coding-agent benchmarks primarily evaluate binary task success, treating execution as a black box and obscuring the behaviors that produce those outcomes. We analyze a large corpus of 143,209 execution trajectories from 125 agent configurations spanning 117 unique…