28 Sep 2026
Mixture-of-Experts (MoE) models repeatedly route tokens to sparse subsets of experts, but conventional routers expose no routing-specific record of how cross-layer influences accumulate.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,381 papers.
28 Sep 2026
Mixture-of-Experts (MoE) models repeatedly route tokens to sparse subsets of experts, but conventional routers expose no routing-specific record of how cross-layer influences accumulate.
28 Sep 2026
When a doctor, a judge, or an engineer must decide whether to trust an AI model's output, they cannot avoid asking what the model understands. Purely mathematical or statistical descriptions struggle to distinguish trustworthy from untrustworthy outputs without reintroducing the…
28 Sep 2026
Language model post-training is often bottlenecked by the need for human-collected preference data, which is expensive and difficult to scale. Reinforcement learning from AI feedback (RLAIF) style approaches that leverage pseudo labels offer an abundant alternative but introduce…
28 Sep 2026
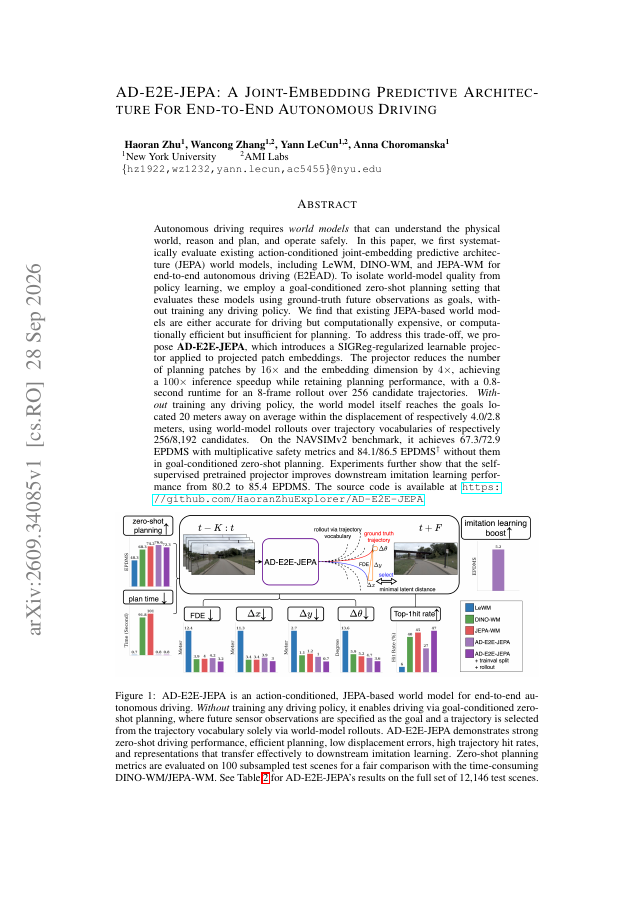
Autonomous driving requires \textit{world models} that can understand the physical world, reason and plan, and operate safely. In this paper, we first systematically evaluate existing action-conditioned joint-embedding predictive architecture (JEPA) world models, including LeWM,…
27 Sep 2026
Tracking any point of a dynamic scene in metric 3D - in absolute meters, not up to an unknown scale - underpins 3D and 4D reconstruction, robot navigation, and autonomous driving, where decisions are made in meters, not pixels.
27 Sep 2026
When post-training large language models on tasks with semi-verifiable rewards, there are many factors (training steps, base model size, training order, data quality, verifier accuracy, etc.) that practitioners must contend with to maximize model performance.
27 Sep 2026
Phishing remains one of the most common vectors for financial and identity fraud, and most detection systems still rely on inspecting a page's URL, HTML markup, or domain registration history.
27 Sep 2026
Many dense-prediction benchmarks evaluate rare events by pooling prediction and target over spatial blocks, thresholding each, and scoring the contingency table. At a fixed rare operating point, the max-pooled Critical Success Index (CSI) confounds spatial discrimination with…
27 Sep 2026
Self-supervised pretraining learns representations that are broadly transferable across downstream tasks, yet direct fine-tuning can be suboptimal due to misalignment between self-supervised and downstream task objectives, potentially degrading pretrained features beneficial to…
27 Sep 2026
High-bandwidth plasma diagnostics increasingly provide inputs to machine learning and signal-processing algorithms intended for real-time tokamak control, but the complete path from diagnostic sampling to control-system handoff is difficult to commission because of their…
27 Sep 2026
How does compositional reasoning emerge during learning? We address this question by mathematically analyzing the learning dynamics of deep linear networks. We train these networks in structured synthetic environments and derive a theory linking the structure of experience to…
27 Sep 2026
Knowledge Distillation (KD) has emerged as a vital paradigm for transferring the capabilities of high-capacity models to efficient ``student'' counterparts, addressing critical challenges in computational cost, deployment constraints, and privacy-sensitive settings.
27 Sep 2026
Historical manuscript illustrations preserve rich visual evidence of past cultures. They depict people, animals, plants, diagrams, music notations, and decorative forms.
27 Sep 2026
A central aim of neuromorphic computing is to provide a viable alternative to highly energy-intensive Transformer-based AI. However, efficient alternatives struggle to capture the set of qualities that have secured the Transformer's status as the de facto standard in sequence…
27 Sep 2026
Scientific code generation can produce executable programs that fail to compute the intended scientific object. We study this problem in language-model synthesis of Clifford circuits, which prepare the stabilizer states used in quantum error correction and admit exact classical…
26 Sep 2026
Surrogate models are commonly evaluated by how often they agree with their teacher model over an evaluation set. Local variation in this agreement is well known, but its structure and consequences are less clear.
26 Sep 2026
LLM agents increasingly keep working after a task succeeds as they resume after compaction or take over handoffs. Their finished work keeps receiving follow-up input that sometimes falsely accuses it for later failures.
26 Sep 2026
Reinforcement mid-training lets language models learn internal thoughts from unlabeled text, but efficient token-level credit assignment remains challenging. Existing group-relative methods require costly repeated generation.
26 Sep 2026
Audiology consultation requires structured history-taking, audiometric interpretation and patient-centred communication, yet real-world case material is scarce. We present a bilingual AI audiologist pairing a general-purpose large language model with rubric-guided playbook…
26 Sep 2026
Transformers and state-space models (SSMs) are two prominent sequential learning architectures, yet their comparison remains largely empirical and existing theoretical analyses are typically task-specific or architecturally restricted.
26 Sep 2026
Language models are increasingly evaluated as vulnerability detectors, and scores reported for similar models differ widely between papers. We measured how much of that difference evaluation protocol accounts for, with model outputs held fixed.
26 Sep 2026
It has recently been found that deep learning often occurs at the "edge of stability (EoS)," where the maximum Hessian eigenvalue of the model is stabilized at a value reciprocal to the learning rate.
26 Sep 2026
Who we communicate with influences both our interpretation of their utterances and the design of our own. Such adjustment to the conversational partner is studied as speaker modeling in comprehension and as audience design in production, with the two literatures having developed…
26 Sep 2026
Pre-training data poisoning of large language models is usually studied using targeted backdoors and their survival through safety post-training, which leaves open a more basic question: how does a model's clean data performance degrade as the poison rate $\varepsilon$ grows?…