8 Oct 2026
Reliable predictive uncertainty in Laplace approximations depends critically on the prior precision, yet selecting it requires a posterior sweep that is prohibitively expensive for neural networks with billions of parameters.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,411 papers.
8 Oct 2026
Reliable predictive uncertainty in Laplace approximations depends critically on the prior precision, yet selecting it requires a posterior sweep that is prohibitively expensive for neural networks with billions of parameters.
8 Oct 2026
We describe a 4-tensor attention model that predicts the next semantic state of a scene, for video generation and robot planning. A window of states has positions (x, t) and two fibers, a semantic fiber and a temporal-context fiber, and one softmax normalizes attention jointly…
8 Oct 2026
The kernel bandit problem consists of sequentially optimizing an unknown function with noisy feedback, where the function has bounded norm in a given Reproducing Kernel Hilbert Space (RKHS).
8 Oct 2026
Automated methods have been proposed to overcome the limitations of human verbal deception detection, but evidence remains fragmented across disciplines. We systematically reviewed 25 years of research (289 reports, 6,136 classification models) and meta-analyzed 3,653 models…
7 Oct 2026
There are more than 2,000 listed companies on the UK's London Stock Exchange, divided into 11 sectors who are required to communicate their financial results at least twice in a single financial year. UK annual reports are very lengthy documents with around 80 pages on average.
7 Oct 2026
Continual pre-training and fine-tuning in Large Language Models (LLMs) inevitably induce catastrophic forgetting, typically mitigated by replay using often-inaccessible original data. In this data-free regime, we analyze where forgetting occurs and why.
6 Oct 2026
Model merging offers a promising solution for combining multiple fine-tuned checkpoints into a single model through parameter arithmetic. However, finding optimal merging coefficients requires an extensive search that becomes prohibitively expensive as models scale in both size…
6 Oct 2026
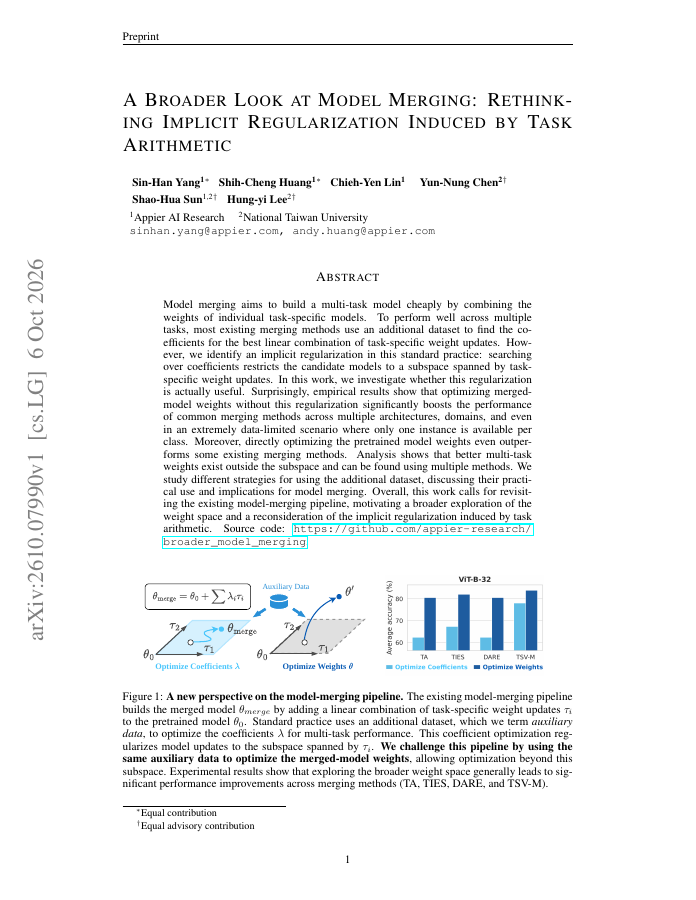
Model merging aims to build a multi-task model cheaply by combining the weights of individual task-specific models. To perform well across multiple tasks, most existing merging methods use an additional dataset to find the coefficients for the best linear combination of…
6 Oct 2026
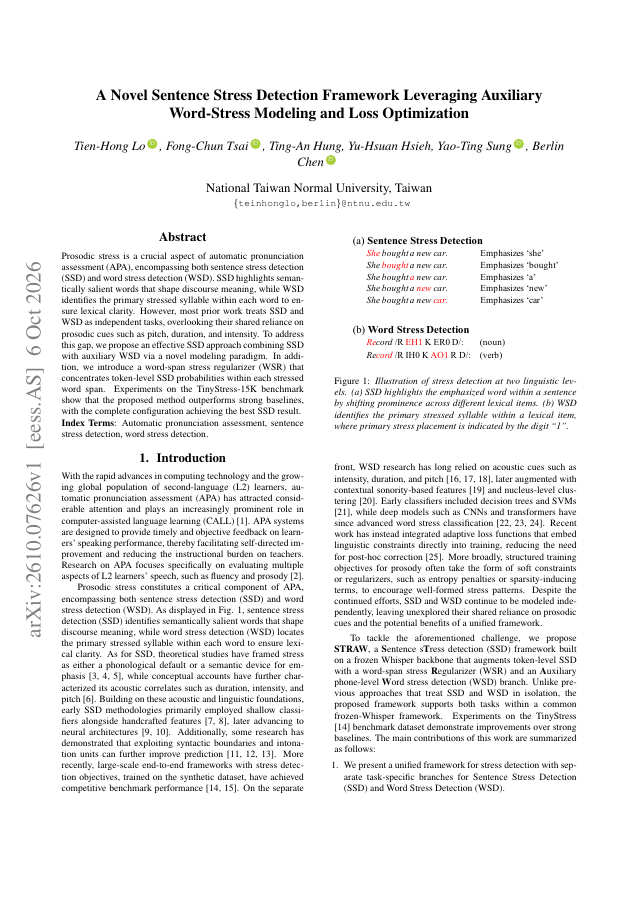
Prosodic stress is a crucial aspect of automatic pronunciation assessment (APA), encompassing both sentence stress detection (SSD) and word stress detection (WSD). SSD highlights semantically salient words that shape discourse meaning, while WSD identifies the primary stressed…
6 Oct 2026
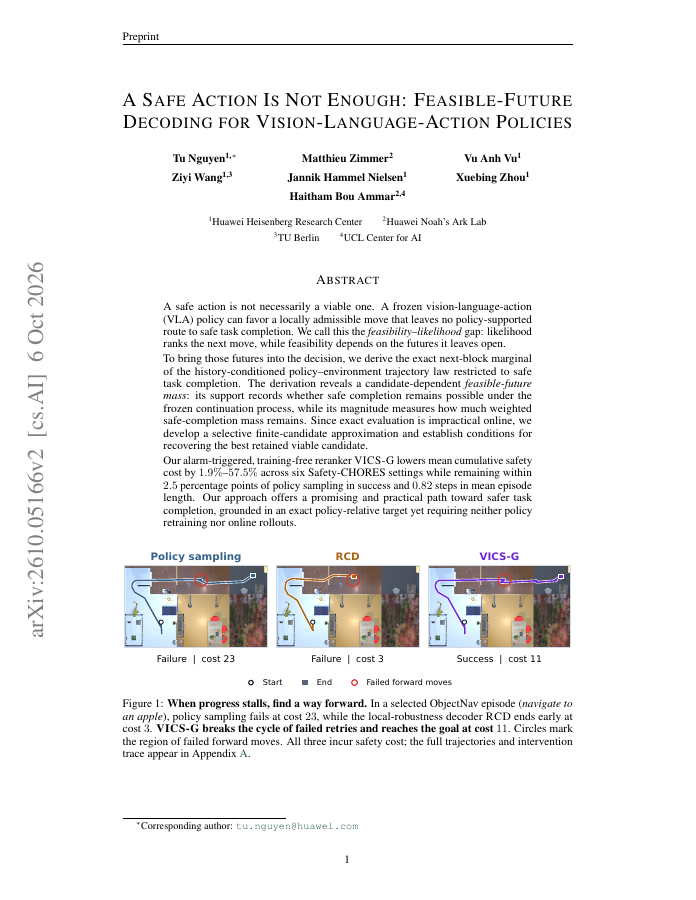
A safe action is not necessarily a viable one. A frozen vision-language-action (VLA) policy can favor a locally admissible move that leaves no policy-supported route to safe task completion.
6 Oct 2026
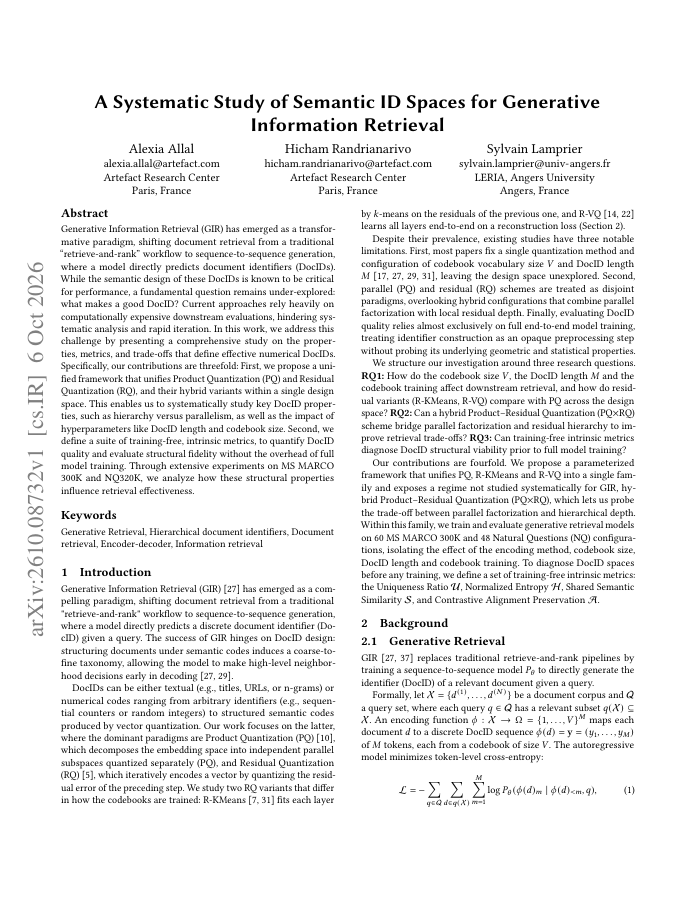
Generative Information Retrieval (GIR) has emerged as a transformative paradigm, shifting document retrieval from a traditional "retrieve-and-rank" workflow to sequence-to-sequence generation, where a model directly predicts document identifiers (DocIDs).
6 Oct 2026
Endpoint accuracy on abstract-reasoning benchmarks does not reveal whether a language model has acquired a transferable rule or fit distribution-specific regularities. We study this distinction in small language models on the ARC-TGI benchmark, which organizes abstract grid…
5 Oct 2026
Modern text-to-speech (TTS) systems can clone a target speaker from a short reference clip or be fine-tuned on a target voice, yet their behaviour on morphologically rich, lower-resource languages such as Turkish remain under-characterised.
5 Oct 2026
Tactical Combat Casualty Care (TC3) requires responders to connect visual observations of injuries and interventions with established clinical guidance. Developing vision-language models to support this process requires supervision that links visible evidence to traceable…
5 Oct 2026
Low-Rank Adaptation (LoRA) has become a standard approach for parameter-efficient fine-tuning, yet a fundamental practical question remains unresolved: how should the adapter rank be chosen? An overly small rank may lead to a poorly conditioned optimization landscape, whereas an…
5 Oct 2026
We present a new perspective on the problem of likelihood approximation within the framework of simulation-based inference that promotes scalable and controllable simulation routines for large-scale data analysis, allows efficient parameter space exploration or smooth…
5 Oct 2026
As technology scales to smaller nodes, increasing current densities make electromigration (EM) one of the dominant reliability challenges in on-chip interconnects. Accurate transient stress analysis is needed to identify wires susceptible to EM degradation, but applying…
5 Oct 2026
An inaccurate expert can still provide useful information after correction. We study online learning to defer in which the learner chooses an expert and fixes a correction function before purchasing its answer, then applies that function to the answer received.
5 Oct 2026
A recurring design principle in modern optimizers is to decouple update magnitude from the raw gradient norm, yet its consequences for learning-curve and resource scaling remain unclear.
5 Oct 2026
We develop and test a theory of language model representations in which there exist atomic features. Our main theoretical insight is that in such a model, sparse dictionaries (e.g., SAEs) of increasing size recover an increasing prefix of the most prevalent atoms in the training…
5 Oct 2026
Representations of translated sentences are similar in the inner layers of multilingual language models -- an observation connected to the platonic representation hypothesis, yet unexplained theoretically.
5 Oct 2026
Deterministic benchmark scores show that an agent received credit, but not whether that credit was earned, reported honestly, or would hold on a second run. We introduce a Trust Layer for Agent Evaluation, an additive post-hoc framework that reports, beside each recorded score,…
5 Oct 2026
As AI agents increasingly tackle complex repository-level coding tasks, distributing work across multiple agents is a natural way to scale beyond the capabilities of a single agent.
4 Oct 2026
An electromagnetic inversion scheme that integrates stochastic optimization (STO) and plug-and-play (PNP) regularization into contrast-source inversion (CSI), termed STO-PNP-CSI, is developed.