4 Sep 2026
Large language models (LLMs) show potential for medical tasks, but their single-turn question-answer format does not reflect how clinical diagnosis is performed in practice. As a result, they remain limited in complex diagnostic settings.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,381 papers.
4 Sep 2026
Large language models (LLMs) show potential for medical tasks, but their single-turn question-answer format does not reflect how clinical diagnosis is performed in practice. As a result, they remain limited in complex diagnostic settings.
4 Sep 2026
Multilingual language models develop shared cross-lingual representations, and various interpretability methods claim to quantify this sharing. These methods have been developed largely in isolation, and when they disagree, it is unclear whether the disagreement reflects a…
4 Sep 2026
Recent structured RAG methods leverage tree- or graph-based reasoning structures to improve multi-hop QA. However, they face key limitations in evidence-intensive QA, where answering a question requires synthesizing information scattered across dozens or even hundreds of…
4 Sep 2026
We present a unified reinforcement-learning (RL) framework that discovers compact parametrized quantum circuits (PQCs) for data-scarce device modeling. A graph neural network (GNN) policy optimized by proximal policy optimization (PPO) searches circuit architectures using…
4 Sep 2026
Large language models (LLMs) show strong reasoning ability, but their explanations can remain inconsistent, weakly grounded, or difficult to verify. We propose a verifier-guided explainable reasoning framework for transparent educational question answering that combines…
4 Sep 2026
UAV image collections contain spatially and temporally related frames, yet semantic-segmentation benchmarks commonly split them at image level. Such splitting can place samples from one acquisition in both model development and testing, obscuring transfer to a genuinely new…
4 Sep 2026
Mixture-of-Experts (MoE) architectures provide an efficient paradigm for scaling large language models (LLMs), yet fixed top-k routing activates the same number of expert slots for every token, causing substantial redundant computation.
3 Sep 2026
Chain-of-thought (CoT) reasoning improves large reasoning models (LRMs) on complex tasks but often produces long, redundant traces. Recent training-free early-exit methods shorten these traces by choosing an intermediate point to stop reasoning.
3 Sep 2026
Modern AI agent harnesses expose lifecycle hooks that bind shell commands to runtime events such as session start, tool calls, and file edits. These commands run with host privileges yet ship as lifecycle-hook configuration and may fire at times the LLM never observes.
3 Sep 2026
A critical challenge in deploying Large Language Models (LLMs) is developing reliable mechanisms to estimate their confidence, enabling systems to determine when to trust model outputs versus seek human intervention.
3 Sep 2026
Multi-agent AI science ecosystems rely on agents possessing tools that allow them to communicate, coordinate, and build on each other's work. Yet this shared infrastructure can also introduce vulnerabilities by creating a substrate for the contagious spread of unintended and…
3 Sep 2026
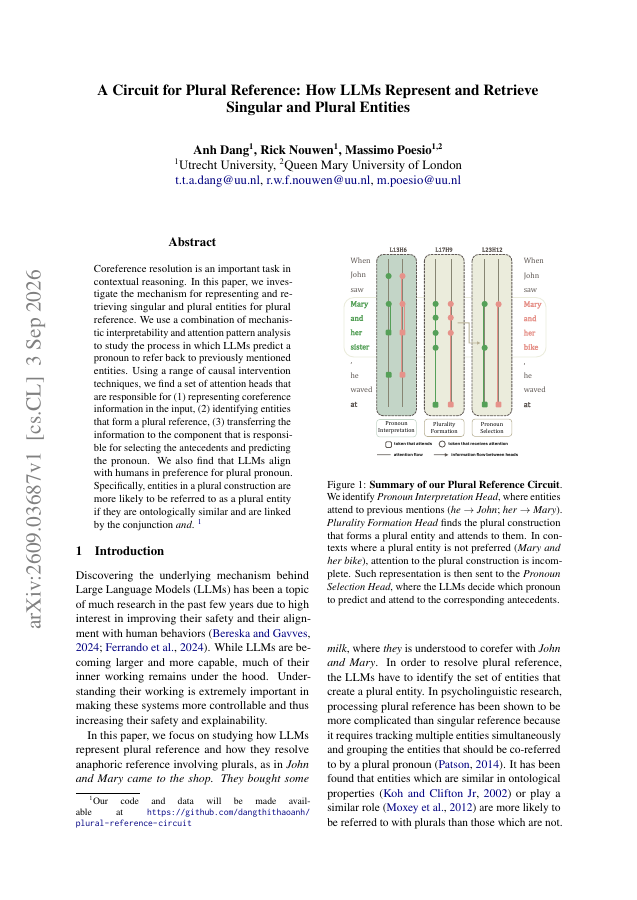
Coreference resolution is an important task in contextual reasoning. In this paper, we investigate the mechanism for representing and retrieving singular and plural entities for plural reference.
3 Sep 2026
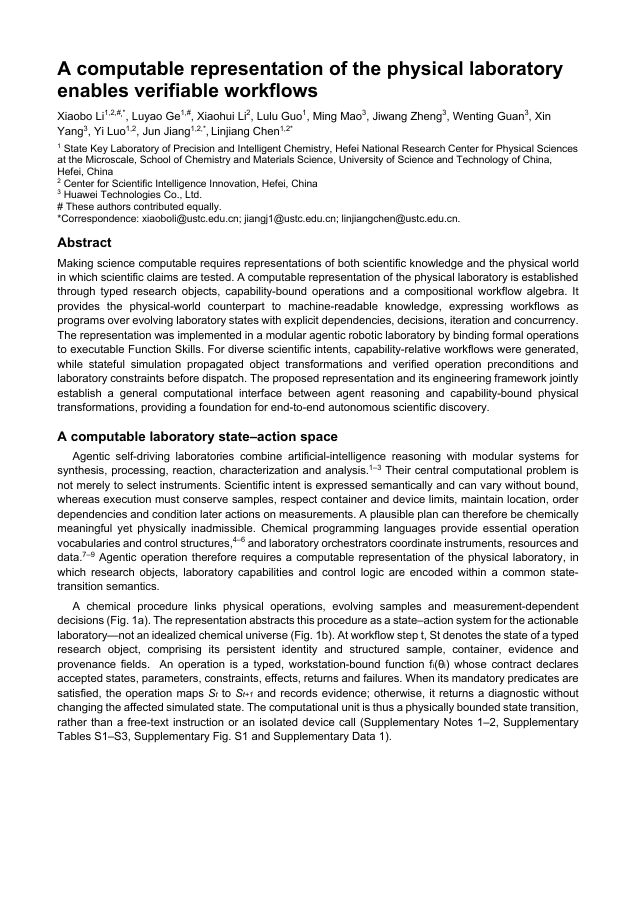
Making science computable requires representations of both scientific knowledge and the physical world in which scientific claims are tested. A computable representation of the physical laboratory is established through typed research objects, capability-bound operations and a…
3 Sep 2026
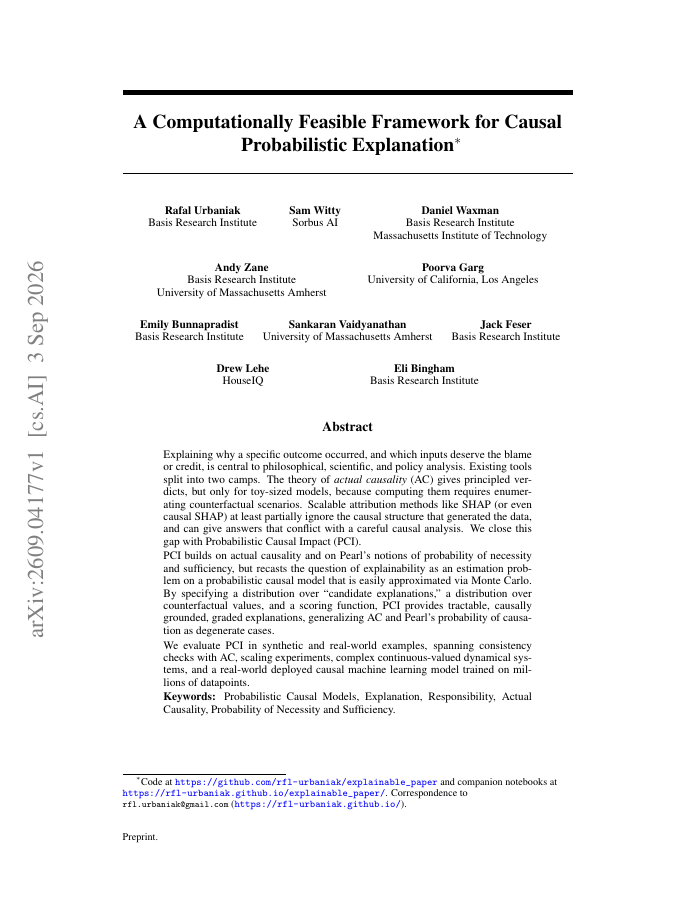
Explaining why a specific outcome occurred, and which inputs deserve the blame or credit, is central to philosophical, scientific, and policy analysis. Existing tools split into two camps.
3 Sep 2026
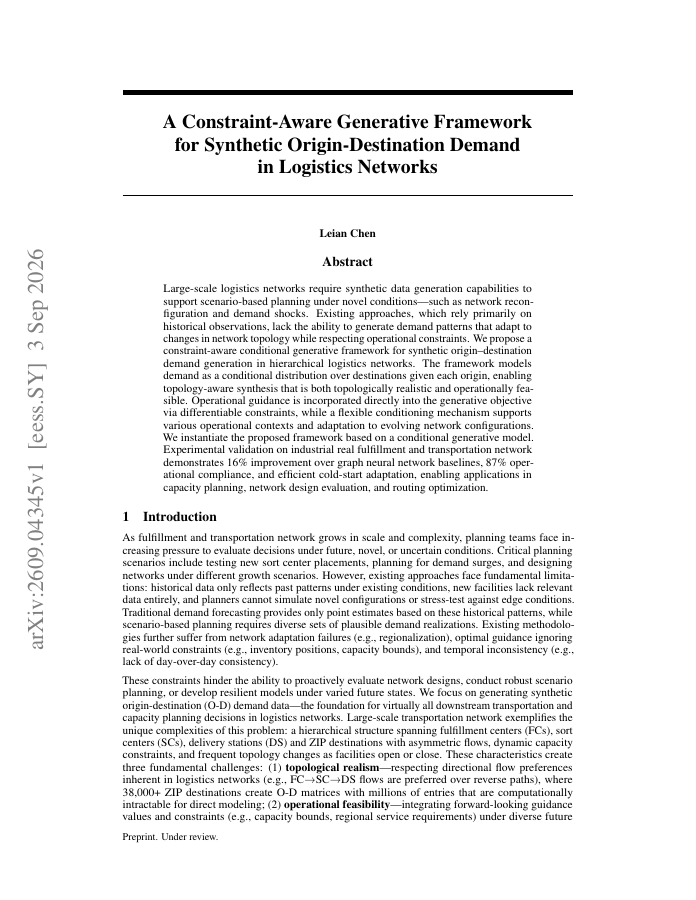
Large-scale logistics networks require synthetic data generation capabilities to support scenario-based planning under novel conditions-such as network reconfiguration and demand shocks.
3 Sep 2026
Every engineered fill is specified by a maximum dry density and an optimum moisture content. Each determination needs a full Proctor test. Published correlations rest on one to four hundred specimens, usually from one laboratory at one compactive energy, and are seldom released.
3 Sep 2026
Quantile treatment effects (QTEs) measure the effect of a treatment on the distribution of an outcome, and their estimation at extreme quantile levels is of central interest in applications where the target quantiles lie far beyond the range of the data.
3 Sep 2026
This paper presents a low-cost, open experimental platform for research in end-to-end autonomous driving with miniature Ackermann vehicles. The platform combines a physical vehicle, a printed urban track, data collection tools, trajectory registration, and a Webots digital twin,…
3 Sep 2026
For every coherent and sufficiently expressive finite syntactic system S, we prove the existence of at least one theorem that S cannot produce autonomously. The result is a metatheorem: it proves the existence of a theorem, and applies to every finite syntactic system - security…
3 Sep 2026
Energy consumption is one of the largest operational expenditure items for mobile network operators, yet site-level energy inefficiencies such as faulty cooling controllers, idle radio equipment, and parasitic auxiliary loads often remain undetected because no ground-truth…
3 Sep 2026
Artificial intelligence (AI) teaching assistants powered by large language models (LLMs) offer scalable educational support but often provide limited personalization. This study presents a prompt-engineering-based framework for personalizing general-purpose LLM/RAG-based AI…
3 Sep 2026
We introduce a lightweight Quantum Prototypical Recurrent Unit (QPRU) that requires significantly fewer parameters than both classical recurrent architectures, such as Long Short- Term Memory (LSTM) and Gated Recurrent Unit (GRU), and quantum variants, including Quantum LSTM…
3 Sep 2026
Large language models (LLMs) are increasingly used for consequential decisions, making their explanations an important tool for auditing model behavior. Unfortunately, these explanations can be unfaithful, failing to reflect the actual reasoning underlying the model's decisions.
3 Sep 2026
Large language models (LLMs) are increasingly used to annotate cultural texts at scales that are impractical for human coders. However, before their outputs are treated as measurements of latent social constructs, it is necessary to establish whether those measurements are…