1 Feb 2026
We consider the problem of heteroskedastic generalized linear bandits (GLBs) with adversarial corruptions, which subsumes heteroskedastic linear bandits and logistic/Poisson bandits, in the presence of adversarial corruptions.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,422 papers.
1 Feb 2026
We consider the problem of heteroskedastic generalized linear bandits (GLBs) with adversarial corruptions, which subsumes heteroskedastic linear bandits and logistic/Poisson bandits, in the presence of adversarial corruptions.
1 Feb 2026
Flow-based generative models can be viewed through a physics lens: sampling transports a particle from noise to data by integrating a learned velocity field, and each sample corresponds to a trajectory with its own dynamical effort.
1 Feb 2026
Fine-tuning Large Language Models (LLMs) with Low-Rank Adaptation (LoRA) offers a resource-efficient way to personalize or specialize. However, LoRA is highly sensitive to hyperparameter choices, and exhaustive hyperparameter search is computationally expensive.
1 Feb 2026
Pre-trained vision encoders like DINOv2 have demonstrated exceptional performance on unimodal tasks. However, we observe that their features are poorly aligned across different visual modalities.
1 Feb 2026
In general reinforcement learning, all established optimal agents, including AIXI, are model-based, explicitly maintaining and using environment models. This paper introduces Universal AI with Q-Induction (AIQI), the first model-free agent proven to be asymptotically…
1 Feb 2026
Safe UAV emergency landing requires more than just identifying flat terrain; it demands understanding complex semantic risks (e.g., crowds, temporary structures) invisible to traditional geometric sensors.
1 Feb 2026
Preconditioning is a common method applied to modify Markov chain Monte Carlo algorithms with the goal of making them more efficient. In practice it is often extremely effective, even when the preconditioner is learned from the chain.
1 Feb 2026
Objective: This study develops and validates a patient simulation framework that aligns with the National Institute of Standards and Technology AI Risk Management Framework MAP and MEASURE functions, providing an empirical basis for identifying and characterizing performance…
1 Feb 2026
Differentiating through the solution of a quadratic program (QP) is a central problem in differentiable optimization. Most existing approaches differentiate through the Karush--Kuhn--Tucker (KKT) system, but their computational cost and numerical robustness can degrade at scale.
1 Feb 2026
LLM self-explanations are often presented as a promising tool for AI oversight, yet their faithfulness to the model's true reasoning process is poorly understood. Existing faithfulness metrics have critical limitations, typically relying on identifying unfaithfulness via…
1 Feb 2026
Training data leakage from Large Language Models (LLMs) raises serious concerns related to privacy, security, and copyright compliance. A central challenge in assessing this risk is distinguishing prefix-specific memorization of training data from the generation of statistically…
1 Feb 2026
Automated methods for discovering mechanistic simulator models from observational data offer a promising path toward accelerating scientific progress. Such methods often take the form of agentic-style iterative workflows that repeatedly propose and revise candidate models by…
1 Feb 2026
Diffusion models trained on different, non-overlapping subsets of a dataset often produce strikingly similar outputs when given the same noise seed. We trace this consistency to a simple linear effect: the shared Gaussian statistics across splits already predict much of the…
1 Feb 2026
Sparse Mixture-of-Experts (SMoE) architectures are increasingly used to scale large language models efficiently, delivering strong accuracy under fixed compute budgets. However, SMoE models often suffer from severe load imbalance across experts, where a small subset of experts…
1 Feb 2026
Transformer models systematically favor certain token positions, yet the architectural origins of this position bias remain poorly understood. This bias is closely connected to the Lost-in-the-Middle phenomenon, where models underutilize information placed in the middle of the…
1 Feb 2026
We propose a novel swap-adversarial framework that mitigates high inter-subject variability and the high-dimensional low-sample-size problem in electrocorticography (ECoG) data.
1 Feb 2026
Large language models (LLMs) are increasingly being used in a zero-shot (generative) fashion to assess mental health conditions, yet we have limited knowledge on what factors affect their accuracy.
1 Feb 2026
Iterative self-improvement fine-tunes an autoregressive large language model (LLM) on reward-verified outputs generated by the LLM itself. In contrast to the empirical success of self-improvement, the theoretical foundation of this generative, iterative procedure in a practical,…
1 Feb 2026
Training large-scale generative models is resource-intensive and relies heavily on heuristic dataset weighting. We address two fundamental questions: Can we train Large Language Models (LLMs) modularly, combining small, domain-specific experts to match monolithic performance,…
1 Feb 2026
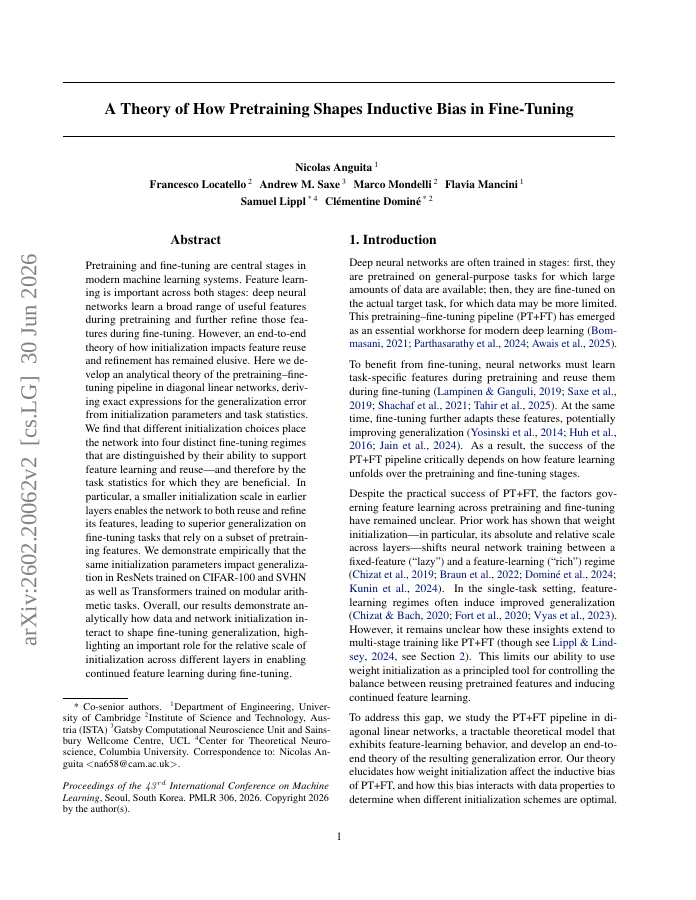
Pretraining and fine-tuning are central stages in modern machine learning systems. In practice, feature learning plays an important role across both stages: deep neural networks learn a broad range of useful features during pretraining and further refine those features during…
1 Feb 2026
We formulate plasticity as target-dependent, finite-horizon reachability under history-dependent dynamics, using standard minimum-energy control theory. An extended state includes parameters and internal variables that affect future updates.
1 Feb 2026
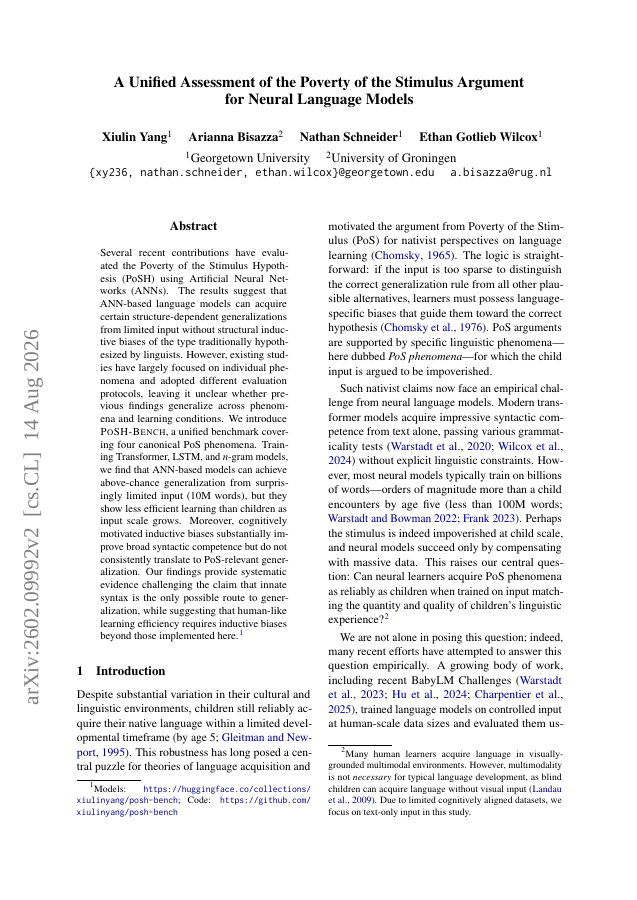
Several recent contributions have evaluated the Poverty of the Stimulus Hypothesis (PoSH) using Artificial Neural Networks (ANNs). The results suggest that ANN-based language models can acquire certain structure-dependent generalizations from limited input without structural…
1 Feb 2026
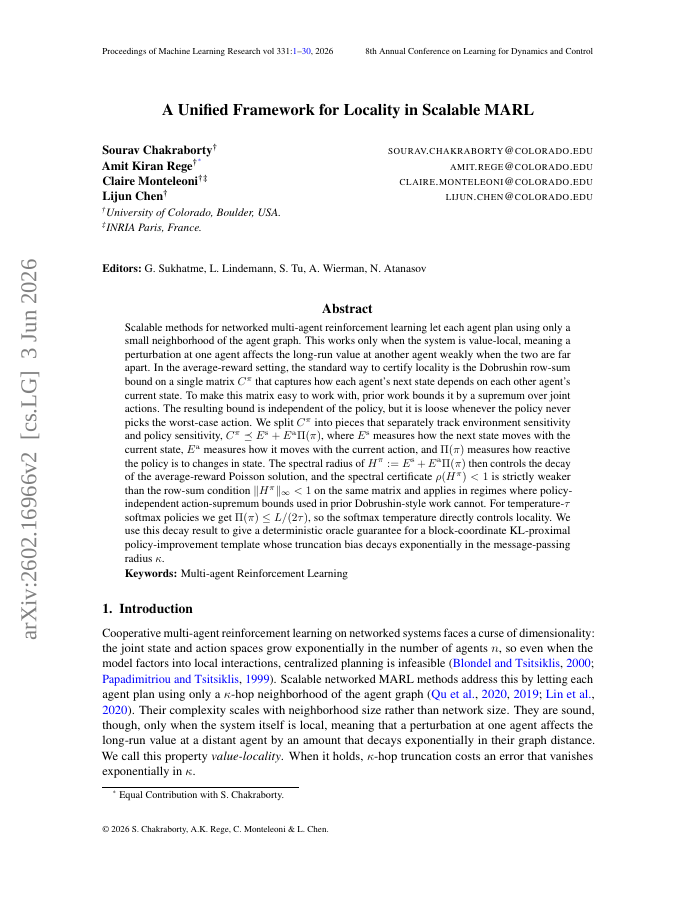
Scalable methods for networked multi-agent reinforcement learning let each agent plan using only a small neighborhood of the agent graph. This works only when the system is value-local, meaning a perturbation at one agent affects the long-run value at another agent weakly when…
1 Feb 2026
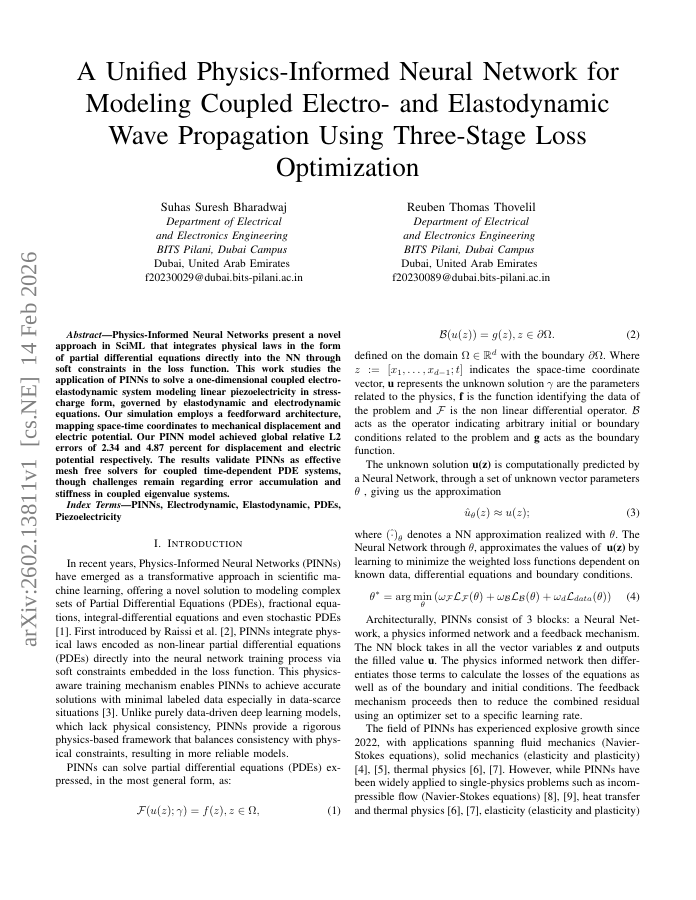
Physics-Informed Neural Networks present a novel approach in SciML that integrates physical laws in the form of partial differential equations directly into the NN through soft constraints in the loss function.