The Illusion of Visual Tool-Use: A Causal Audit of Thinking with Images
6 Aug 2026
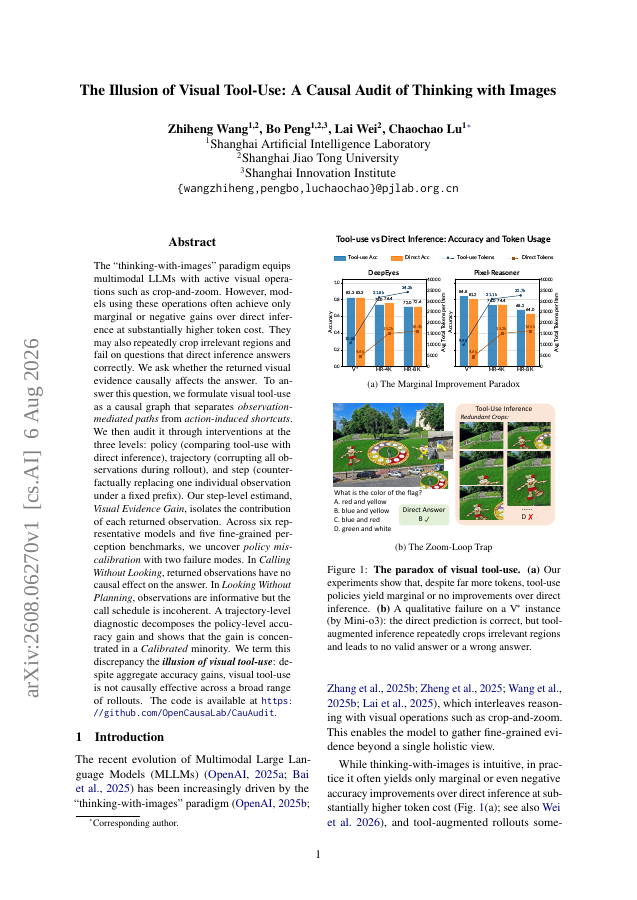
The "thinking-with-images" paradigm equips multimodal LLMs with active visual operations such as crop-and-zoom. However, models using these operations often achieve only marginal or negative gains over direct inference at substantially higher token cost.
60.0/h