16 Sep 2026
Mixture-of-experts (MoE) inference on consumer hardware is bounded by weight memory: a 35B-class model is 19.5GB at 4-bit, and sparsity shrinks the compute per token, not the bytes that must be held.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,663 papers.
16 Sep 2026
Mixture-of-experts (MoE) inference on consumer hardware is bounded by weight memory: a 35B-class model is 19.5GB at 4-bit, and sparsity shrinks the compute per token, not the bytes that must be held.
17 Sep 2026
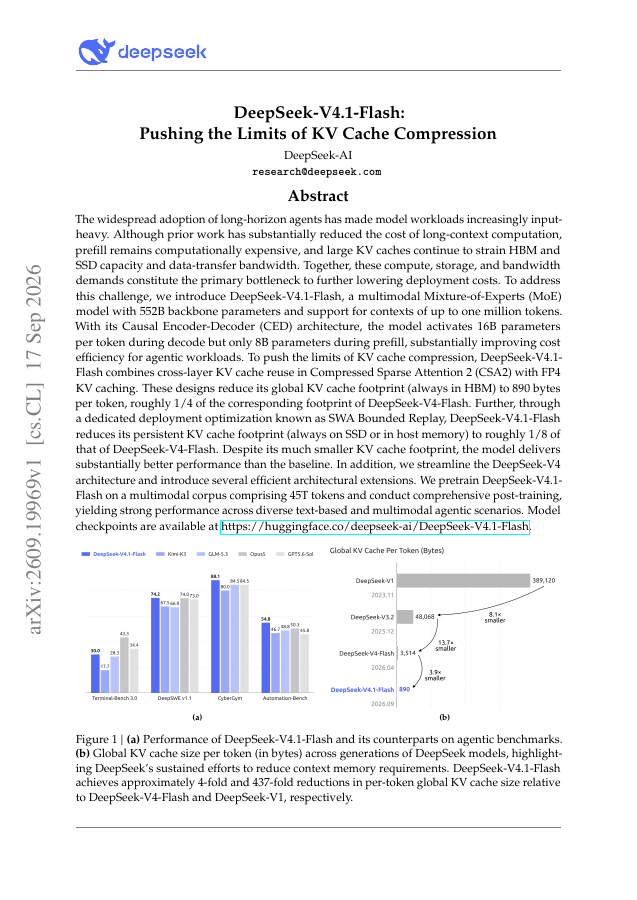
The widespread adoption of long-horizon agents has made model workloads increasingly input-heavy. Although prior work has substantially reduced the cost of long-context computation, prefill remains computationally expensive, and large KV caches continue to strain HBM and SSD…
15 Oct 2026
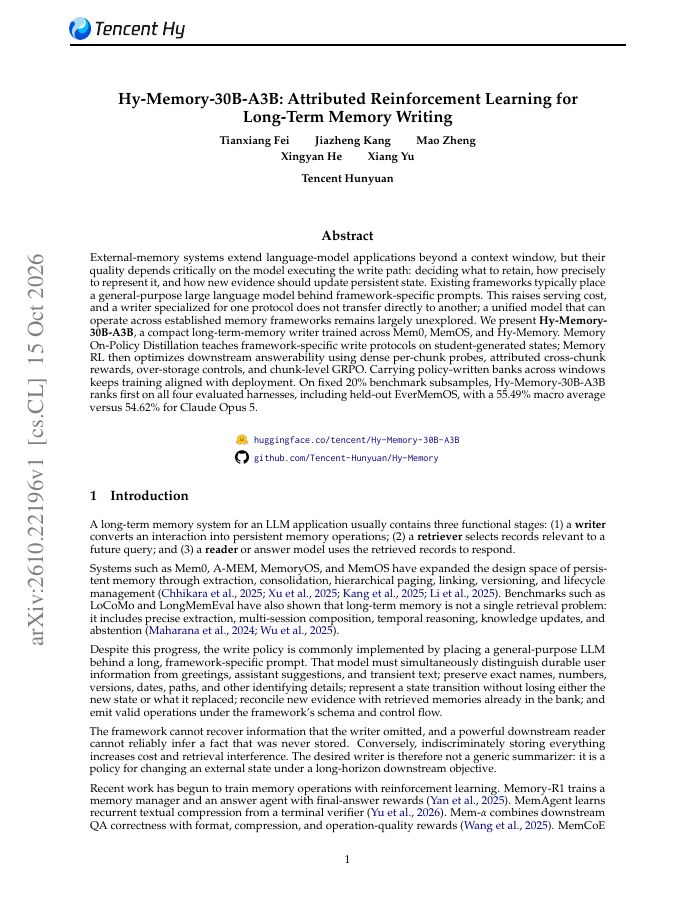
External-memory systems extend language-model applications beyond a context window, but their quality depends critically on the model executing the write path: deciding what to retain, how precisely to represent it, and how new evidence should update persistent state.
2 Jun 2026
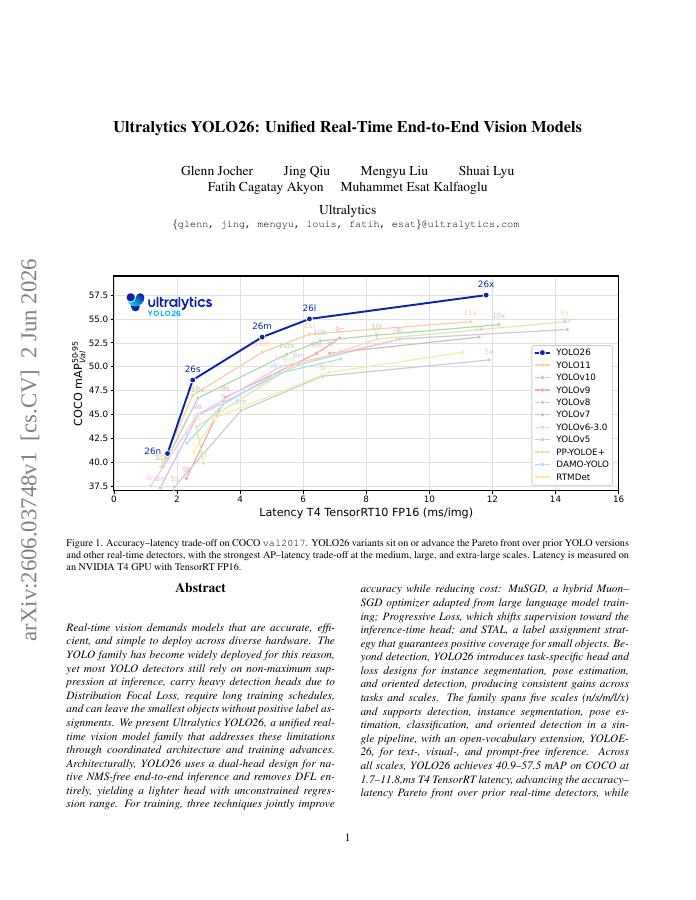
Real-time vision demands models that are accurate, efficient, and simple to deploy across diverse hardware. The YOLO family has become widely deployed for this reason, yet most YOLO detectors still rely on non-maximum suppression at inference, carry heavy detection heads due to…
16 Oct 2026
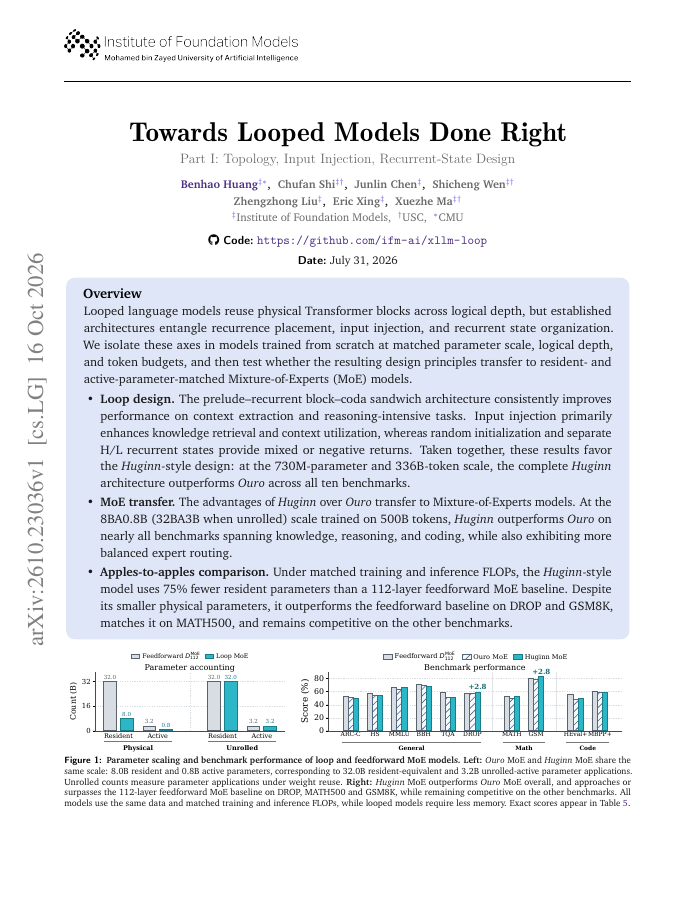
Looped language models reuse physical Transformer blocks across logical depth, but established architectures entangle recurrence placement, input injection, and recurrent state organization.
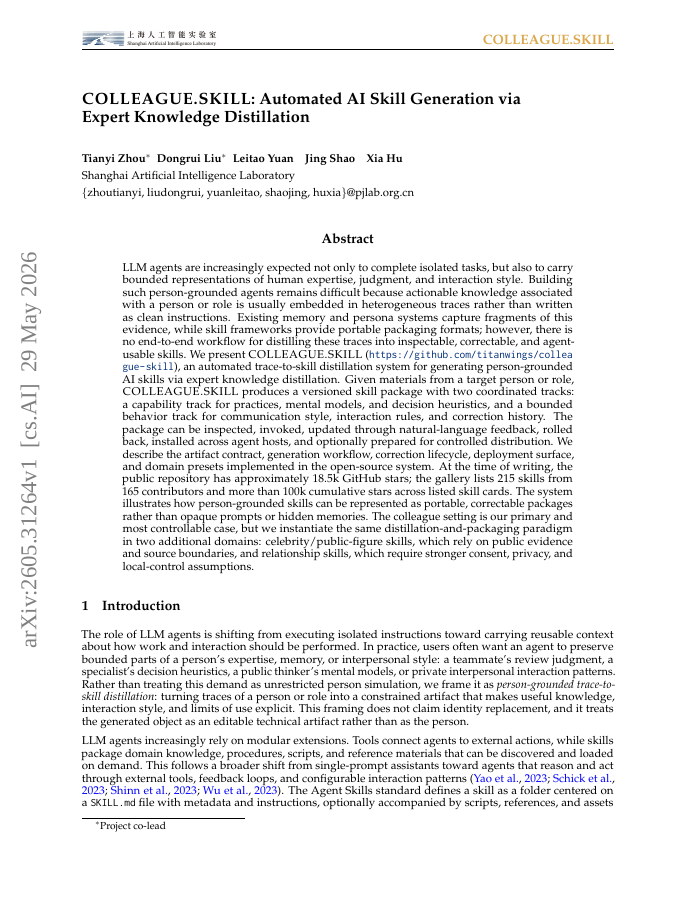
29 May 2026
LLM agents are increasingly expected not only to complete isolated tasks, but also to carry bounded representations of human expertise, judgment, and interaction style. Building such person-grounded agents remains difficult because actionable knowledge associated with a person…
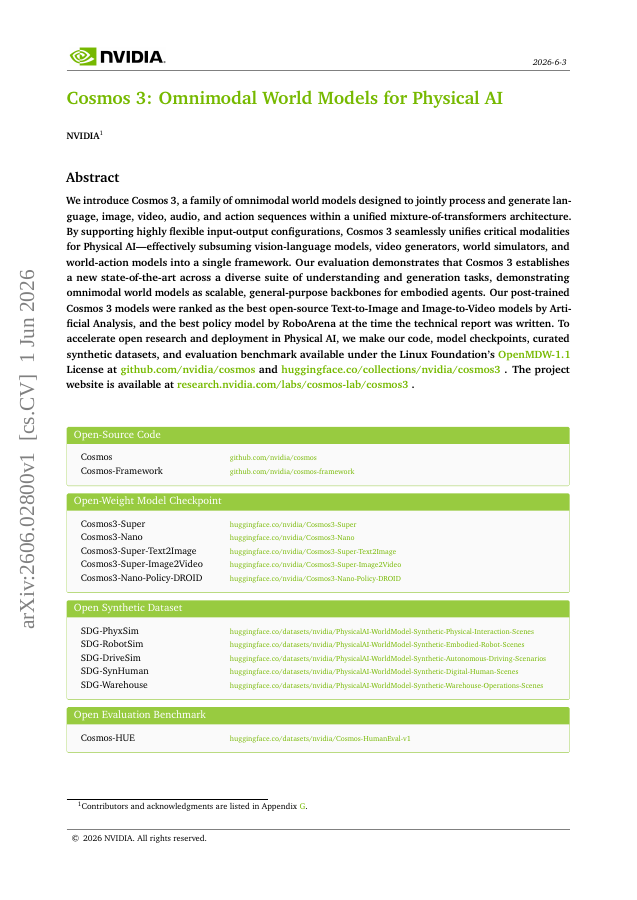
1 Jun 2026
We introduce Cosmos 3, a family of omnimodal world models designed to jointly process and generate language, image, video, audio, and action sequences within a unified mixture-of-transformers architecture.
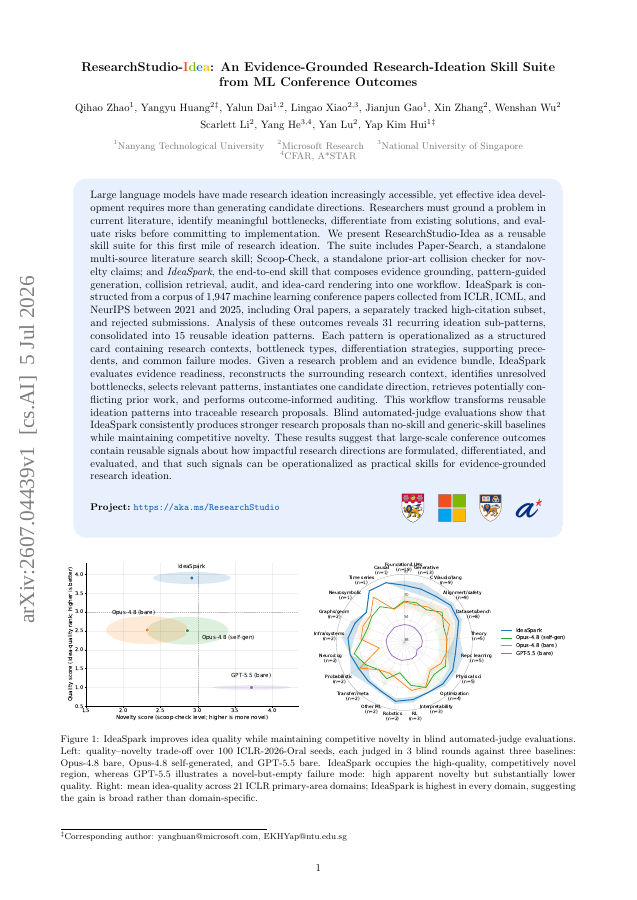
5 Jul 2026
Large language models have made research ideation increasingly accessible, yet effective idea development requires more than generating candidate directions. Researchers must ground a problem in current literature, identify meaningful bottlenecks, differentiate from existing…
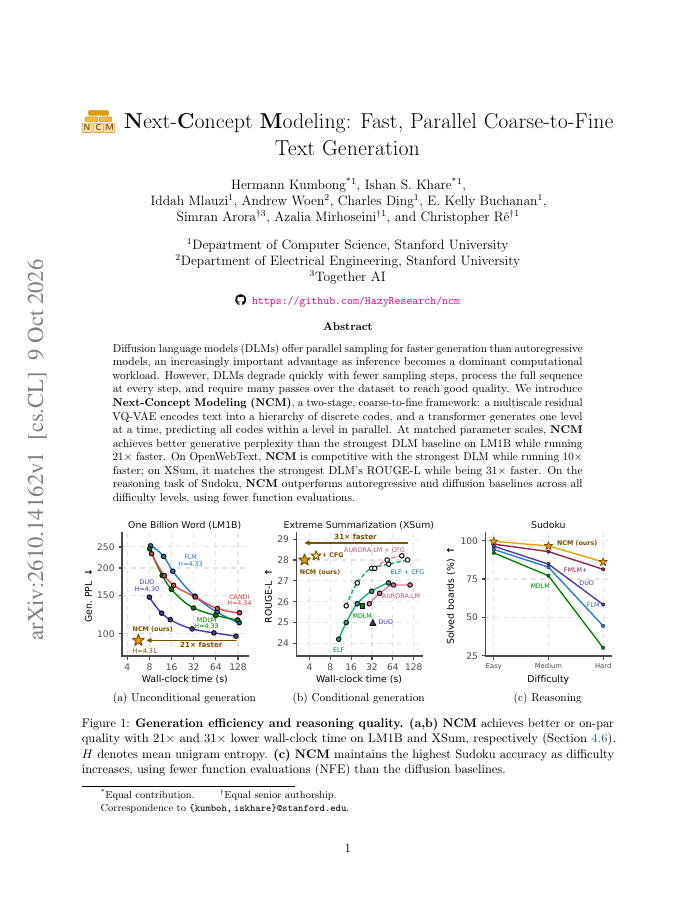
9 Oct 2026
Diffusion language models (DLMs) offer parallel sampling for faster generation than autoregressive models, an increasingly important advantage as inference becomes a dominant computational workload.
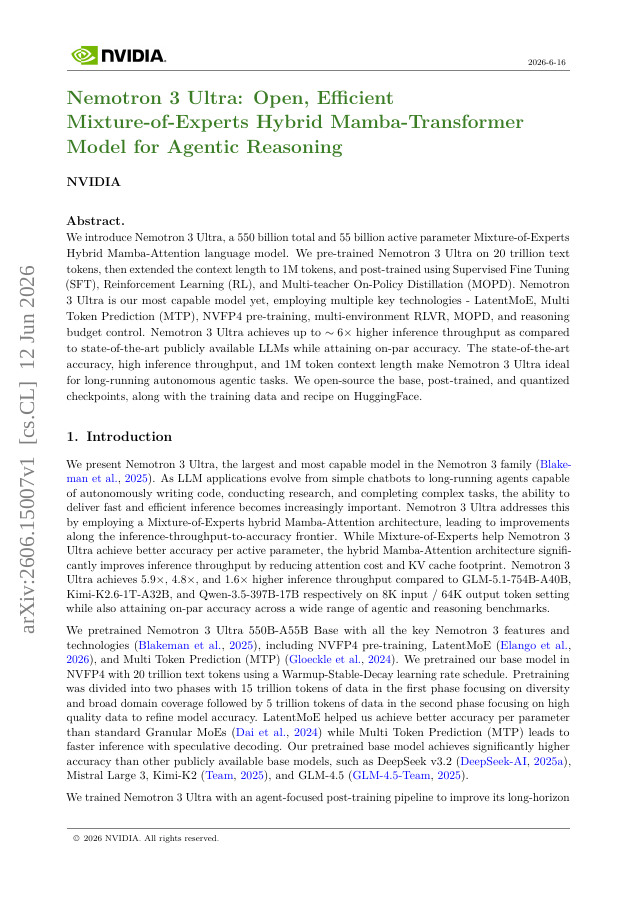
12 Jun 2026
We introduce Nemotron 3 Ultra, a 550 billion total and 55 billion active parameter Mixture-of-Experts Hybrid Mamba-Attention language model. We pre-trained Nemotron 3 Ultra on 20 trillion text tokens, then extended the context length to 1M tokens, and post-trained using…
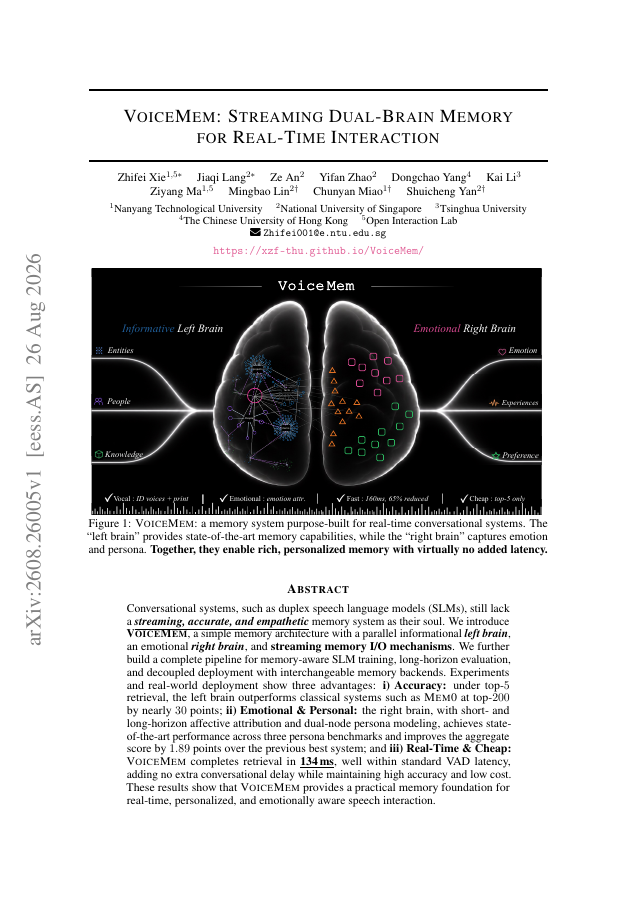
26 Aug 2026
Conversational systems, such as duplex speech language models (SLMs), still lack a streaming, accurate, and empathetic memory system as their soul. We introduce VoiceMem, a simple memory architecture with a parallel informational left brain, an emotional right brain, and…
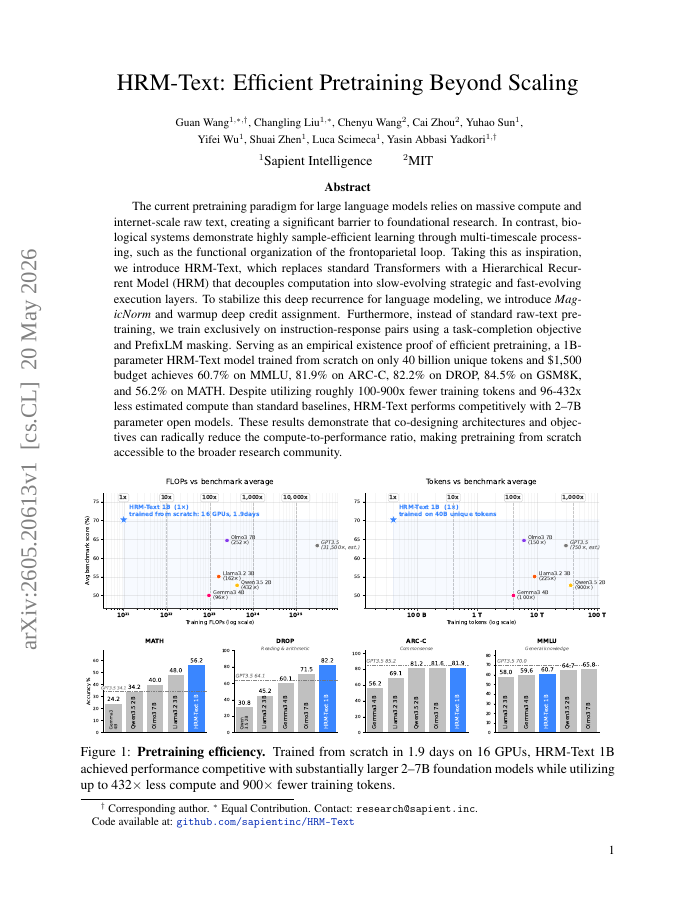
Guan Wang, Changling Liu, Chenyu Wang et al. · 20 May 2026
The current pretraining paradigm for large language models relies on massive compute and internet-scale raw text, creating a significant barrier to foundational research.
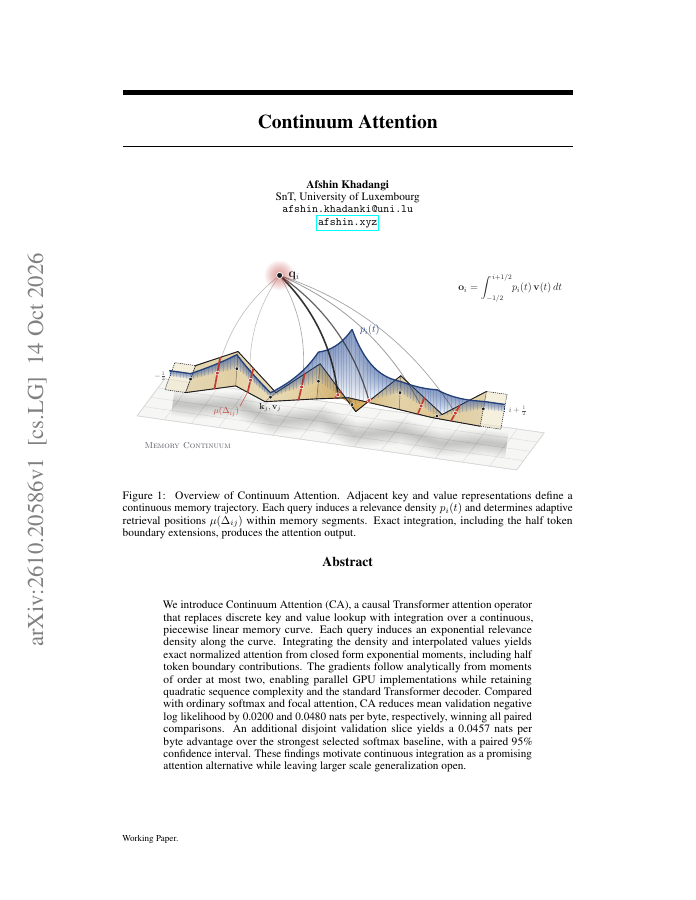
14 Oct 2026
We introduce Continuum Attention (CA), a causal Transformer attention operator that replaces discrete key and value lookup with integration over a continuous, piecewise linear memory curve. Each query induces an exponential relevance density along the curve.
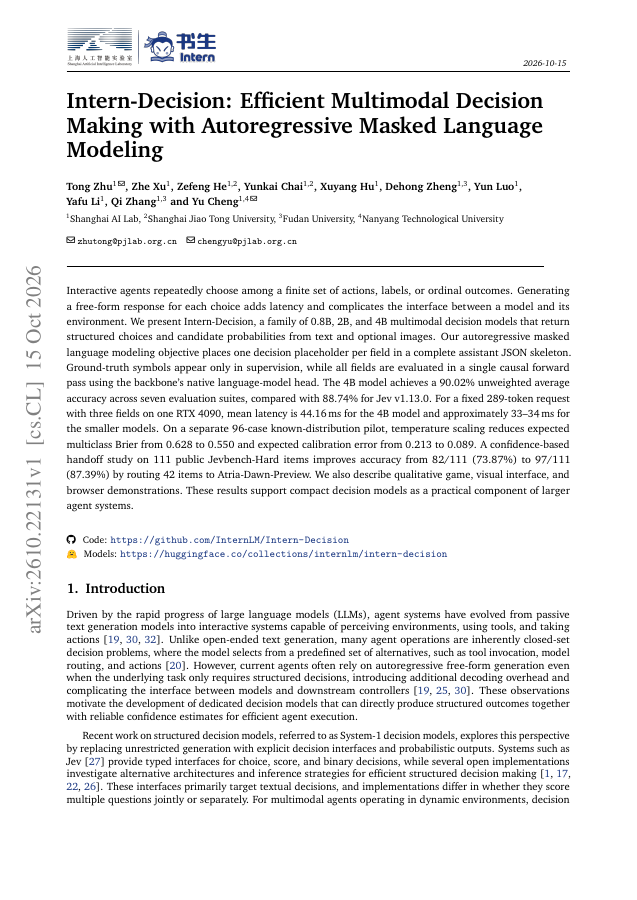
15 Oct 2026
Interactive agents repeatedly choose among a finite set of actions, labels, or ordinal outcomes. Generating a free-form response for each choice adds latency and complicates the interface between a model and its environment.
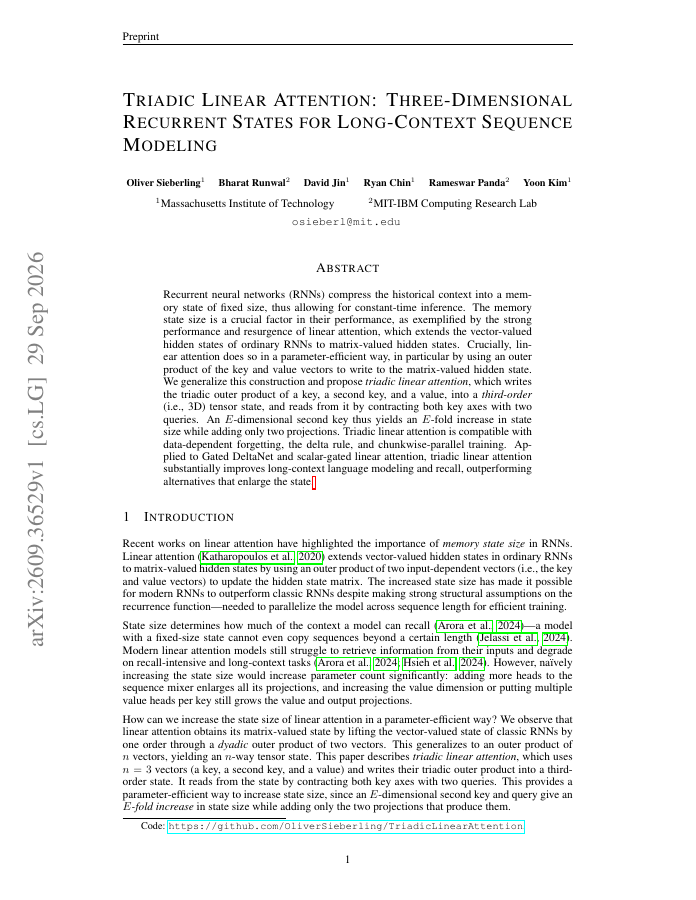
29 Sep 2026
Recurrent neural networks (RNNs) compress the historical context into a memory state of fixed size, thus allowing for constant-time inference. The memory state size is a crucial factor in their performance, as exemplified by the strong performance and resurgence of linear…
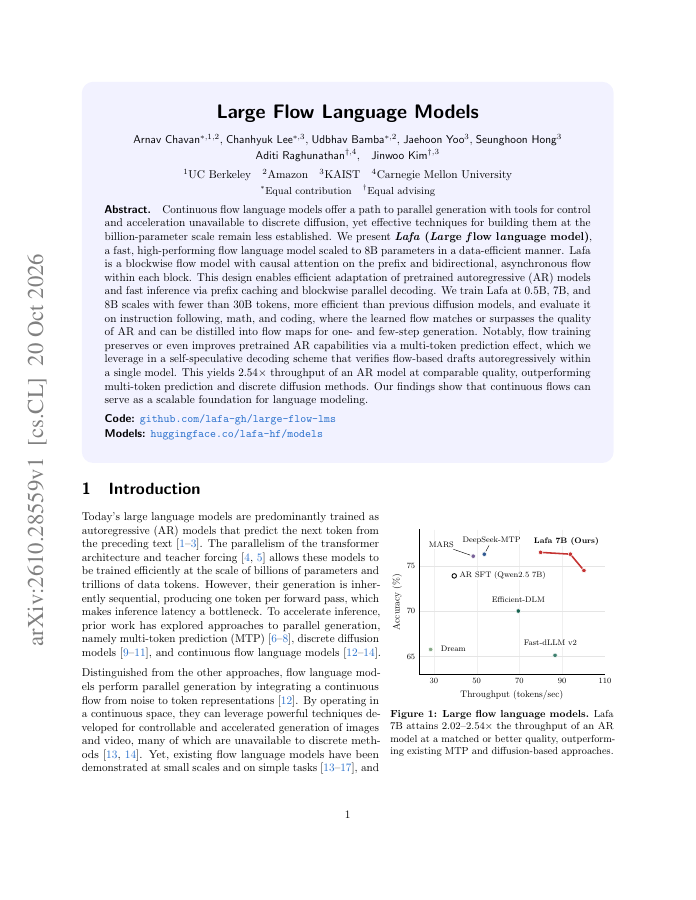
20 Oct 2026
Continuous flow language models offer a path to parallel generation with tools for control and acceleration unavailable to discrete diffusion, yet effective techniques for building them at the billion-parameter scale remain less established.
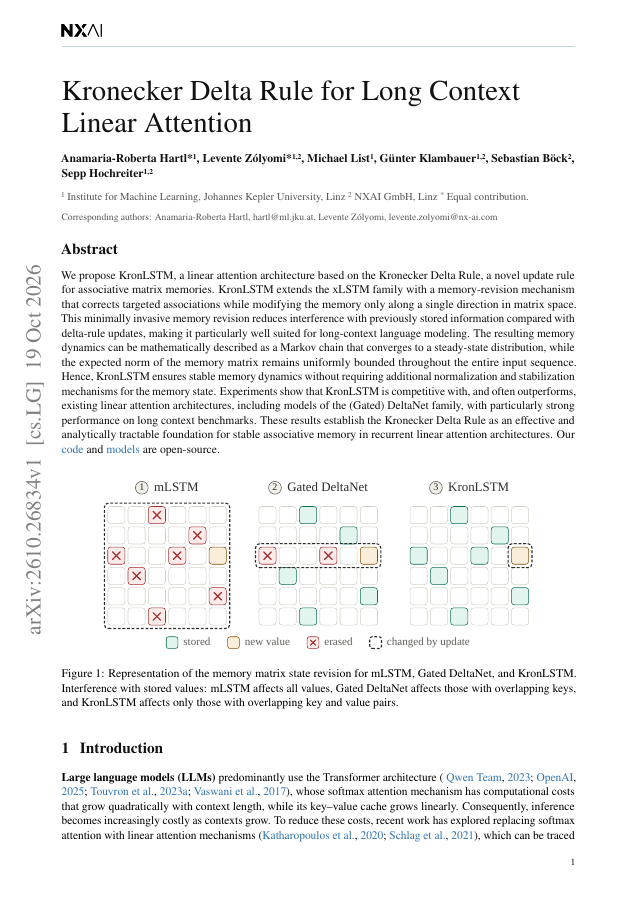
19 Oct 2026
We propose KronLSTM, a linear attention architecture based on the Kronecker Delta Rule, a novel update rule for associative matrix memories. KronLSTM extends the xLSTM family with a memory-revision mechanism that corrects targeted associations while modifying the memory only…
19 Oct 2026
Many modern language models have adopted hybrid architectures that incorporate both linear-time recurrence and softmax attention. Modern recurrence layers provide a highly expressive mixing mechanism while ensuring high throughput by compressing contextual information into a…