9 Oct 2026
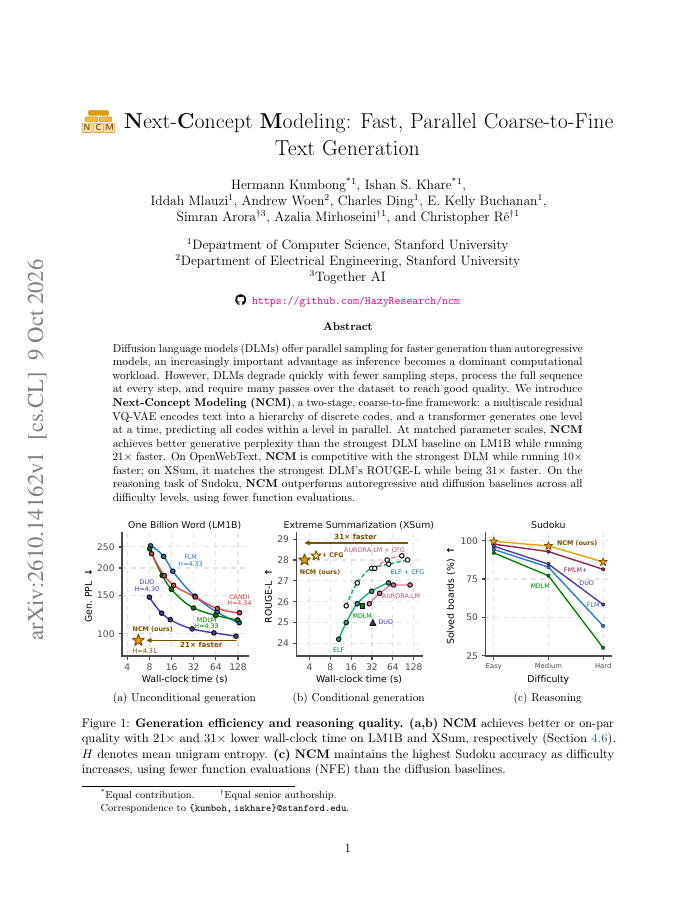
Diffusion language models (DLMs) offer parallel sampling for faster generation than autoregressive models, an increasingly important advantage as inference becomes a dominant computational workload.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,688 papers.
9 Oct 2026
Diffusion language models (DLMs) offer parallel sampling for faster generation than autoregressive models, an increasingly important advantage as inference becomes a dominant computational workload.
15 Oct 2026
External-memory systems extend language-model applications beyond a context window, but their quality depends critically on the model executing the write path: deciding what to retain, how precisely to represent it, and how new evidence should update persistent state.
19 Oct 2026
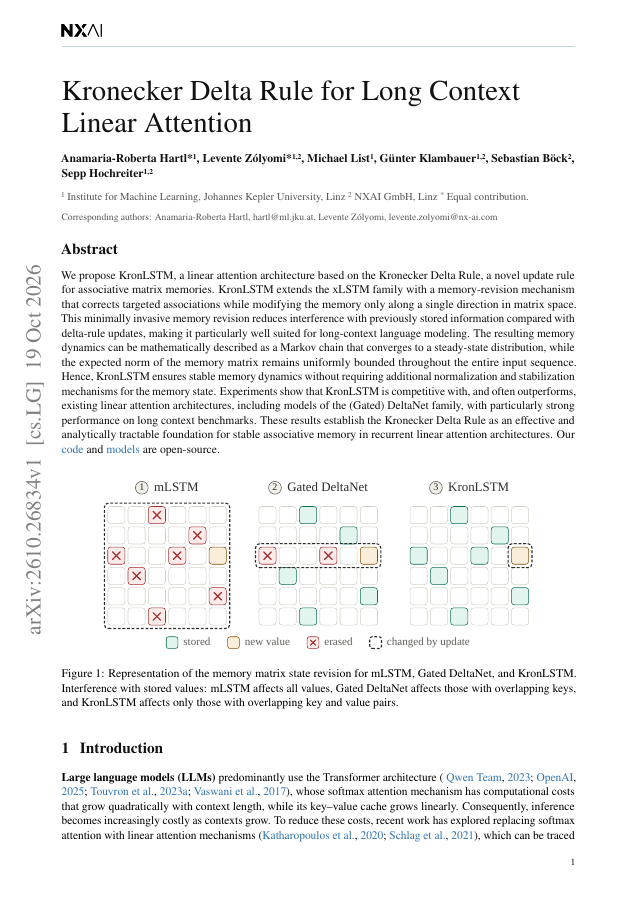
We propose KronLSTM, a linear attention architecture based on the Kronecker Delta Rule, a novel update rule for associative matrix memories. KronLSTM extends the xLSTM family with a memory-revision mechanism that corrects targeted associations while modifying the memory only…
20 Oct 2026
Continuous flow language models offer a path to parallel generation with tools for control and acceleration unavailable to discrete diffusion, yet effective techniques for building them at the billion-parameter scale remain less established.
20 Oct 2026
Deep research systems iteratively plan, gather evidence, synthesize, and revise, making end-to-end latency a key bottleneck for interactive use. Almost all production systems are built on autoregressive (AR) language models and inherit left-to-right decoding in planning and…
20 Oct 2026
Diffusion language models form answers through a sequence of revisable continuous states, but multi-agent systems usually discard those states and make agents communicate only after decoding text.
21 Oct 2026
Uniform diffusion language models (UDLMs) generate text by iteratively denoising sequences of ordinary vocabulary tokens, any of which may be corrupted and subsequently revised.