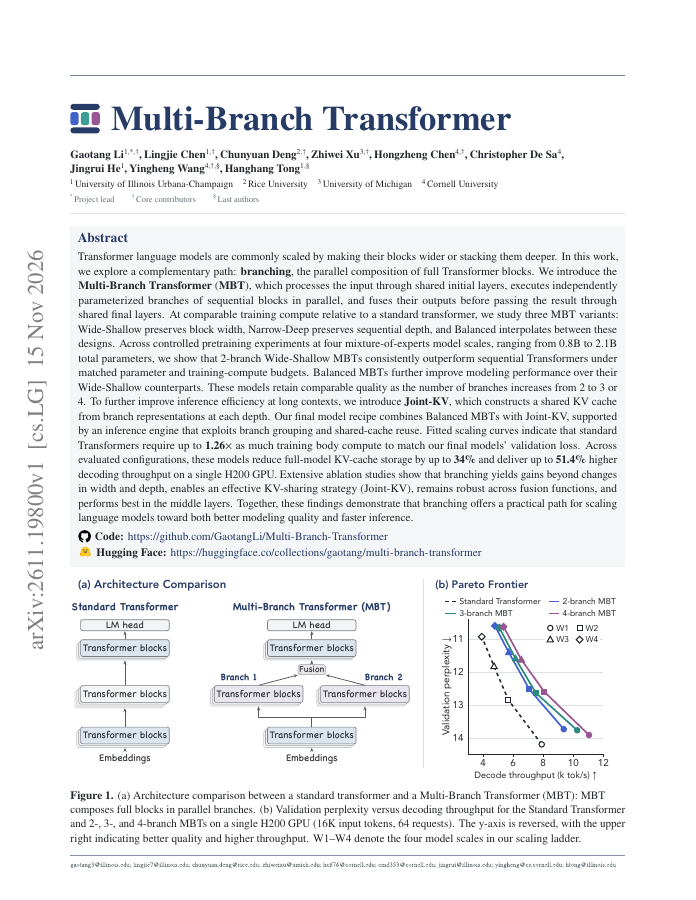
Multi-Branch Transformer
15 Nov 2026
Transformer language models are commonly scaled by making their blocks wider or stacking them deeper. In this work, we explore a complementary path: branching, the parallel composition of full Transformer blocks.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,997 papers.
15 Nov 2026
Transformer language models are commonly scaled by making their blocks wider or stacking them deeper. In this work, we explore a complementary path: branching, the parallel composition of full Transformer blocks.
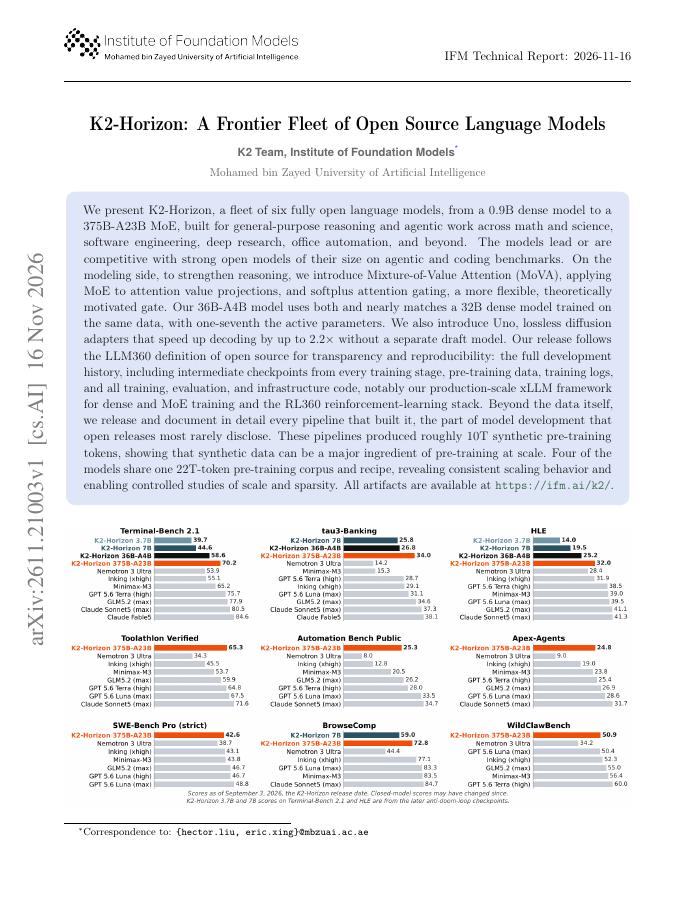
16 Nov 2026
We present K2-Horizon, a fleet of six fully open language models, from a 0.9B dense model to a 375B-A23B MoE, built for general-purpose reasoning and agentic work across math and science, software engineering, deep research, office automation, and beyond.
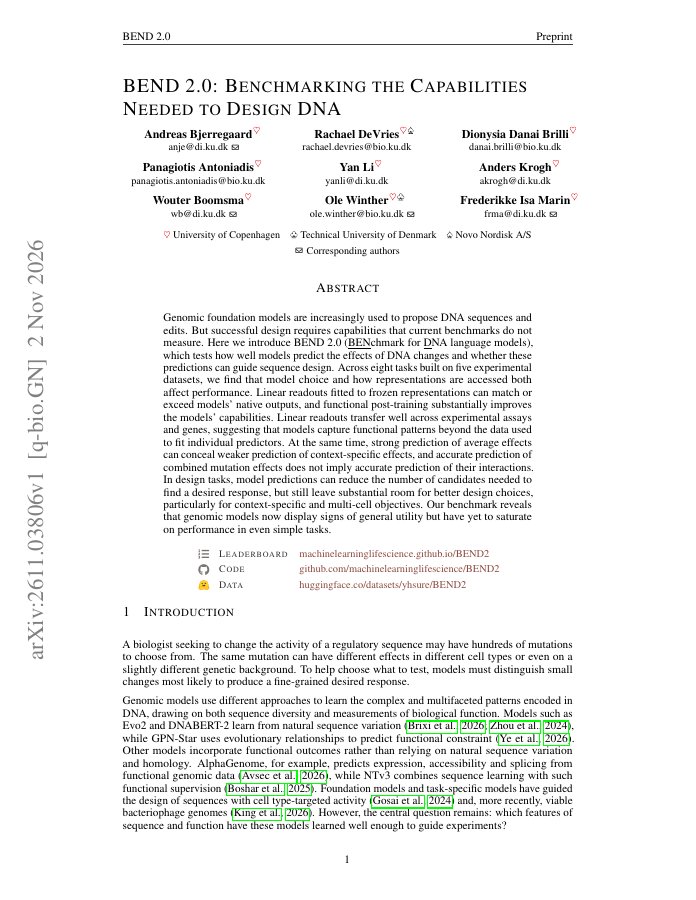
2 Nov 2026
Genomic foundation models are increasingly used to propose DNA sequences and edits. But successful design requires capabilities that current benchmarks do not measure. Here we introduce BEND 2.0 (BENchmark for DNA language models), which tests how well models predict the effects…
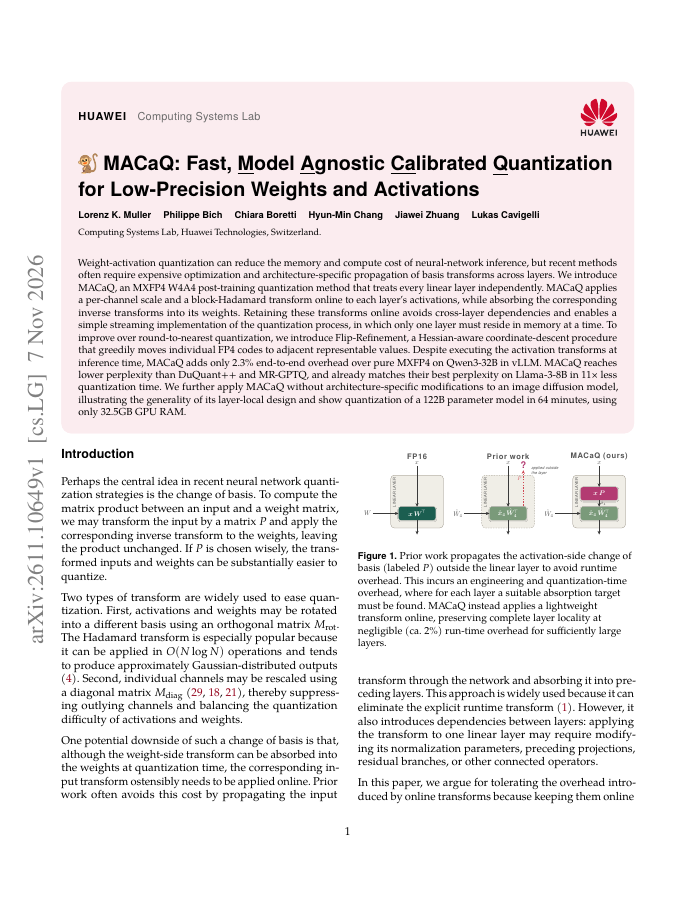
7 Nov 2026
Weight-activation quantization can reduce the memory and compute cost of neural-network inference, but recent methods often require expensive optimization and architecture-specific propagation of basis transforms across layers.
4 Nov 2026
Target-conditioned diffusion drafters predict candidate tokens in parallel, yet each new block must wait for updated target-model hidden states. This forces drafting and verification to run sequentially, limiting speedup even though each block is generated in one pass.
28 Oct 2026
We introduce Nemotron 3.5 Super and Nemotron 3.5 Lightning, open and efficient Mixture-of-Experts Hybrid Mamba-Transformer models designed for reasoning, long-context understanding, and agentic workloads.
9 Nov 2026
Discrete autoregressive modeling, notably through next-token prediction, has become a cornerstone of modern language models. Extending this paradigm to vision allows visual and language models to converge on a unified framework, thereby fostering shared methodology and…
12 Nov 2026
Transferring LLMs into System One decision models typically replaces the language modeling head with a decision head while retaining the full backbone, making every decision pay for all layers. Yet it remains unclear how much depth such decisions require.
12 Nov 2026
Second-order optimizers (e.g., Shampoo, SOAP) have emerged as compelling alternatives to Adam/AdamW and promise faster per-step convergence than AdamW in transformer training.