Multi-Branch Transformer
15 Nov 2026
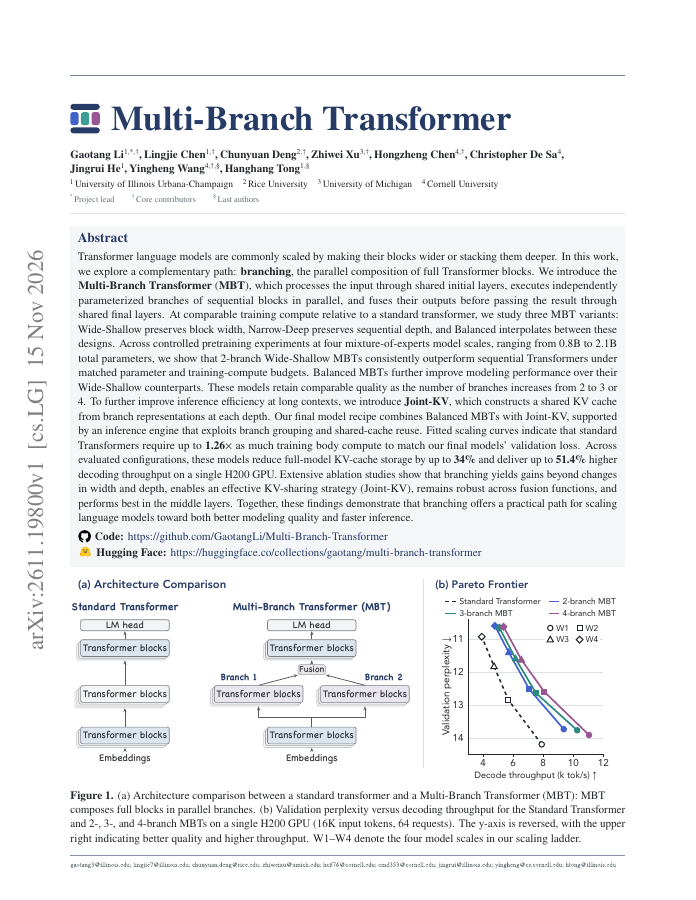
Transformer language models are commonly scaled by making their blocks wider or stacking them deeper. In this work, we explore a complementary path: branching, the parallel composition of full Transformer blocks.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,997 papers.
15 Nov 2026
Transformer language models are commonly scaled by making their blocks wider or stacking them deeper. In this work, we explore a complementary path: branching, the parallel composition of full Transformer blocks.
16 Nov 2026
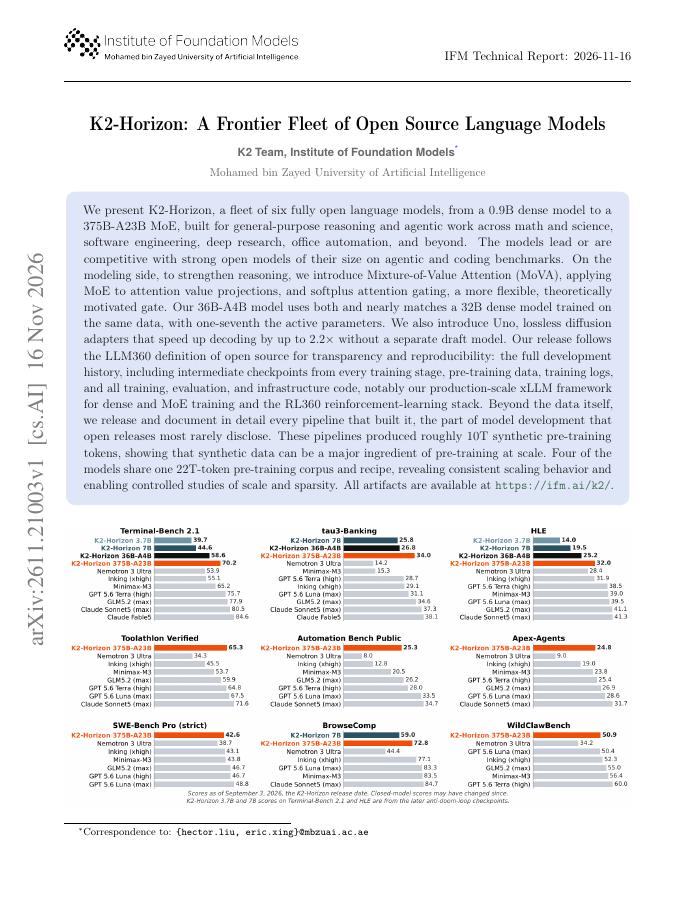
We present K2-Horizon, a fleet of six fully open language models, from a 0.9B dense model to a 375B-A23B MoE, built for general-purpose reasoning and agentic work across math and science, software engineering, deep research, office automation, and beyond.