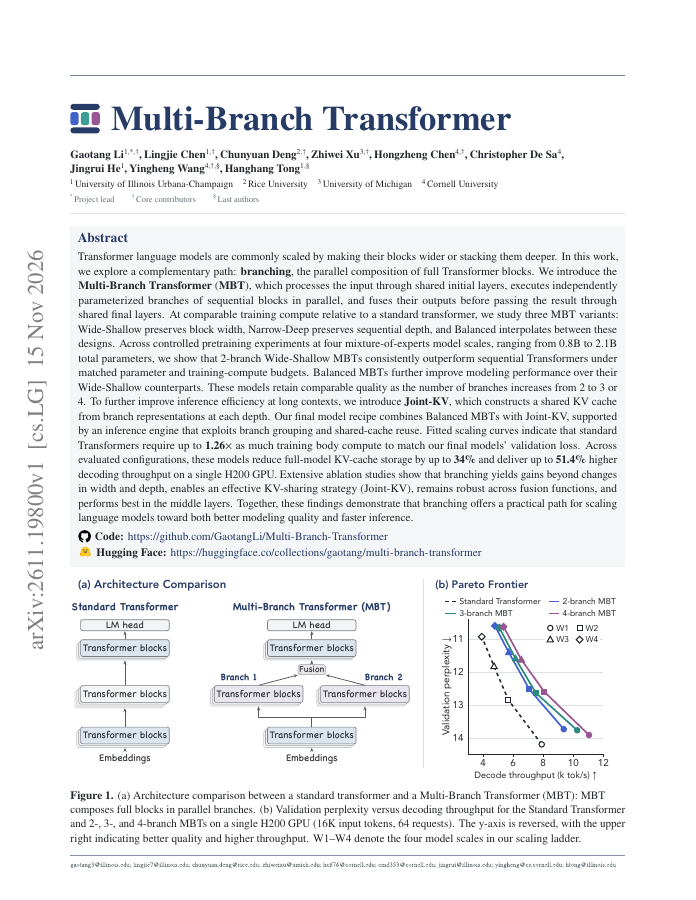
Multi-Branch Transformer
15 Nov 2026
Transformer language models are commonly scaled by making their blocks wider or stacking them deeper. In this work, we explore a complementary path: branching, the parallel composition of full Transformer blocks.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,997 papers.
15 Nov 2026
Transformer language models are commonly scaled by making their blocks wider or stacking them deeper. In this work, we explore a complementary path: branching, the parallel composition of full Transformer blocks.
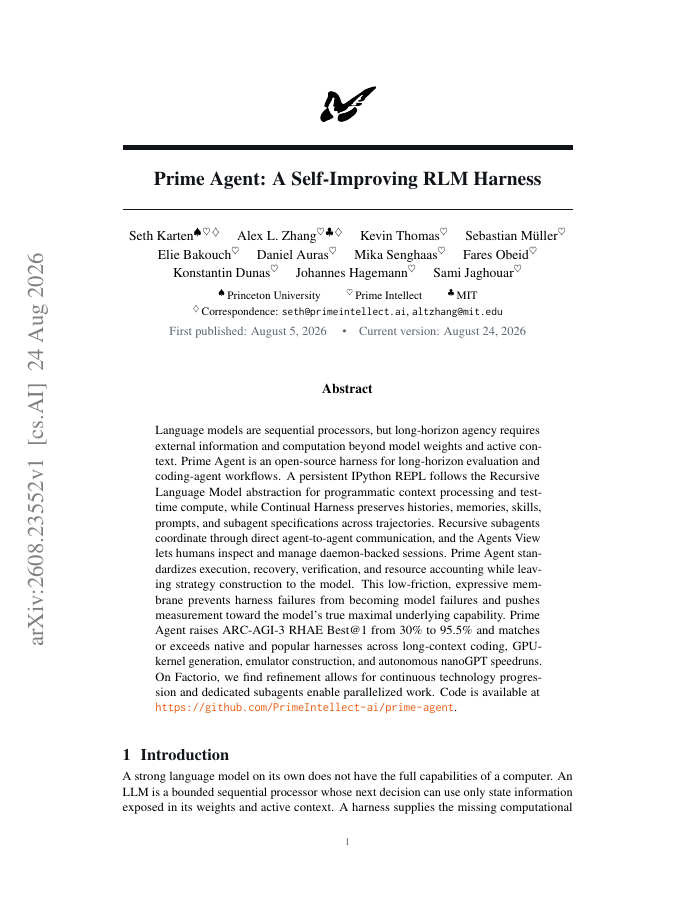
24 Aug 2026
Language models are sequential processors, but long-horizon agency requires external information and computation beyond model weights and active context. Prime Agent is an open-source harness for long-horizon evaluation and coding-agent workflows.
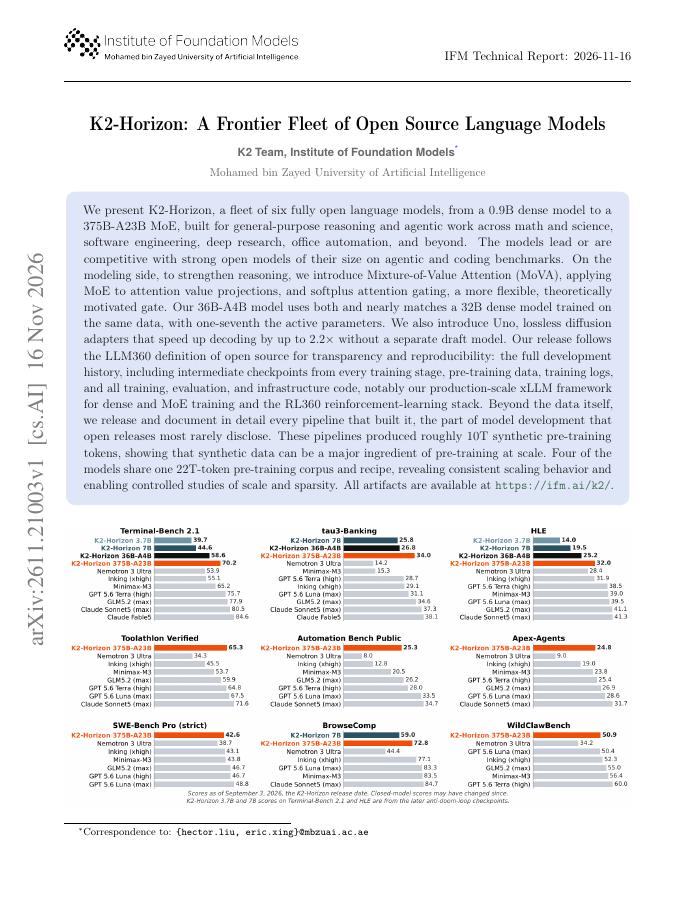
16 Nov 2026
We present K2-Horizon, a fleet of six fully open language models, from a 0.9B dense model to a 375B-A23B MoE, built for general-purpose reasoning and agentic work across math and science, software engineering, deep research, office automation, and beyond.

27 May 2026
Mixture-of-Experts (MoE) is now the dominant architecture for frontier language models, yet it requires all expert parameters to be loaded in memory, making it less preferable for memory-constrained deployment.
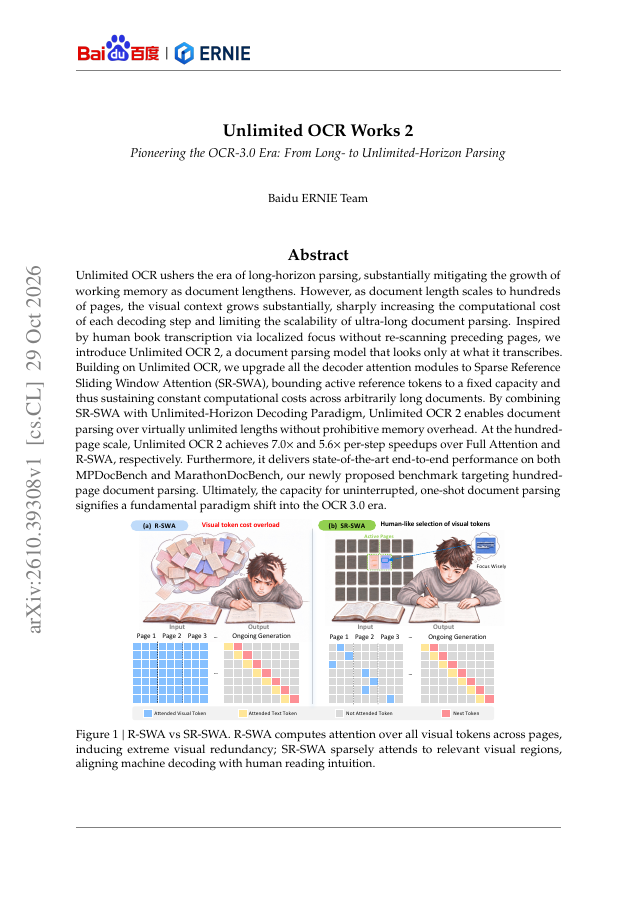
29 Oct 2026
Unlimited OCR ushers the era of long-horizon parsing, substantially mitigating the growth of working memory as document lengthens. However, as document length scales to hundreds of pages, the visual context grows substantially, sharply increasing the computational cost of each…
30 Oct 2026
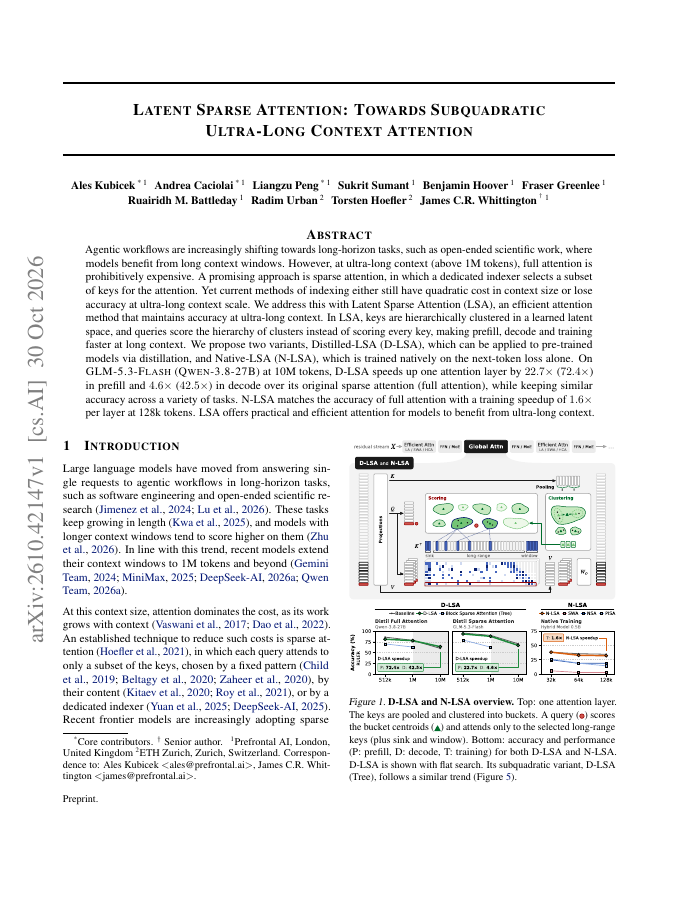
Agentic workflows are increasingly shifting towards long-horizon tasks, such as open-ended scientific work, where models benefit from long context windows. However, at ultra-long context (above 1M tokens), full attention is prohibitively expensive.