16 Oct 2026
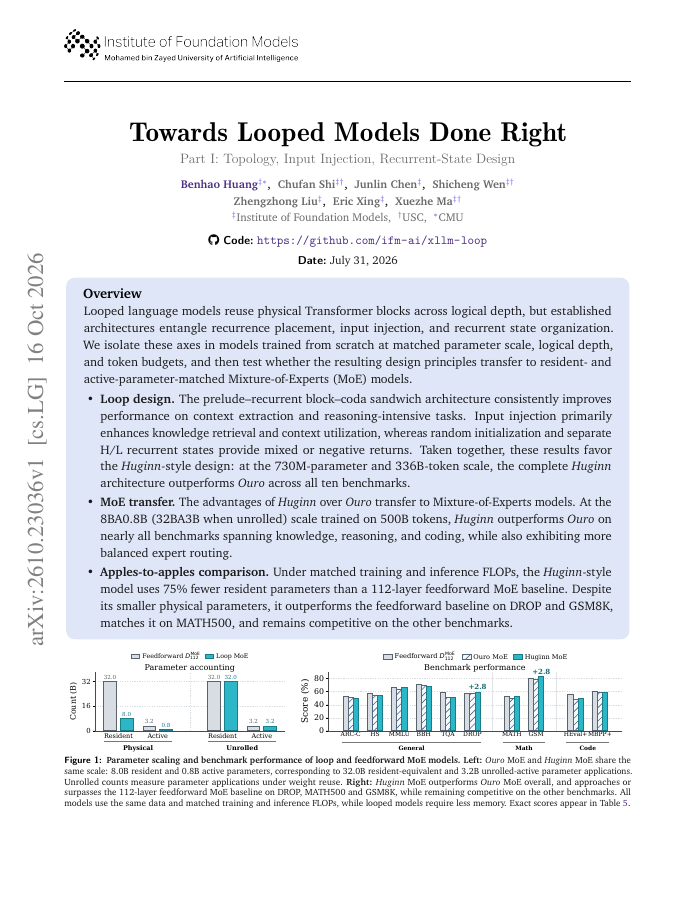
Looped language models reuse physical Transformer blocks across logical depth, but established architectures entangle recurrence placement, input injection, and recurrent state organization.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,663 papers.
16 Oct 2026
Looped language models reuse physical Transformer blocks across logical depth, but established architectures entangle recurrence placement, input injection, and recurrent state organization.
Guan Wang, Changling Liu, Chenyu Wang et al. · 20 May 2026
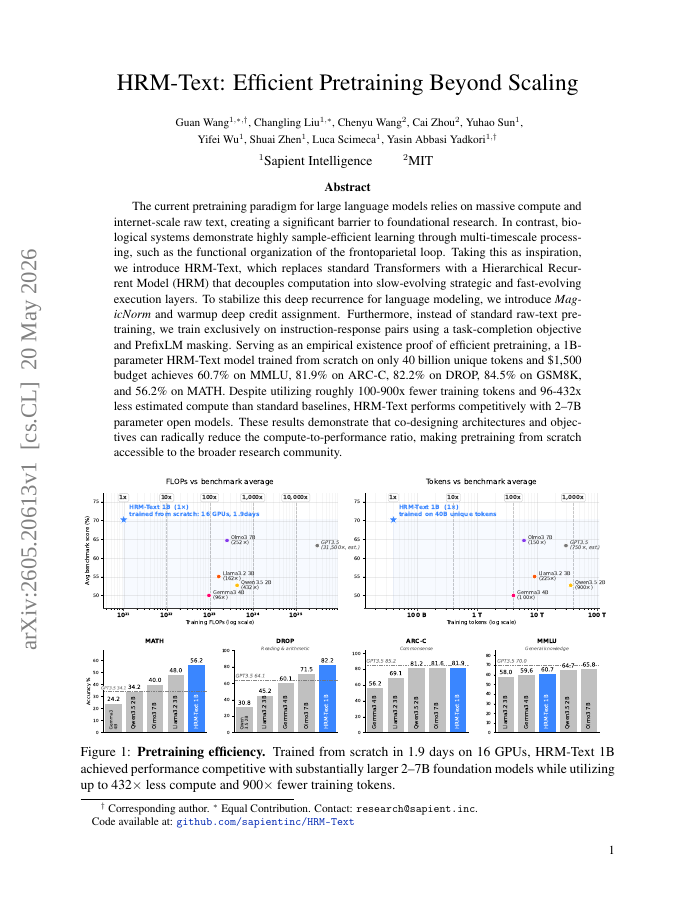
The current pretraining paradigm for large language models relies on massive compute and internet-scale raw text, creating a significant barrier to foundational research.
28 Sep 2026
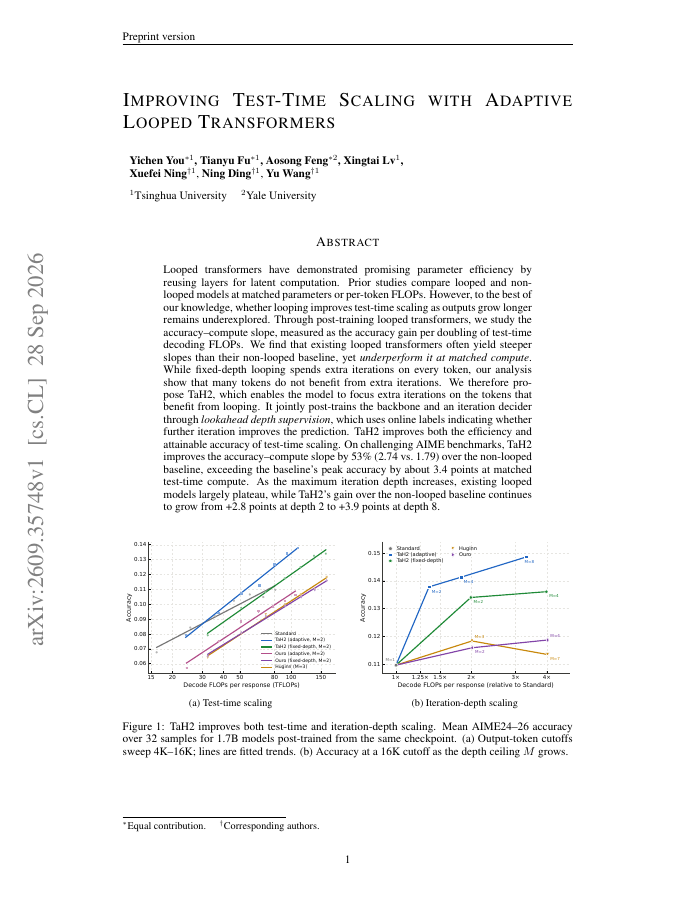
Looped transformers have demonstrated promising parameter efficiency by reusing layers for latent computation. Prior studies compare looped and non-looped models at matched parameters or per-token FLOPs.
20 Oct 2026
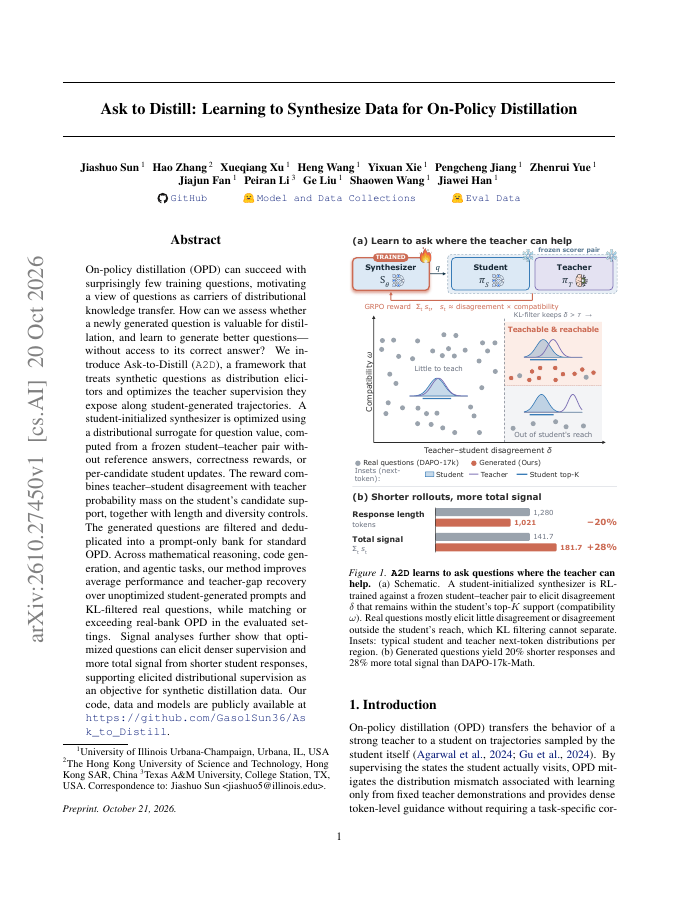
On-policy distillation (OPD) can succeed with surprisingly few training questions, motivating a view of questions as carriers of distributional knowledge transfer. How can we assess whether a newly generated question is valuable for distillation, and learn to generate better…