Inherited, Not Invented: Tracing the Provenance of Wait in Reasoning Models
22 Oct 2026
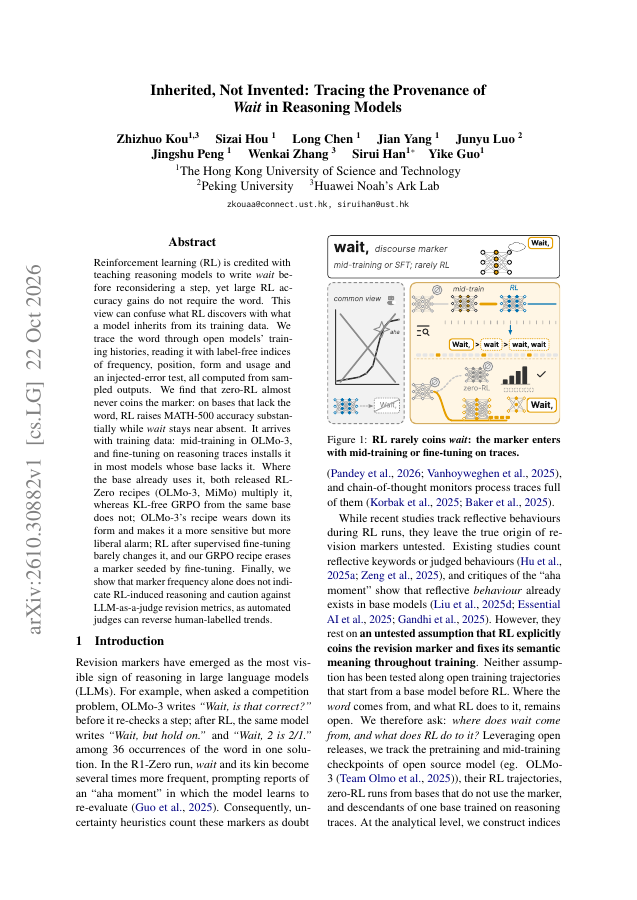
Reinforcement learning (RL) is credited with teaching reasoning models to write {wait} before reconsidering a step, yet large RL accuracy gains do not require the word. This view can confuse what RL discovers with what a model inherits from its training data.