Weight-Space Programming Doesn't Need Transformers
17 Nov 2026
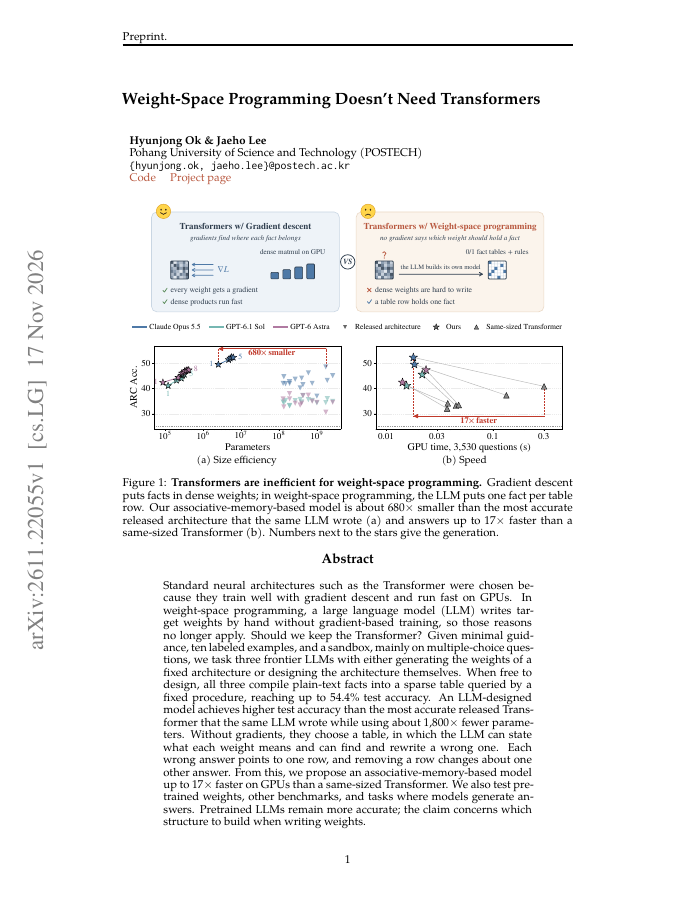
Standard neural architectures such as the Transformer were chosen because they train well with gradient descent and run fast on GPUs. In weight-space programming, a large language model (LLM) writes target weights by hand without gradient-based training, so those reasons no…