9 Oct 2026
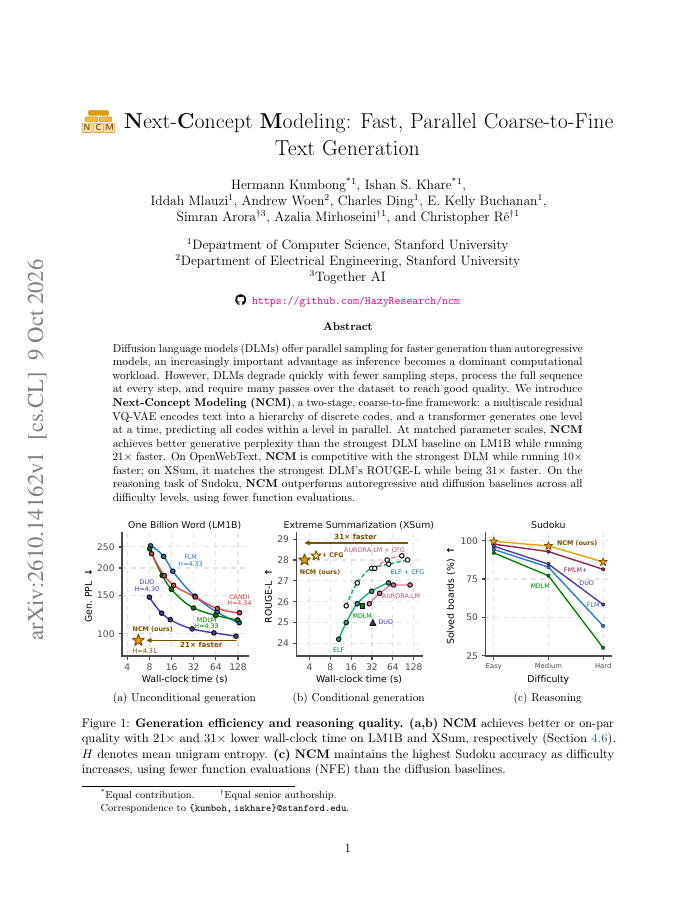
Diffusion language models (DLMs) offer parallel sampling for faster generation than autoregressive models, an increasingly important advantage as inference becomes a dominant computational workload.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,688 papers.
9 Oct 2026
Diffusion language models (DLMs) offer parallel sampling for faster generation than autoregressive models, an increasingly important advantage as inference becomes a dominant computational workload.
12 Oct 2026
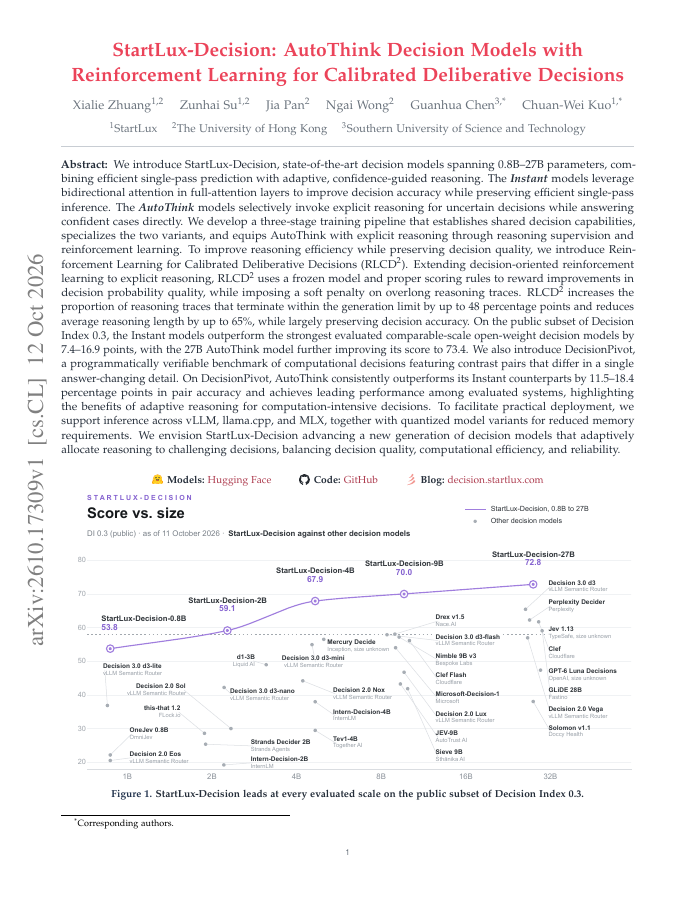
We introduce StartLux-Decision, decision models from 0.8B to 27B parameters that combine efficient single-pass prediction with adaptive, confidence-guided reasoning. The Instant models use bidirectional attention in full-attention layers to improve decision accuracy while…
2 Oct 2026
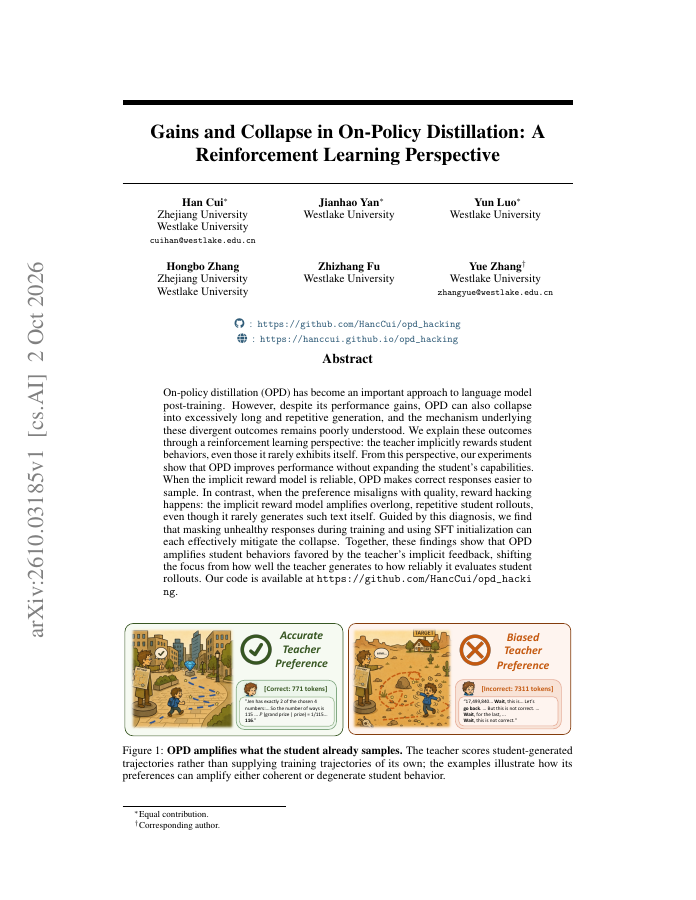
On-policy distillation (OPD) has become an important approach to language model post-training. However, despite its performance gains, OPD can also collapse into excessively long and repetitive generation, and the mechanism underlying these divergent outcomes remains poorly…
13 Oct 2026
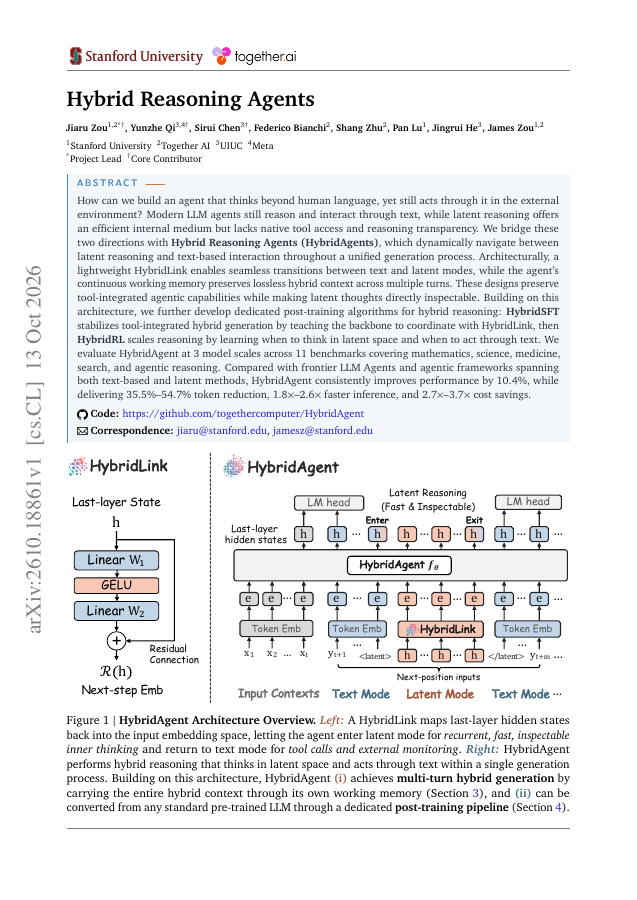
How can we build an agent that thinks beyond human language, yet still acts through it in the external environment? Modern LLM agents still reason and interact through text, while latent reasoning offers an efficient internal medium but lacks native tool access and reasoning…
20 Oct 2026
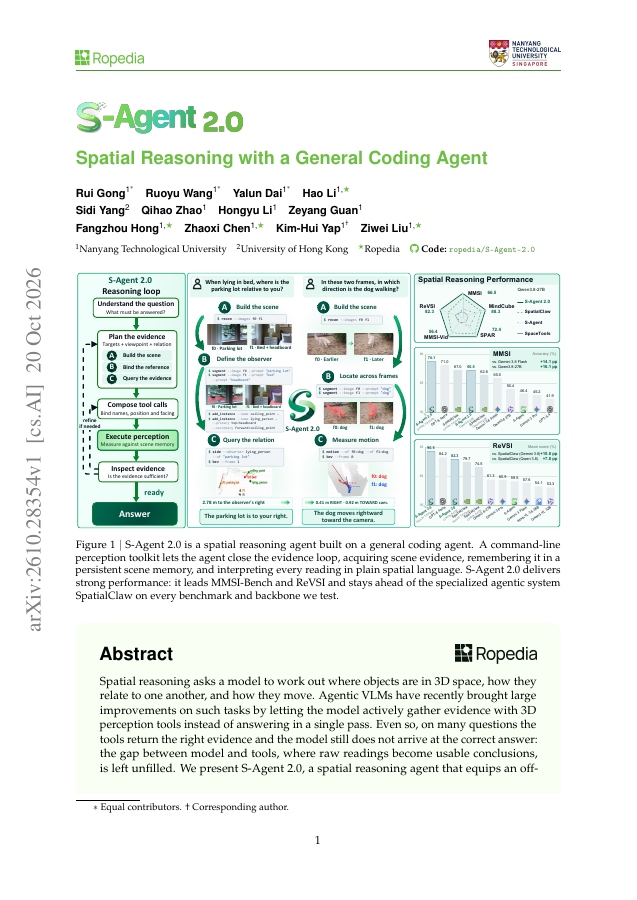
Spatial reasoning asks a model to work out where objects are in 3D space, how they relate to one another, and how they move. Agentic VLMs have recently brought large improvements on such tasks by letting the model actively gather evidence with 3D perception tools instead of…
21 Oct 2026
As LLMs expand their language coverage, evaluating how well they understand and represent diverse cultures becomes increasingly important. However, many benchmarks remain English-centric, with limited cultural coverage and a focus on factual knowledge over its application in…
22 Oct 2026
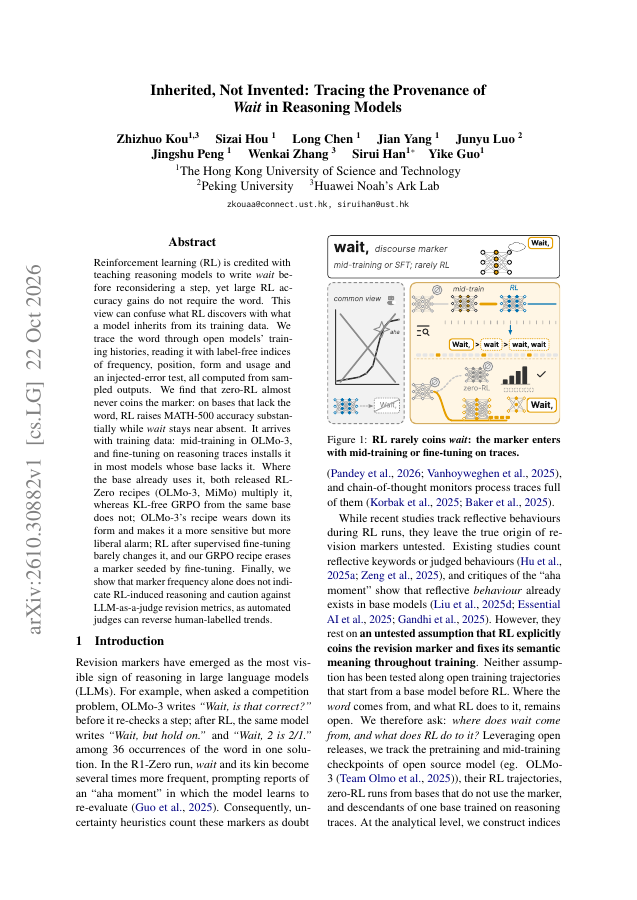
Reinforcement learning (RL) is credited with teaching reasoning models to write {wait} before reconsidering a step, yet large RL accuracy gains do not require the word. This view can confuse what RL discovers with what a model inherits from its training data.