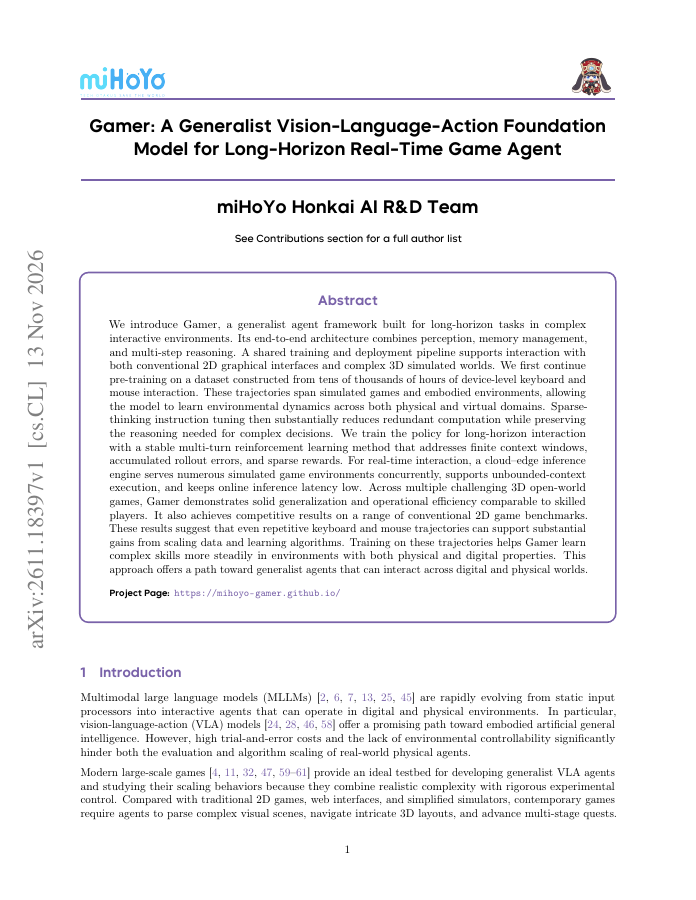
13 Nov 2026
We introduce Gamer, a generalist agent framework built for long-horizon tasks in complex interactive environments. Its end-to-end architecture combines perception, memory management, and multi-step reasoning.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 23,030 papers.
13 Nov 2026
We introduce Gamer, a generalist agent framework built for long-horizon tasks in complex interactive environments. Its end-to-end architecture combines perception, memory management, and multi-step reasoning.
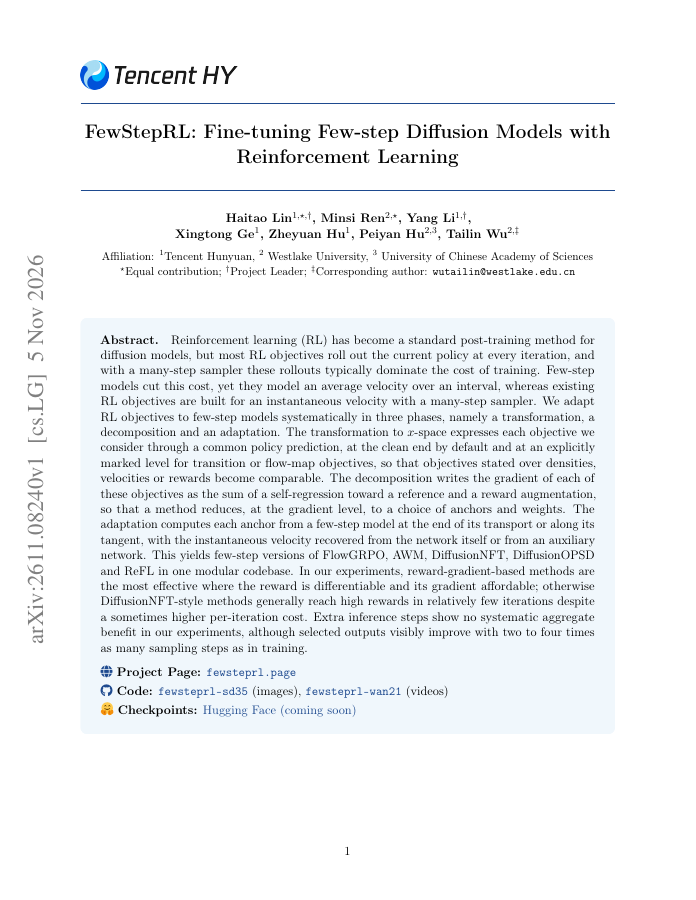
5 Nov 2026
Reinforcement learning (RL) has become a standard post-training method for diffusion models, but most RL objectives roll out the current policy at every iteration, and with a many-step sampler these rollouts typically dominate the cost of training.
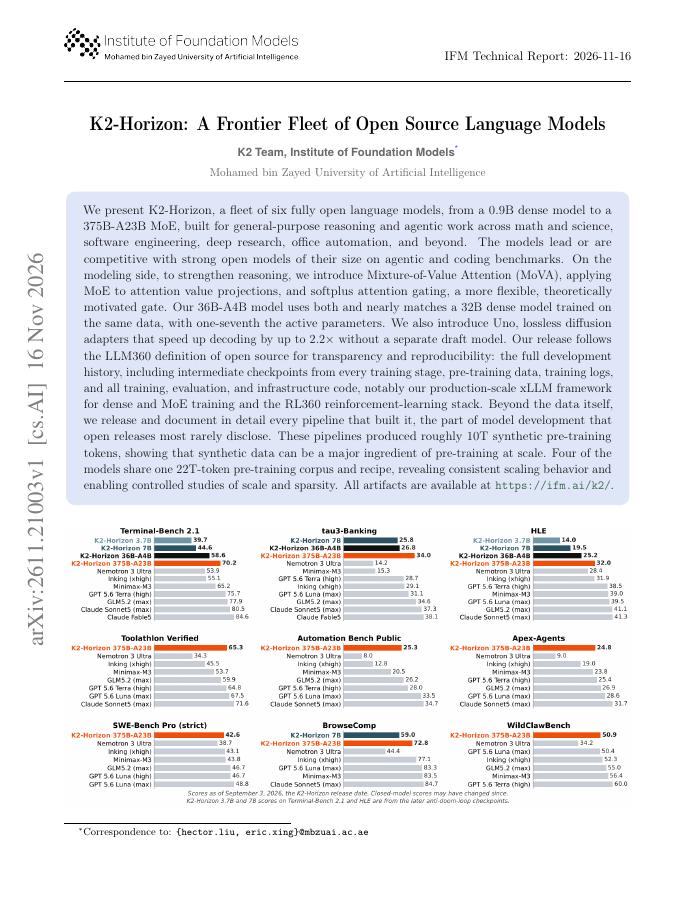
16 Nov 2026
We present K2-Horizon, a fleet of six fully open language models, from a 0.9B dense model to a 375B-A23B MoE, built for general-purpose reasoning and agentic work across math and science, software engineering, deep research, office automation, and beyond.
29 Oct 2026
Foundation models are typically trained in stages: pretraining, midtraining, supervised fine-tuning (SFT), and reinforcement learning (RL), with changes in both data and learning algorithms. We show that this algorithmic separation is not fundamental.
4 Nov 2026
Scaling computer-use agents from individual actions to complex software work requires experience that connects decisions to complete outcomes. We present NorthCUA, an integrated system for turbocharging computer-use agents through experience at scale.
15 Nov 2026
Real-world portfolio management requires converting noisy market observations into coordinated, simultaneous allocations across multiple assets under shared capital constraints. Advances in forecasting models and alpha discovery help identify opportunities.
28 Oct 2026
We introduce Nemotron 3.5 Super and Nemotron 3.5 Lightning, open and efficient Mixture-of-Experts Hybrid Mamba-Transformer models designed for reasoning, long-context understanding, and agentic workloads.
24 Oct 2026
Can LLM agents carry a hard real-world problem from raw data to a system that holds its own against people? We study this in Hearthstone Battlegrounds, an eight-player auto-battler with stochastic shops and battles, hidden information and nearly a thousand interacting cards.
29 Oct 2026
Effective computer-use agents (CUAs) should seamlessly combine visual GUI interaction with code and terminal execution within a single policy. We present Mage-VL-Cowork, a 4B hybrid CUA trained from a general multimodally aligned checkpoint through an end-to-end, progressive…
26 Oct 2026
Critic-free methods are widely used in reinforcement learning with verifiable rewards (RLVR) for long chain-of-thought (CoT) reasoning, avoiding difficult and costly critic training.
3 Nov 2026
Large language models are deployed as long-horizon agents that compose diverse tools across MCP services into executable workflows. Existing MCP environment-scaling methods are data-centric: they first synthesize a database and scenario, then derive tools and tasks from them.