1 Jun 2026
We introduce Cosmos 3, a family of omnimodal world models designed to jointly process and generate language, image, video, audio, and action sequences within a unified mixture-of-transformers architecture.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,663 papers.
1 Jun 2026
We introduce Cosmos 3, a family of omnimodal world models designed to jointly process and generate language, image, video, audio, and action sequences within a unified mixture-of-transformers architecture.
8 Oct 2026
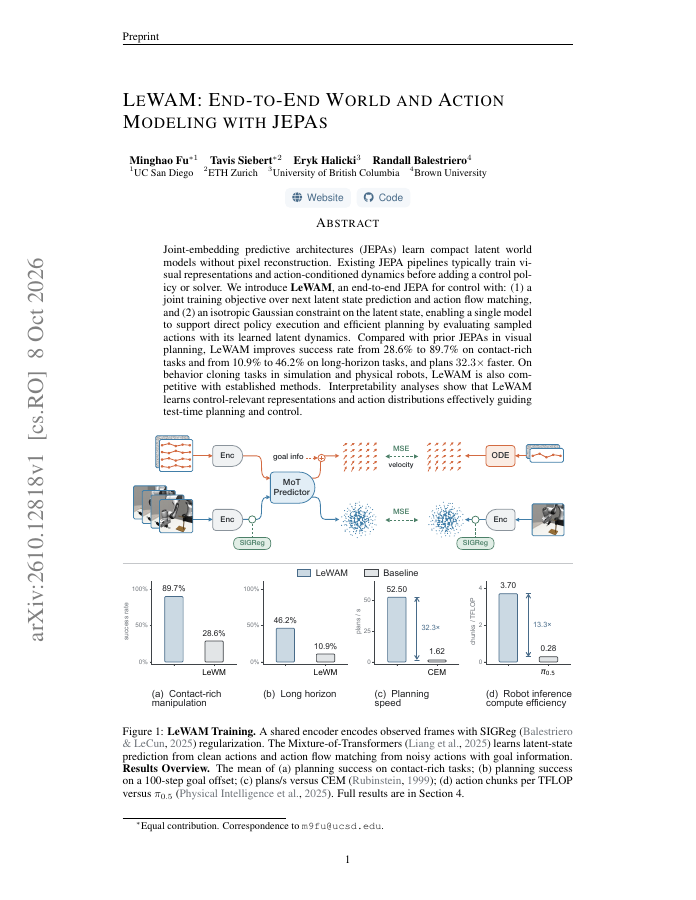
Joint-embedding predictive architectures (JEPAs) learn compact latent world models without pixel reconstruction. Existing JEPA pipelines typically train visual representations and action-conditioned dynamics before adding a control policy or solver.
19 Oct 2026
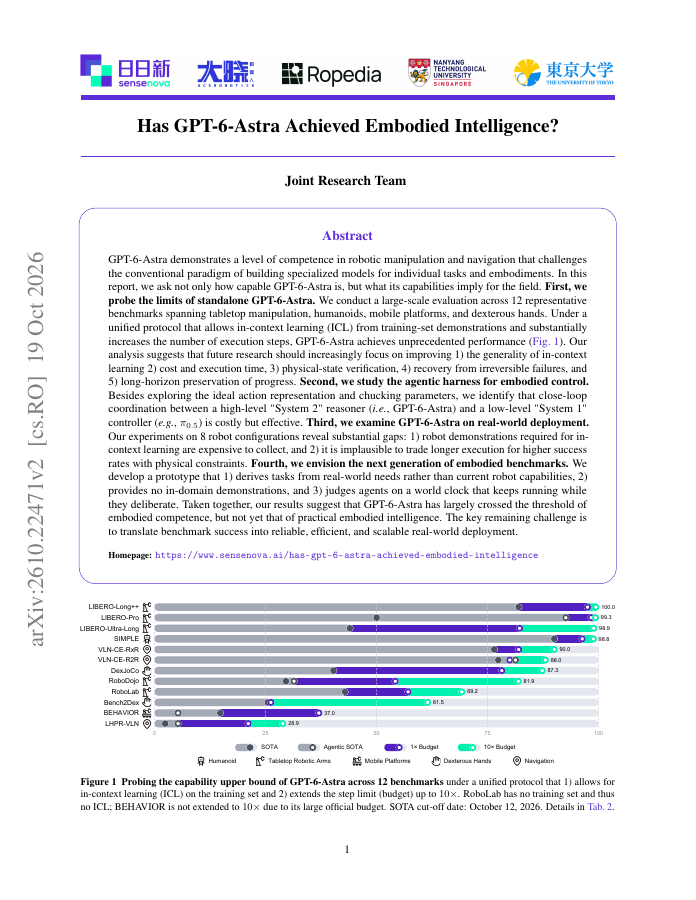
GPT-6-Astra demonstrates a level of competence in robotic manipulation and navigation that challenges the conventional paradigm of building specialized models for individual tasks and embodiments.
5 Oct 2026
World Action Models (WAMs) incorporate visual representations from video generation backbones to guide action prediction. Recent efficient WAMs adopt Mixture-of-Transformers (MoT) architectures and compute video representations once for reuse by the action expert.
16 Oct 2026
Precise grounding matters. It specifies which object is the target and where that object is, even in clutter and for tiny objects, and it has to be fast enough for closed-loop control.
19 Oct 2026
In this paper, we systematically investigate the mechanisms, scaling behavior, and generalization of physical Recursive self-improvement. We introduce PhysRSI-eval to quantify physical RSI through a five-axis metric: First-Attempt Performance, Efficiency, Success, Budget and…