13 Oct 2026
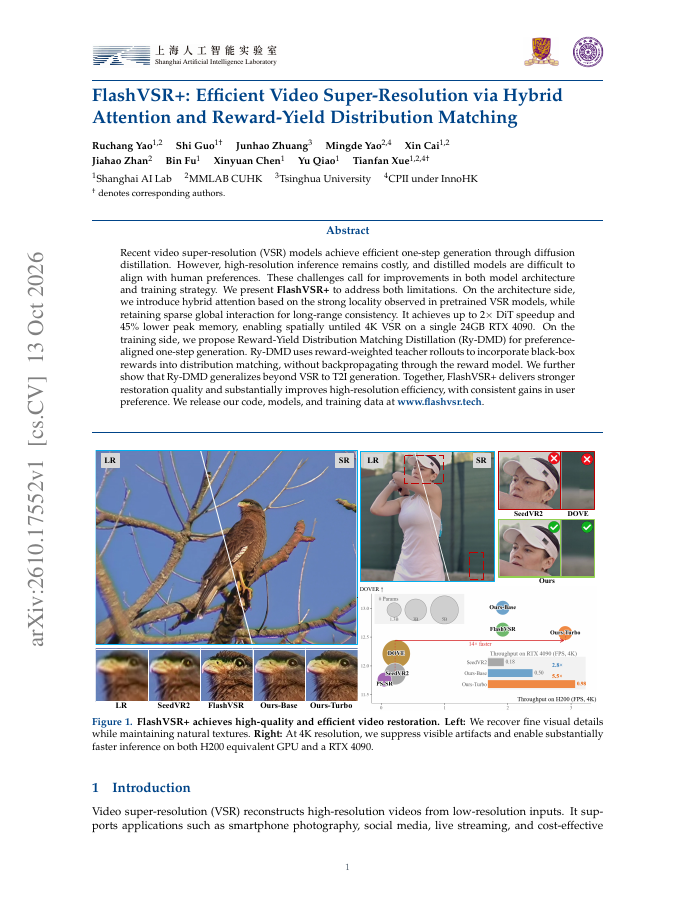
Recent video super-resolution (VSR) models achieve efficient one-step generation through diffusion distillation. However, high-resolution inference remains costly, and distilled models are difficult to align with human preferences.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,642 papers.
13 Oct 2026
Recent video super-resolution (VSR) models achieve efficient one-step generation through diffusion distillation. However, high-resolution inference remains costly, and distilled models are difficult to align with human preferences.
16 Oct 2026
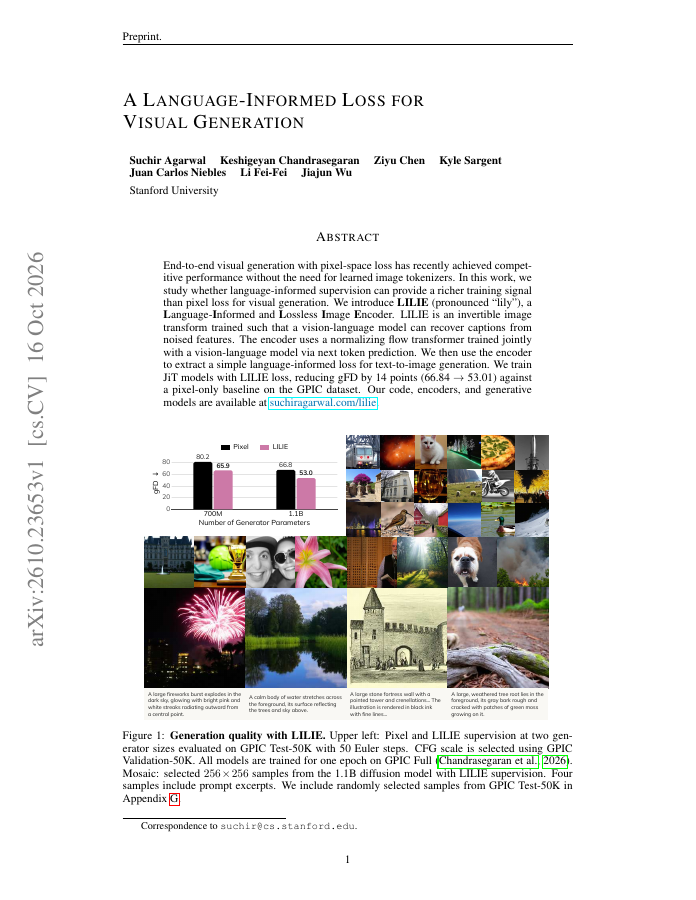
End-to-end visual generation with pixel-space loss has recently achieved competitive performance without the need for learned image tokenizers. In this work, we study whether language-informed supervision can provide a richer training signal than pixel loss for visual…