7 Nov 2026
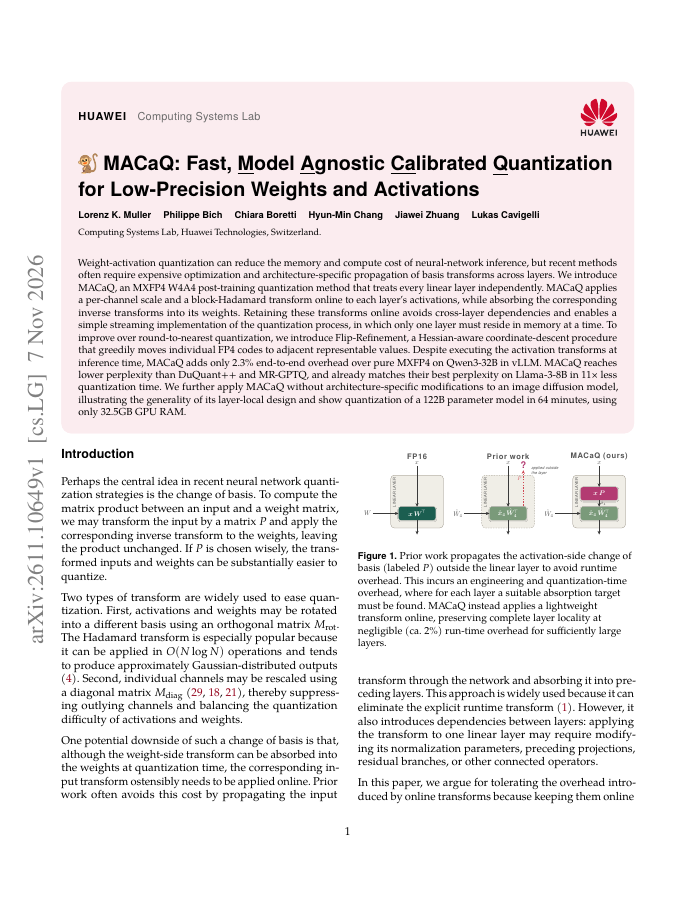
Weight-activation quantization can reduce the memory and compute cost of neural-network inference, but recent methods often require expensive optimization and architecture-specific propagation of basis transforms across layers.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,997 papers.
7 Nov 2026
Weight-activation quantization can reduce the memory and compute cost of neural-network inference, but recent methods often require expensive optimization and architecture-specific propagation of basis transforms across layers.
9 Nov 2026
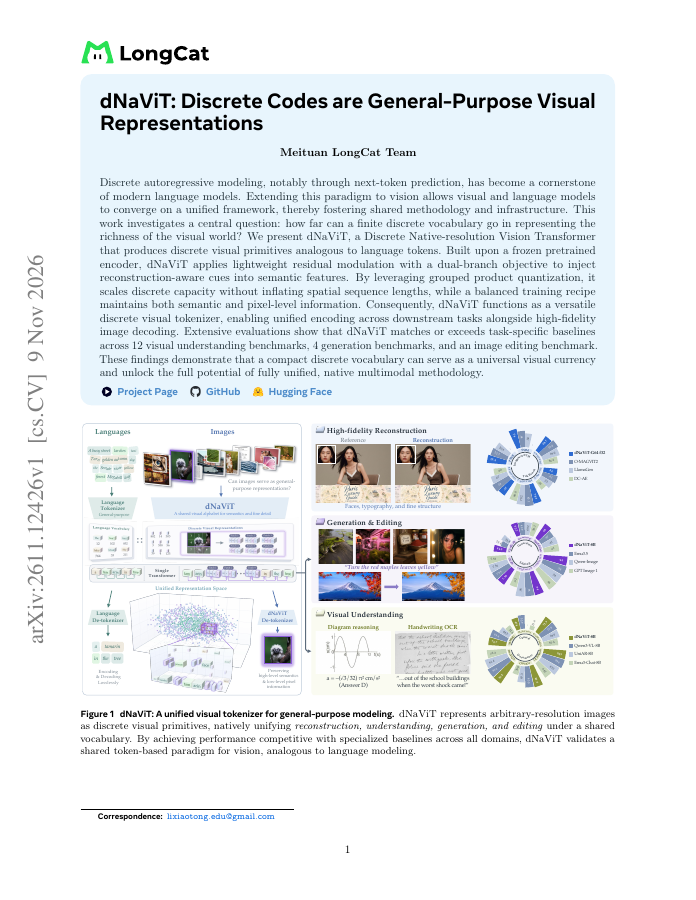
Discrete autoregressive modeling, notably through next-token prediction, has become a cornerstone of modern language models. Extending this paradigm to vision allows visual and language models to converge on a unified framework, thereby fostering shared methodology and…