1 Jun 2026
We introduce Cosmos 3, a family of omnimodal world models designed to jointly process and generate language, image, video, audio, and action sequences within a unified mixture-of-transformers architecture.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,663 papers.
1 Jun 2026
We introduce Cosmos 3, a family of omnimodal world models designed to jointly process and generate language, image, video, audio, and action sequences within a unified mixture-of-transformers architecture.
Jiebo Luo, Ziyun Zeng, Zhenghong Zhou et al. · 18 May 2026
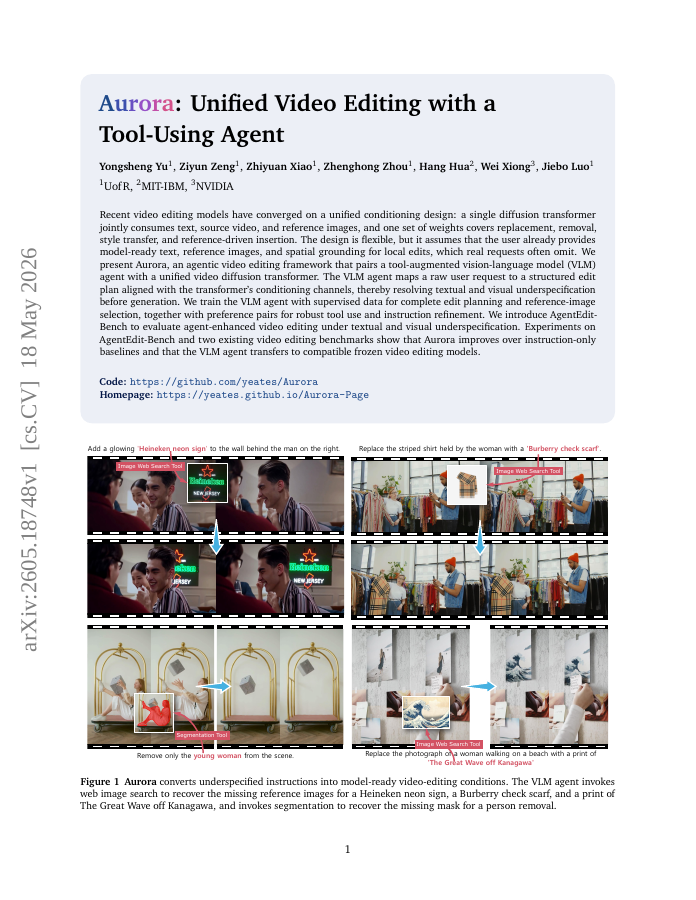
Aurora is an agentic video editing framework that combines a vision-language model agent with a diffusion transformer to handle textual and visual underspecification in video editing requests.
5 Oct 2026
World Action Models (WAMs) incorporate visual representations from video generation backbones to guide action prediction. Recent efficient WAMs adopt Mixture-of-Transformers (MoT) architectures and compute video representations once for reuse by the action expert.
28 Sep 2026
We present EditWorld, a video world model for precise editing and flexible referencing in interactable worlds. Existing video world models primarily focus on navigation, letting users explore generated worlds but offering limited control over how existing world content is…
1 Oct 2026
Distribution Matching Distillation (DMD) trains a few-step student from the difference between separately estimated target and student scores, so it must keep an auxiliary diffusion model fitted to the student's evolving distribution at extra memory and computation cost.