1 Jun 2026
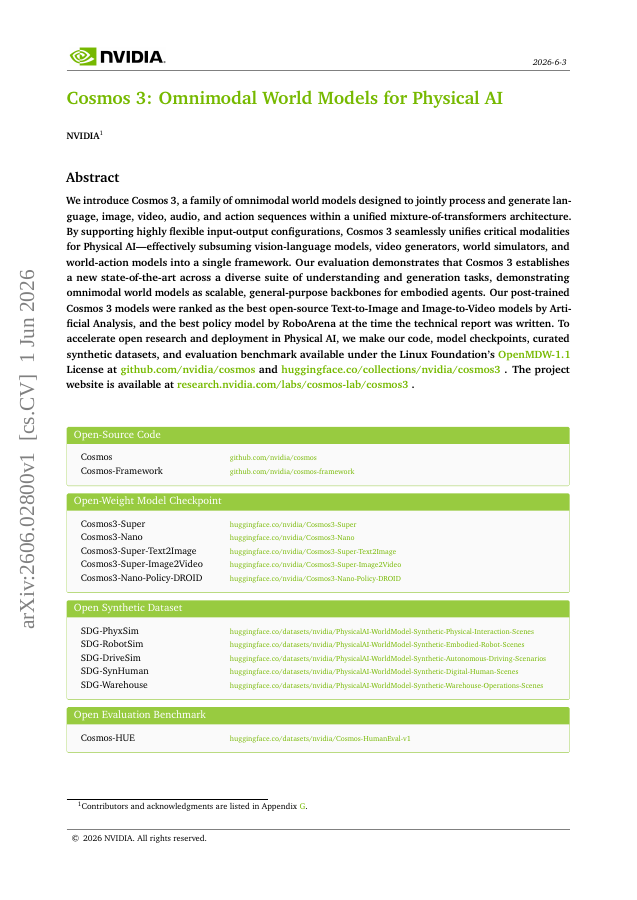
We introduce Cosmos 3, a family of omnimodal world models designed to jointly process and generate language, image, video, audio, and action sequences within a unified mixture-of-transformers architecture.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,667 papers.
1 Jun 2026
We introduce Cosmos 3, a family of omnimodal world models designed to jointly process and generate language, image, video, audio, and action sequences within a unified mixture-of-transformers architecture.
1 Oct 2026
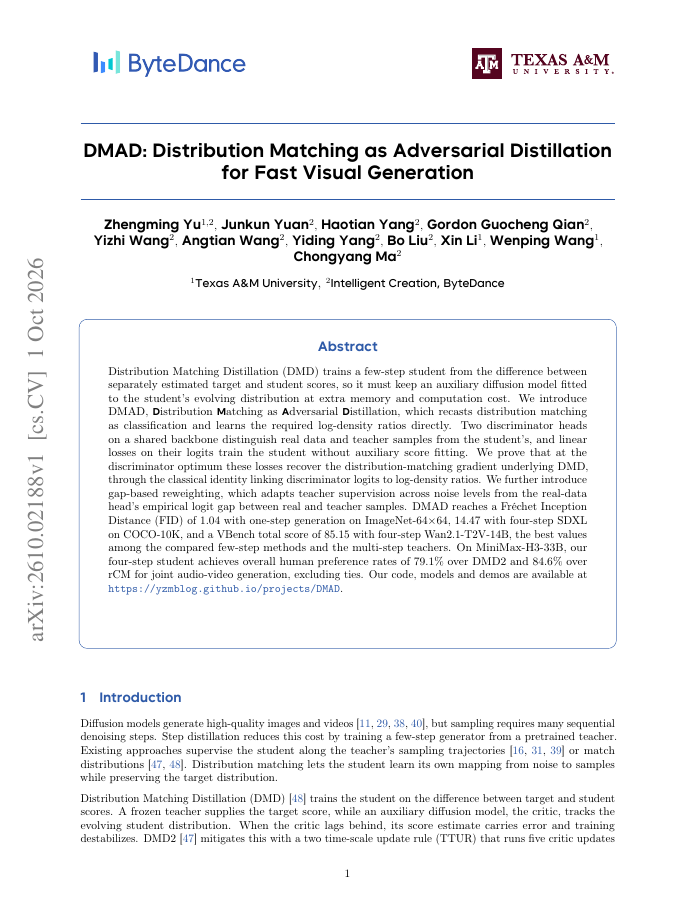
Distribution Matching Distillation (DMD) trains a few-step student from the difference between separately estimated target and student scores, so it must keep an auxiliary diffusion model fitted to the student's evolving distribution at extra memory and computation cost.
8 Oct 2026
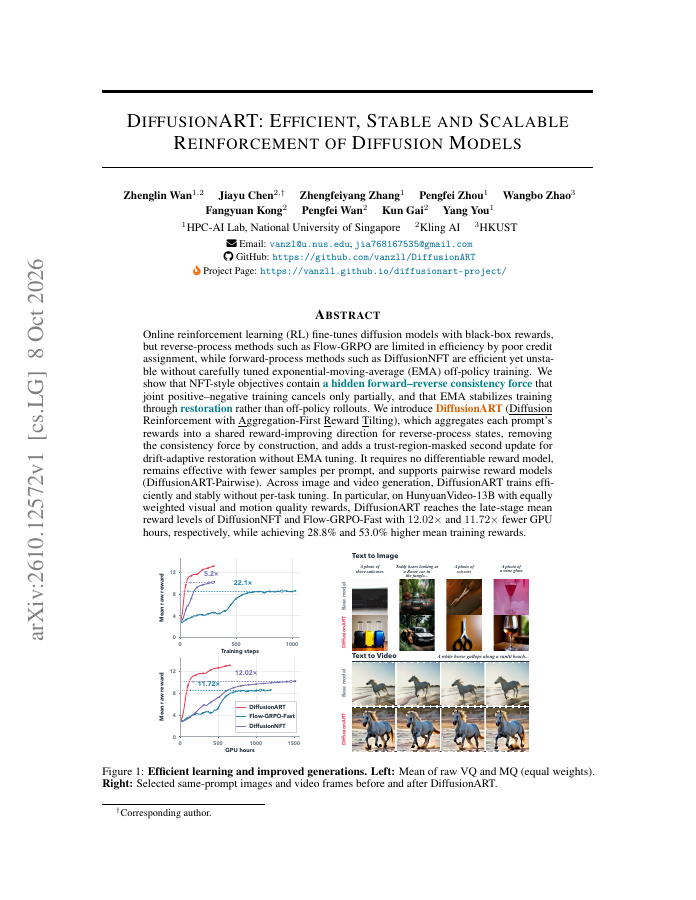
Online reinforcement learning (RL) fine-tunes diffusion models with black-box rewards, but reverse-process methods such as Flow-GRPO are limited in efficiency by poor credit assignment, while forward-process methods such as DiffusionNFT are efficient yet unstable without…
20 Oct 2026
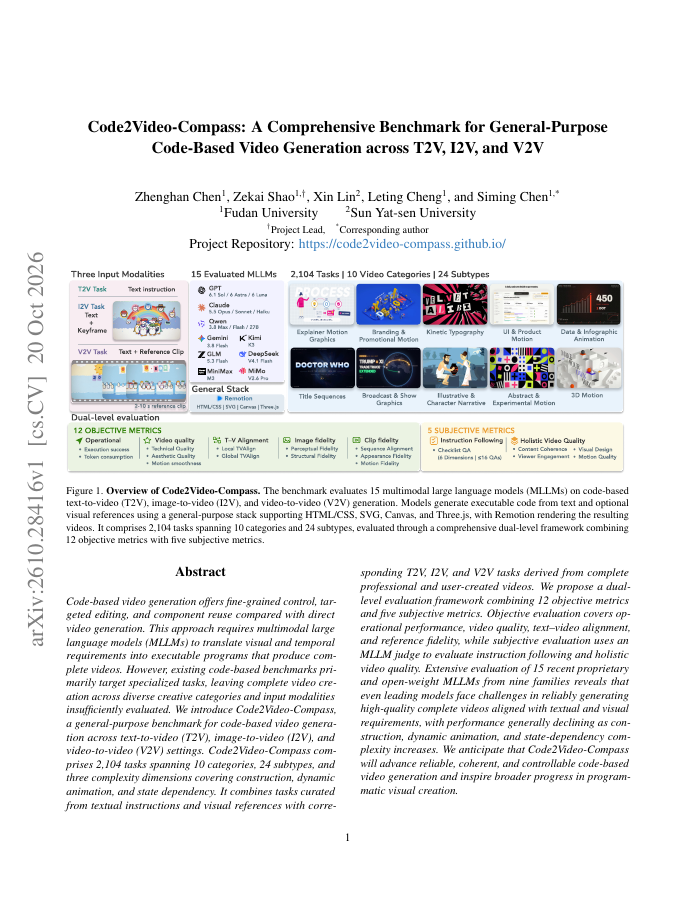
Code-based video generation offers fine-grained control, targeted editing, and component reuse compared with direct video generation. This approach requires multimodal large language models (MLLMs) to translate visual and temporal requirements into executable programs that…
21 Oct 2026
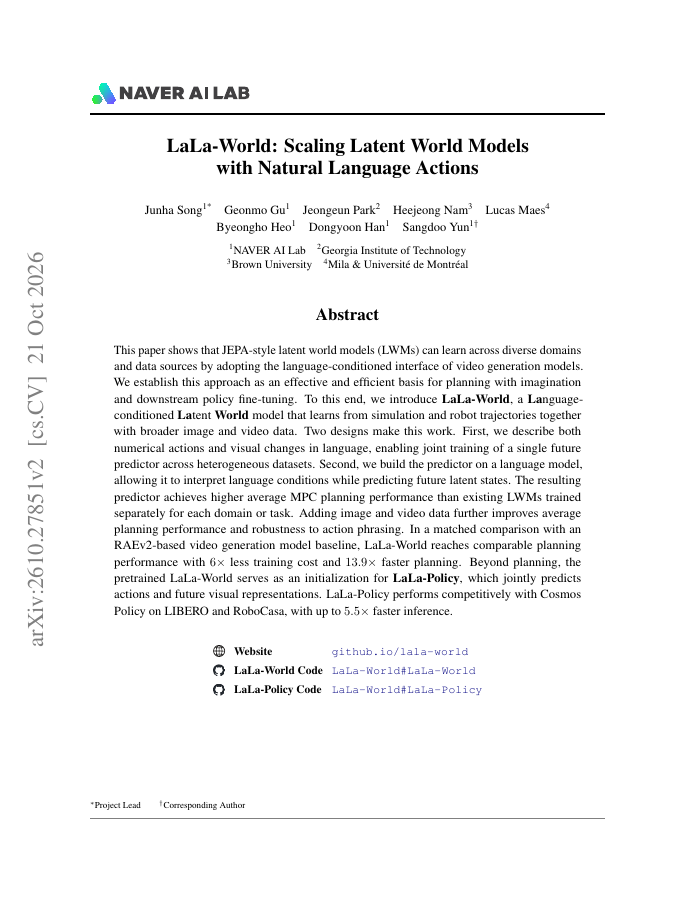
This paper shows that JEPA-style latent world models (LWMs) can learn across diverse domains and data sources by adopting the language-conditioned interface of video generation models.