1 Jun 2026
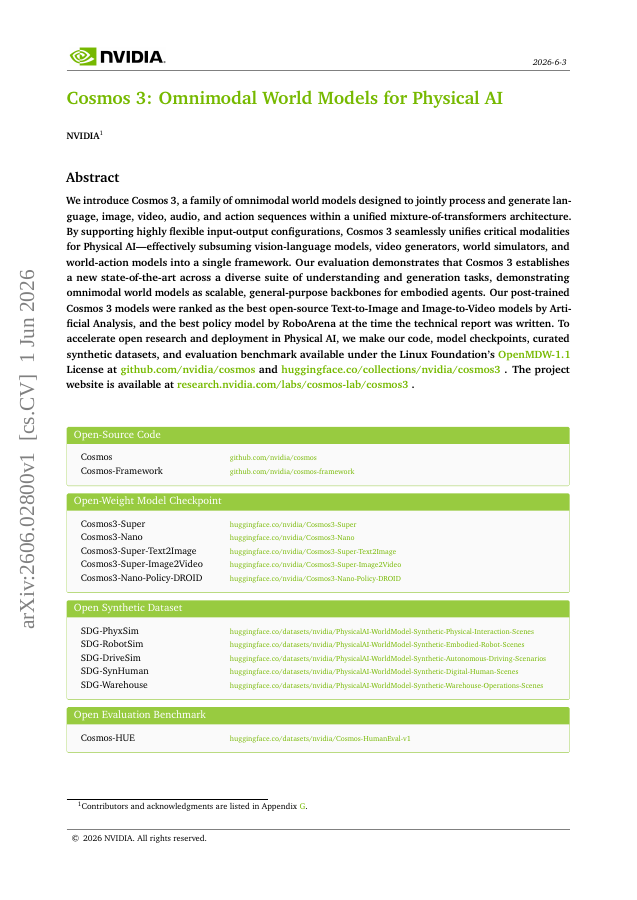
We introduce Cosmos 3, a family of omnimodal world models designed to jointly process and generate language, image, video, audio, and action sequences within a unified mixture-of-transformers architecture.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,688 papers.
1 Jun 2026
We introduce Cosmos 3, a family of omnimodal world models designed to jointly process and generate language, image, video, audio, and action sequences within a unified mixture-of-transformers architecture.
5 Oct 2026
Realistic environment replicas are increasingly valuable for training and evaluating LLM agents, yet the original systems may be inaccessible or impractical to reproduce.
15 Oct 2026
Recent 3D world models increasingly use features from geometry foundation models (GFMs) as predictive world states, benefiting from their rich geometric priors. However, the view dependence of these features entangles scene dynamics with camera-induced variation, making the…
9 Oct 2026
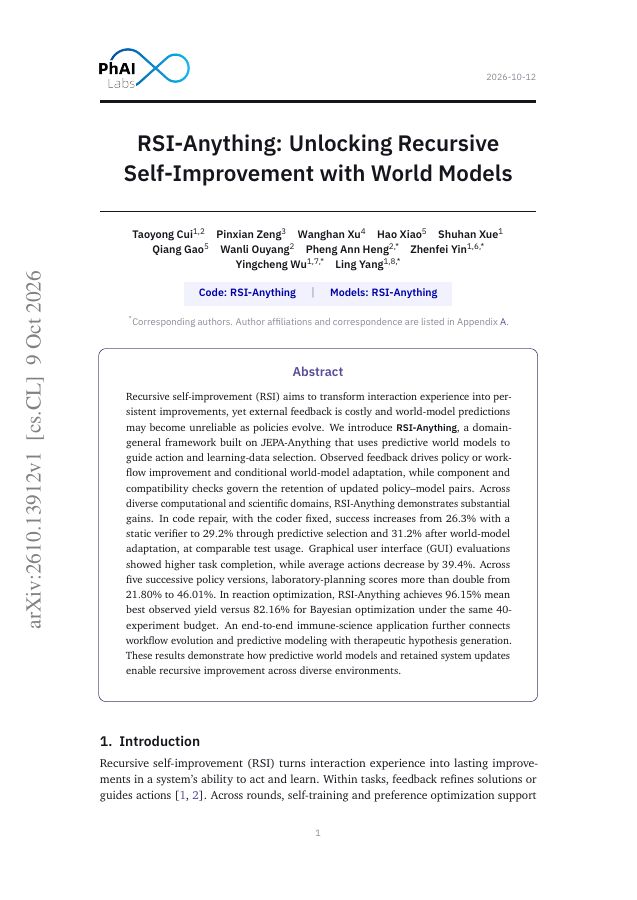
Recursive self-improvement (RSI) aims to transform interaction experience into persistent improvements, yet external feedback is costly and world-model predictions may become unreliable as policies evolve.
21 Oct 2026
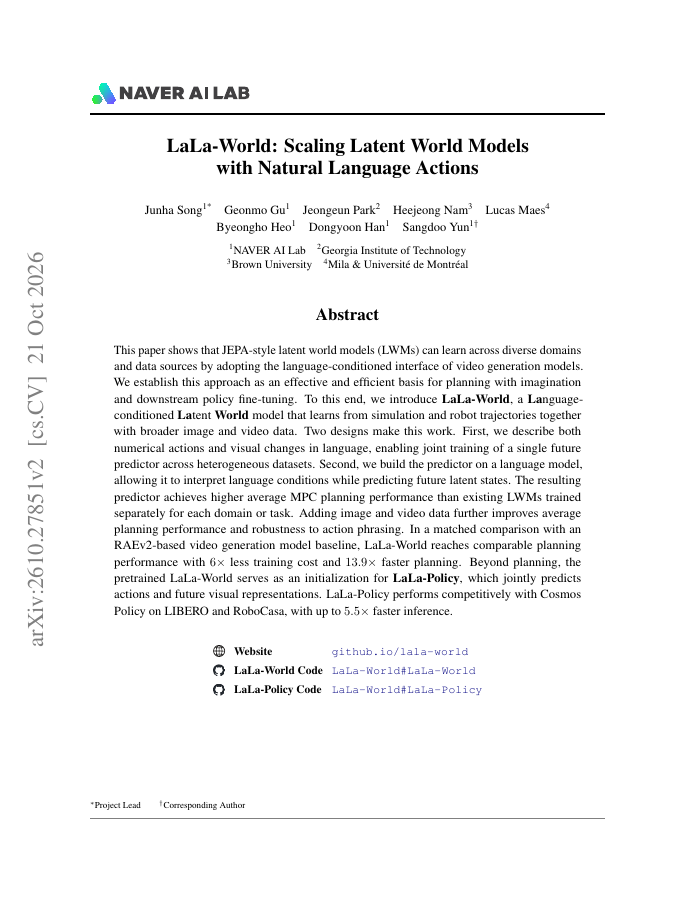
This paper shows that JEPA-style latent world models (LWMs) can learn across diverse domains and data sources by adopting the language-conditioned interface of video generation models.
20 Oct 2026
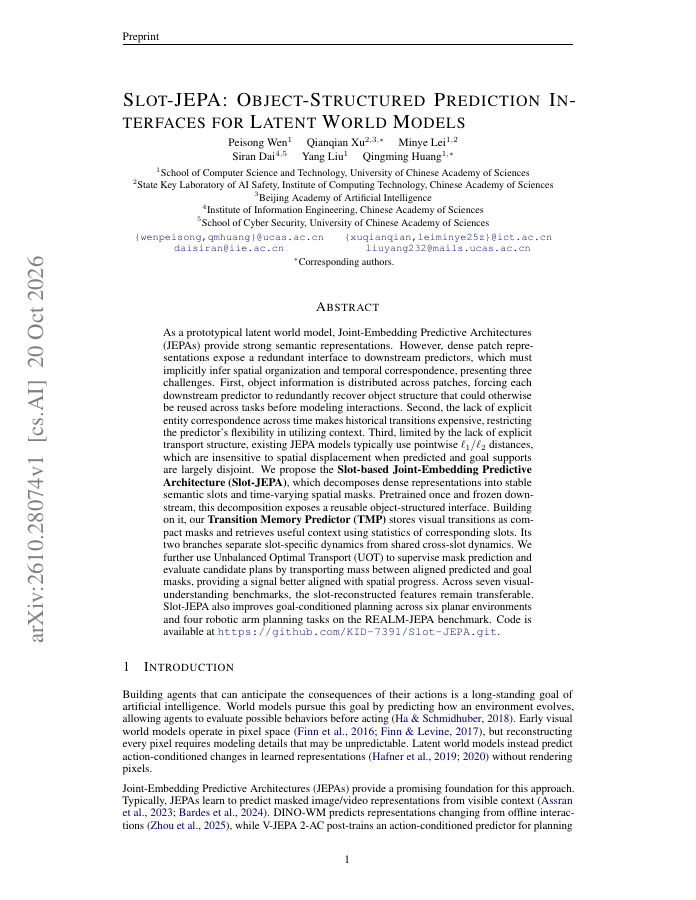
As a prototypical latent world model, Joint-Embedding Predictive Architectures (JEPAs) provide strong semantic representations. However, dense patch representations expose a redundant interface to downstream predictors, which must implicitly infer spatial organization and…