
Sophon
Catalog of AI evals, the tools that lift them, and the labs behind them. Press ⌘K to search.


Latest
Newest evals, tools, models, and papers
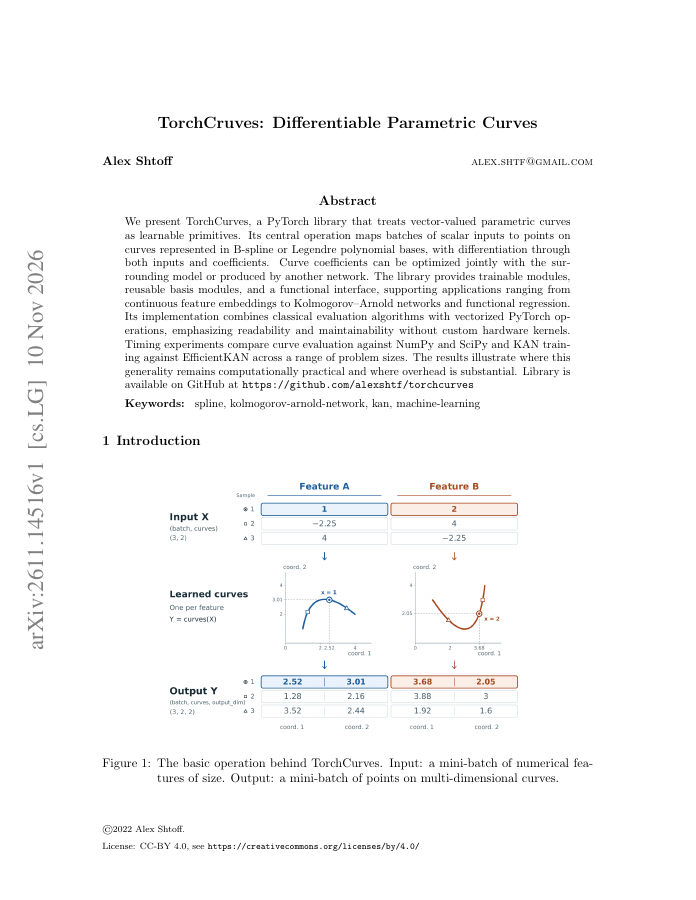
We present TorchCurves, a PyTorch library that treats vector-valued parametric curves as learnable primitives. Its central operation maps batches of scalar inputs to points on curves represented in B-spline or Legendre polynomial bases, with differentiation through both inputs…
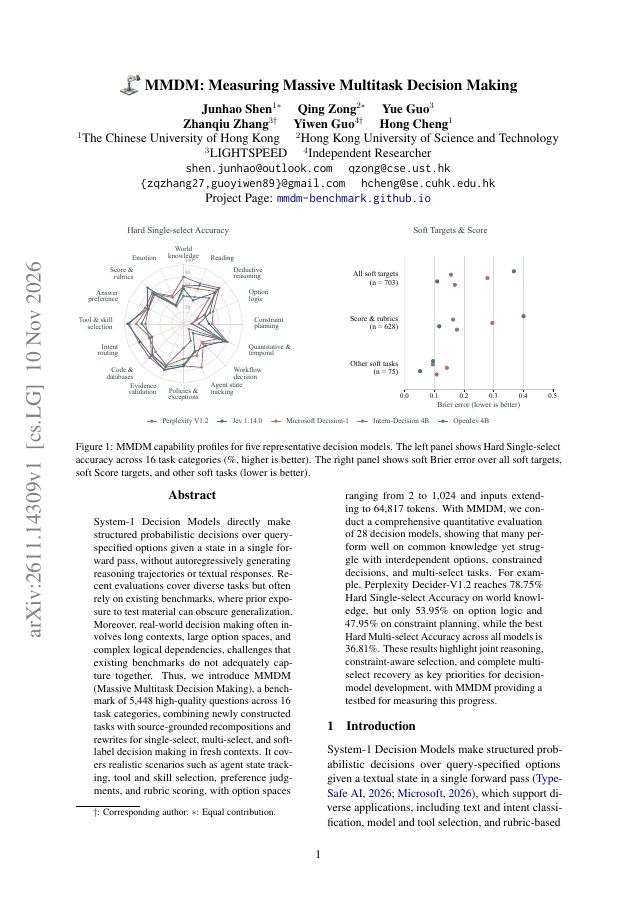
System-1 Decision Models directly make structured probabilistic decisions over query-specified options given a state in a single forward pass, without autoregressively generating reasoning trajectories or textual responses.
Interpretability demonstrations often show that intervening on a group of neurons changes a model's answer. A recent example removes an 18-neuron group in Qwen3-32B and the model answers "Simba" instead of "Scar" to a two-hop Lion King riddle.
RLVR trains language models to reason by rewarding correct final answers. A widely used algorithm, group-relative policy optimization (GRPO), gives every token of a solution the same credit, so dense process rewards have been proposed to credit intermediate steps, for example…
Point upgrade to Claude Fable 5.1 from Anthropic, with gains in coding, reasoning, and vision. Same 1M context, at a lower rack rate than Fable 5.1.
AAA games offer a rich testbed for evaluating agent perception, reasoning, and control. However, evaluating whether agents can complete tasks in AAA games is challenging and often human-annotated because task outcomes are often difficult to verify automatically, let alone…
Automating printed circuit board (PCB) routing requires coordinating board-level connectivity decisions with geometric execution under strict design rules. Although recent agents can interact with native routing tools, reliable routing on complex boards remains challenging.
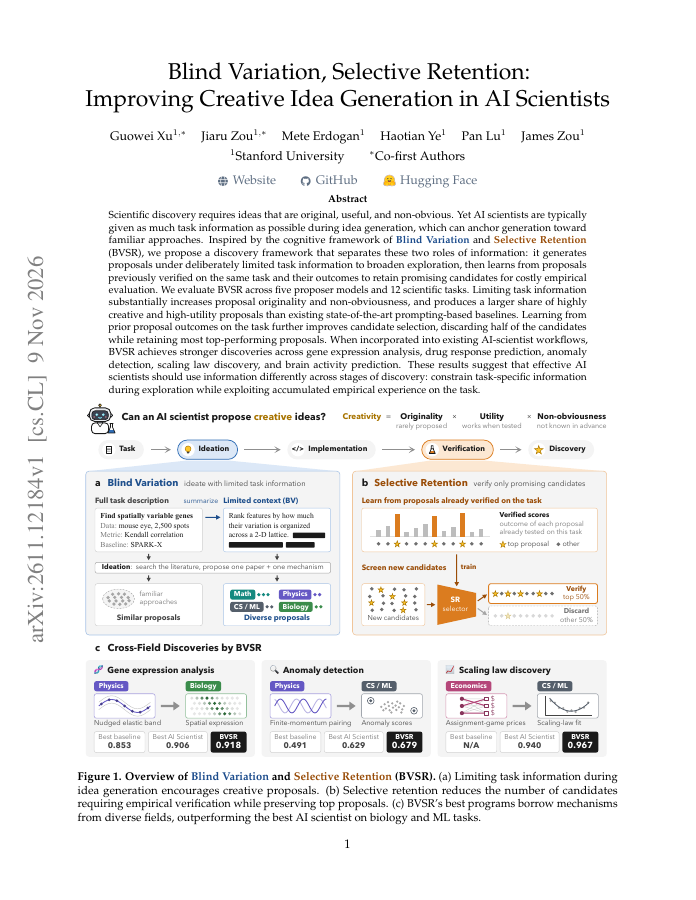
Scientific discovery requires ideas that are original, useful, and non-obvious. Yet AI scientists are typically given as much task information as possible during idea generation, which can anchor generation toward familiar approaches.
Leaderboards
Current standings across rating systems
#1 Gemini 4 Carbon · 1528
#1 Gemini 4 Carbon · 1539
#1 Gemini 4 Carbon · 1539
#1 Gemini 4 Argon · 1536
#1 Gemini 4 Carbon · 1543
#1 Gemini 4 Carbon · 1552
What lifts scores most
Tools with the most known eval-lift evidence
Browse by capability
Pick a capability to rank the tools that train toward it
Closest to saturation
Benchmarks where the top score approaches the ceiling