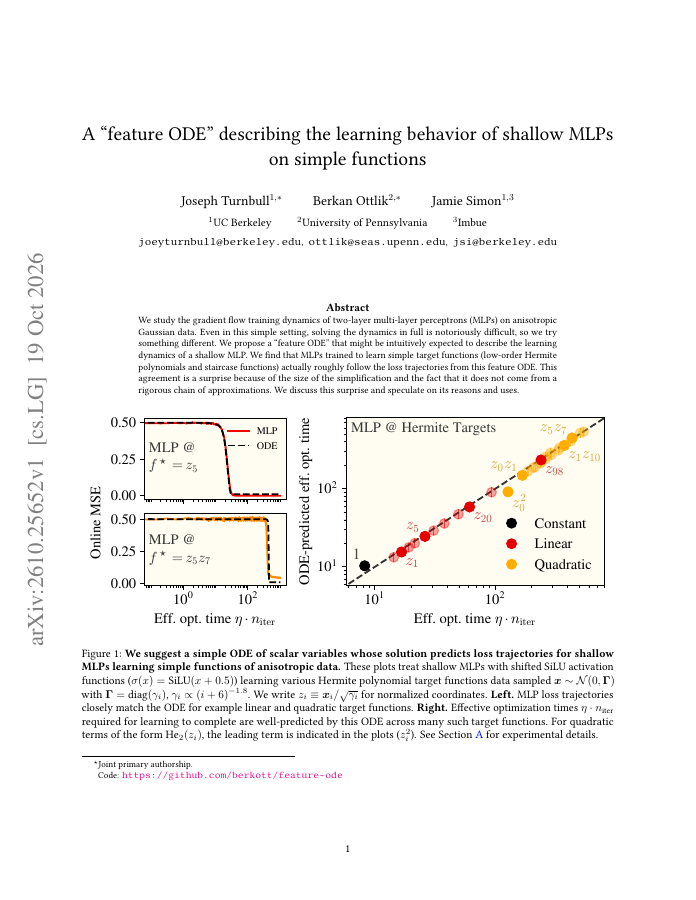
We study the gradient flow training dynamics of two-layer multi-layer perceptrons (MLPs) on anisotropic Gaussian data. Even in this simple setting, solving the dynamics in full is notoriously difficult, so we try something different. We propose a "feature ODE" that might be intuitively expected to describe the learning dynamics of a shallow MLP. We find that MLPs trained to learn simple target functions (low-order Hermite polynomials and staircase functions) actually roughly follow the loss trajectories from this feature ODE. This agreement is a surprise because of the size of the simplification and the fact that it does not come from a rigorous chain of approximations. We discuss this surprise and speculate on its reasons and uses.
A "feature ODE" describing the learning behavior of shallow MLPs on simple functions
We study the gradient flow training dynamics of two-layer multi-layer perceptrons (MLPs) on anisotropic Gaussian data. Even in this simple setting, solving the dynamics in full is notoriously difficult, so we try something different.
- Preview
- Year
- 2026
- Hosting
- Full text hostedCC-BY-4.0
Cite
Notes
Only stored in your browser.
Attribution
- Abstract & full text
- arxiv.org/abs/2610.25652CC-BY-4.0
- TL;DR
- Semantic Scholar