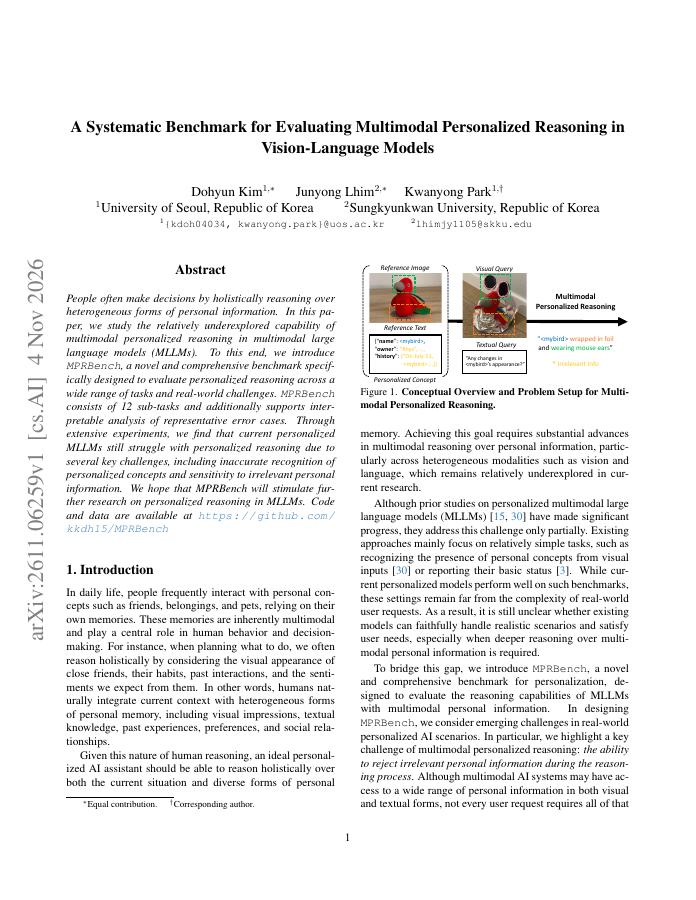
People often make decisions by holistically reasoning over heterogeneous forms of personal information. In this paper, we study the relatively underexplored capability of multimodal personalized reasoning in multimodal large language models (MLLMs). To this end, we introduce MPRBench, a novel and comprehensive benchmark specifically designed to evaluate personalized reasoning across a wide range of tasks and real-world challenges. MPRBench consists of 12 sub-tasks and additionally supports interpretable analysis of representative error cases. Through extensive experiments, we find that current personalized MLLMs still struggle with personalized reasoning due to several key challenges, including inaccurate recognition of personalized concepts and sensitivity to irrelevant personal information. We hope that MPRBench will stimulate further research on personalized reasoning in MLLMs. Code and data are available at https://github.com/kkdh15/MPRBench
A Systematic Benchmark for Evaluating Multimodal Personalized Reasoning of Vision-Language Models
People often make decisions by holistically reasoning over heterogeneous forms of personal information. In this paper, we study the relatively underexplored capability of multimodal personalized reasoning in multimodal large language models (MLLMs).
- Preview
- Year
- 2026
- Hosting
- Abstract onlyARXIV-DEFAULT
Cite
Notes
Only stored in your browser.
Attribution
- Abstract & full text
- arxiv.org/abs/2611.06259ARXIV-DEFAULT
- TL;DR
- Semantic Scholar