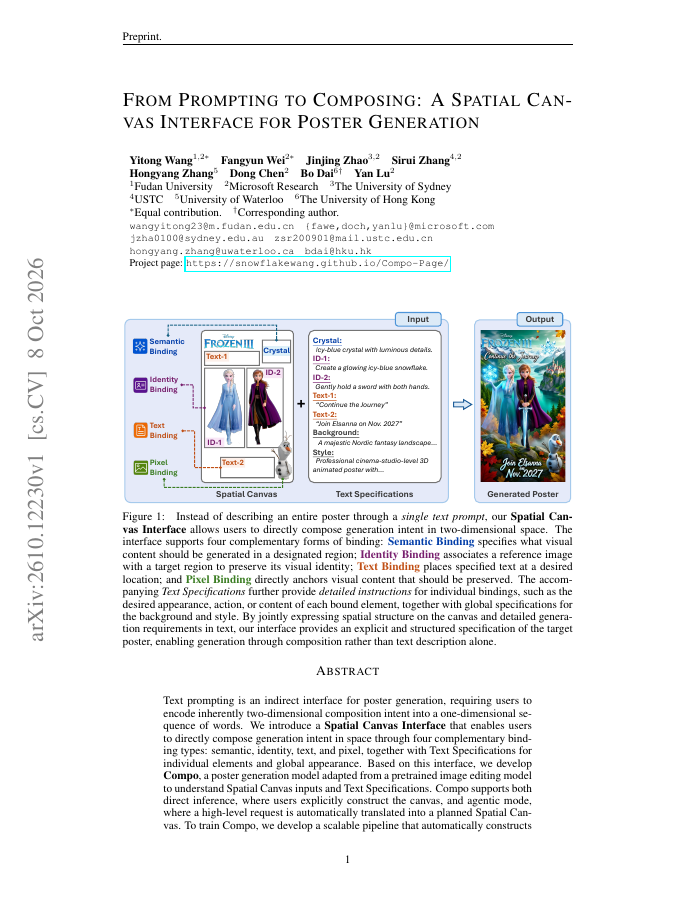
Text prompting is an indirect interface for poster generation, requiring users to encode inherently two-dimensional composition intent into a one-dimensional sequence of words. We introduce a Spatial Canvas Interface that enables users to directly compose generation intent in space through four complementary binding types: semantic, identity, text, and pixel, together with Text Specifications for individual elements and global appearance. Based on this interface, we develop Compo, a poster generation model adapted from a pretrained image editing model to understand Spatial Canvas inputs and Text Specifications. Compo supports both direct inference, where users explicitly construct the canvas, and agentic mode, where a high-level request is automatically translated into a planned Spatial Canvas. To train Compo, we develop a scalable pipeline that automatically constructs supervision data for different binding types and their combinations, enabling efficient adaptation without training a specialized poster generator from scratch. We further introduce a benchmark that evaluates adherence to individual binding types and their joint composition. Experiments show that Compo achieves stronger compositional controllability than both general-purpose image generation models and dedicated poster generation systems while maintaining high visual quality. By decoupling intent specification from visual generation, our work shifts poster generation from prompting toward composing.
From Prompting to Composing: A Spatial Canvas Interface for Poster Generation
Text prompting is an indirect interface for poster generation, requiring users to encode inherently two-dimensional composition intent into a one-dimensional sequence of words.
- Preview
- Year
- 2026
- Stars
- 6
- Hosting
- Abstract onlyARXIV-DEFAULT
Cite
Notes
Only stored in your browser.
Attribution
- Abstract & full text
- arxiv.org/abs/2610.12230ARXIV-DEFAULT
- TL;DR
- Semantic Scholar