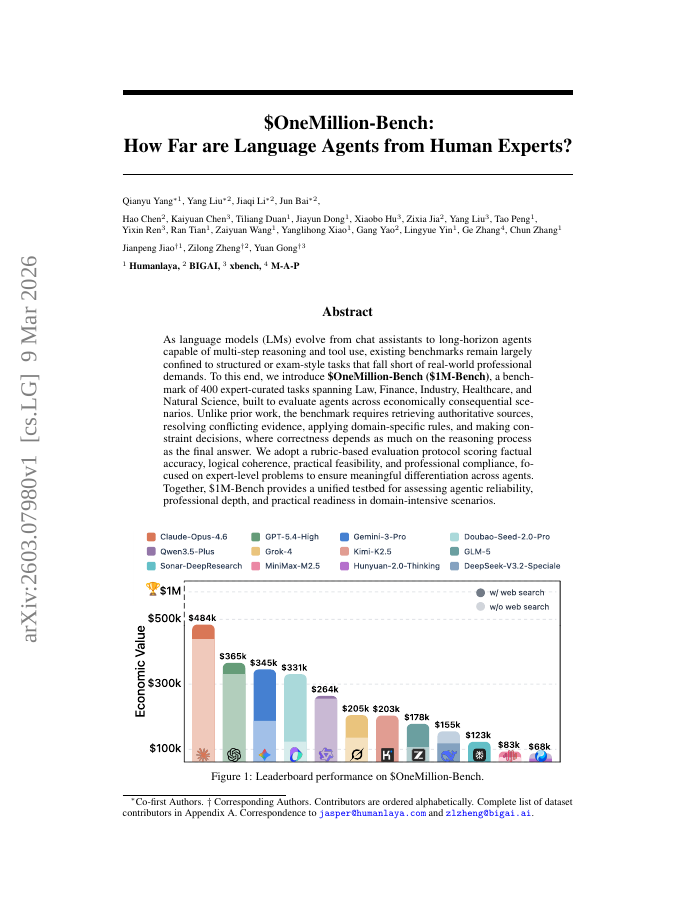
As language models (LMs) evolve from chat assistants to long-horizon agents capable of multi-step reasoning and tool use, existing benchmarks remain largely confined to structured or exam-style tasks that fall short of real-world professional demands. To this end, we introduce \OneMillion-Bench (\OMB), a benchmark of 400 expert-curated tasks spanning Law, Finance, Industry, Healthcare, and Natural Science, built to evaluate agents across economically consequential scenarios. Unlike prior work, the benchmark requires retrieving authoritative sources, resolving conflicting evidence, applying domain-specific rules, and making constraint decisions, where correctness depends as much on the reasoning process as the final answer. We adopt a rubric-based evaluation protocol scoring factual accuracy, logical coherence, practical feasibility, and professional compliance, focusing on expert-level problems to ensure meaningful differentiation across agents. Together, $OMB provides a unified testbed for assessing agentic reliability, professional depth, and an indicator of practical readiness in domain-intensive scenarios.
\$OneMillion-Bench: How Far are Language Agents from Human Experts?
As language models (LMs) evolve from chat assistants to long-horizon agents capable of multi-step reasoning and tool use, existing benchmarks remain largely confined to structured or exam-style tasks that fall short of real-world professional demands.
- Preview
- Year
- 2026
- Venue
- arXiv 2026
- Authors
- 22
- Hosting
- Excerpt onlyCC-BY-NC-4.0
Cite
Notes
Only stored in your browser.
Attribution
- Abstract & full text
- arxiv.org/abs/2603.07980CC-BY-NC-4.0
- TL;DR
- Semantic Scholar