30 Sep 2026
Despite the widespread use of Low-Rank Adaptation (LoRA), little is known about its dynamics in continual learning and the mechanisms by which low-rank updates affect catastrophic forgetting.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,712 papers.
30 Sep 2026
Despite the widespread use of Low-Rank Adaptation (LoRA), little is known about its dynamics in continual learning and the mechanisms by which low-rank updates affect catastrophic forgetting.
30 Sep 2026
We evaluate Jev on ten dataset-defined application labels in CESNET-QUICEXT-25 using only the first ten packets' sizes, directions, and inter-packet times. To the best of our knowledge, this is the first empirical study of general-purpose decision models, represented here by…
30 Sep 2026
Adapting a language model to a specialized corpus means choosing which instruction-tuning tasks to train on under a fixed budget, and testing one choice costs a fine-tuning run. Common heuristics add more source tasks or pick sources similar to the target.
30 Sep 2026
Amortized simulation-based inference (SBI), which is trained on radiative-transfer simulators, recovers exoplanet atmospheres accurately on synthetic James Webb Space Telescope (JWST) spectra but collapses when it comes to real reduced spectra.
30 Sep 2026
AI reviewers can assign different judgments to manuscripts that report the same science in different wording, potentially rewarding rhetorical optimization over scientific improvement.
30 Sep 2026
Fairness assessment in algorithmic decisions that affect individuals, such as credit scoring, often relies on parity measures calculated at the aggregate group level. Such measures may not reveal which individuals experience unfairness or which explanatory factors contribute to…
30 Sep 2026
Laurito et al. (PNAS 2025) showed that large language models choosing between two descriptions of the same product, paper or film prefer the description written by a language model over the one written by a person, by a wide margin over what human judges do.
30 Sep 2026
Making decisions despite conflicting norms and incomplete or unreliable information is a fundamental challenge for autonomous systems. We introduce a simple doxastic deontic logic for this setting: a classically reducible fragment of Chellas' Minimal Deontic Logic, extended with…
30 Sep 2026
Looped models reason by applying the same block of weights many times, so compressing that block saves memory traffic on every loop. Compressed looped models, however, often collapse, and the collapse is usually blamed on rounding error that accumulates from loop to loop.
30 Sep 2026
Matching problems are ubiquitous in data science as they enable the alignment of structured objects and distributions. While existing solvers are often tailored to specific matching formulations, we unify a broad class of such problems within a common mathematical and…
29 Sep 2026
LLMs trained with Chain-of-thought excel in reasoning capability, but often come with excessive token cost. We find that the core of reasoning capacity lies in the Thinking model's weight component within the null space of a projection defined by the corresponding Non-thinking…
29 Sep 2026
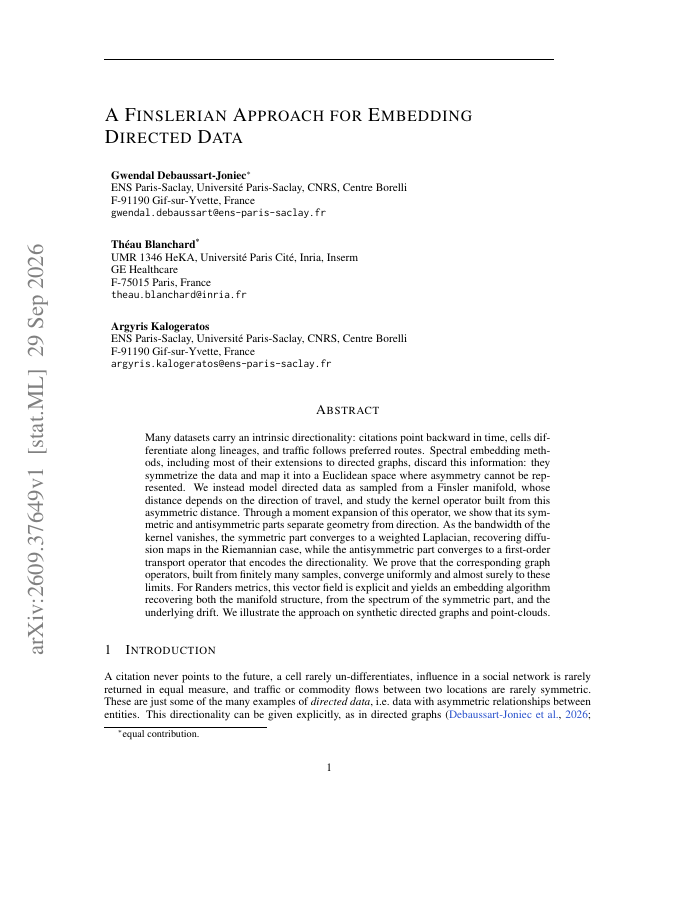
Many datasets carry an intrinsic directionality: citations point backward in time, cells differentiate along lineages, and traffic follows preferred routes. Spectral embedding methods, including most of their extensions to directed graphs, discard this information: they…
29 Sep 2026
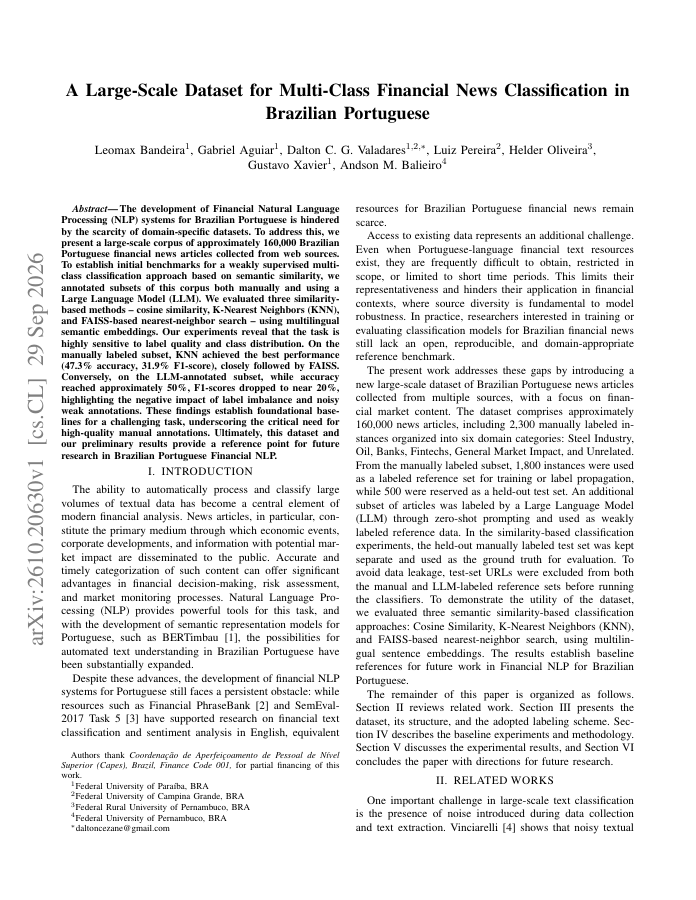
The development of Financial Natural Language Processing (NLP) systems for Brazilian Portuguese is hindered by the scarcity of domain-specific datasets. To address this, we present a large-scale corpus of approximately 160,000 Brazilian Portuguese financial news articles…
29 Sep 2026
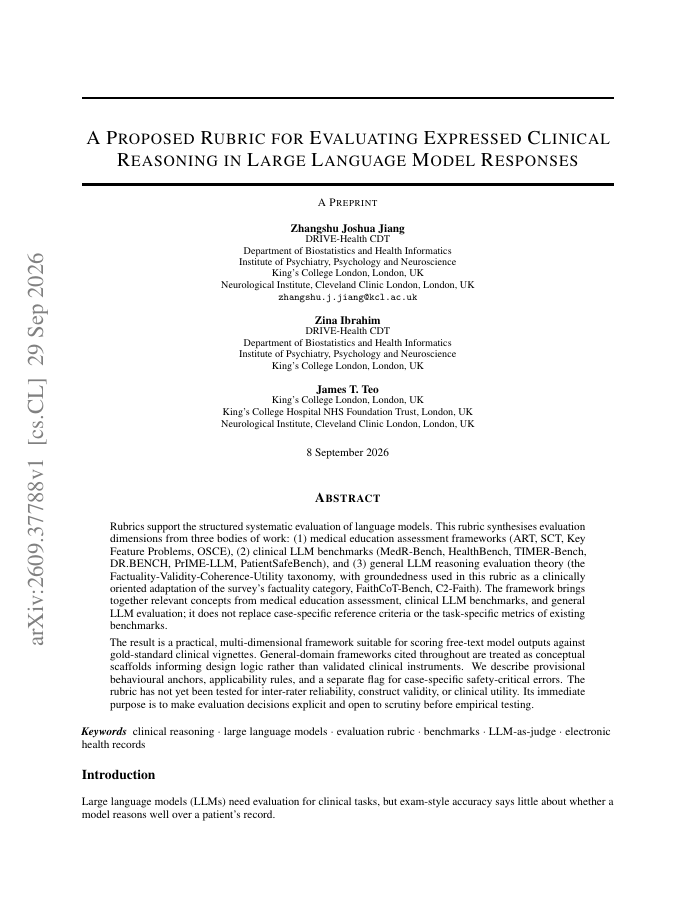
We propose a rubric for assessing expressed clinical reasoning in model responses, drawing on three bodies of work: medical education assessment frameworks (ART, SCT, Key Feature Problems and OSCE); clinical LLM benchmarks (MedR-Bench, HealthBench, TIMER-Bench, DR.
29 Sep 2026
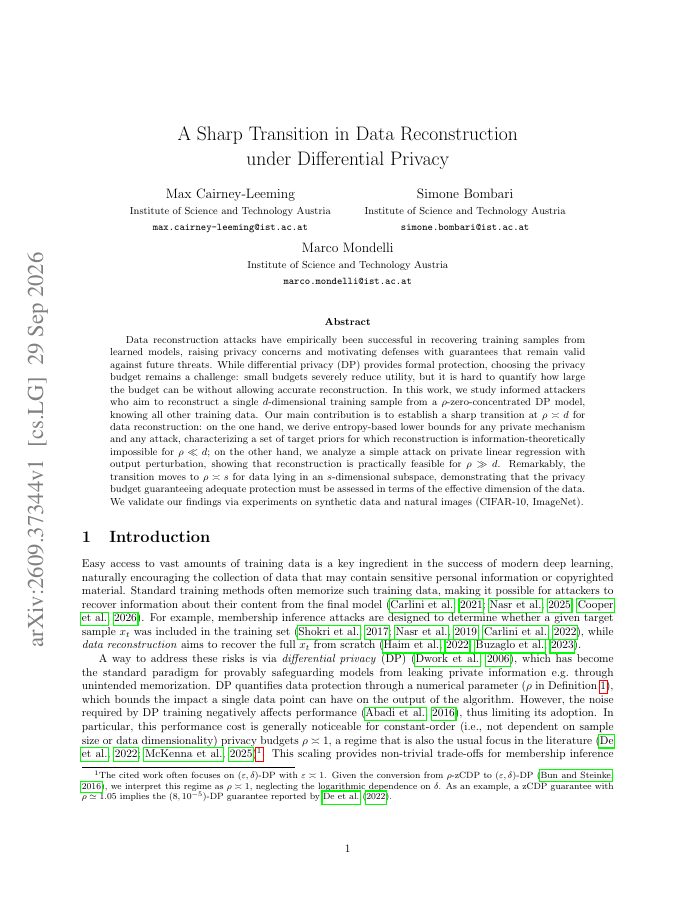
Data reconstruction attacks have empirically been successful in recovering training samples from learned models, raising privacy concerns and motivating defenses with guarantees that remain valid against future threats.
28 Sep 2026
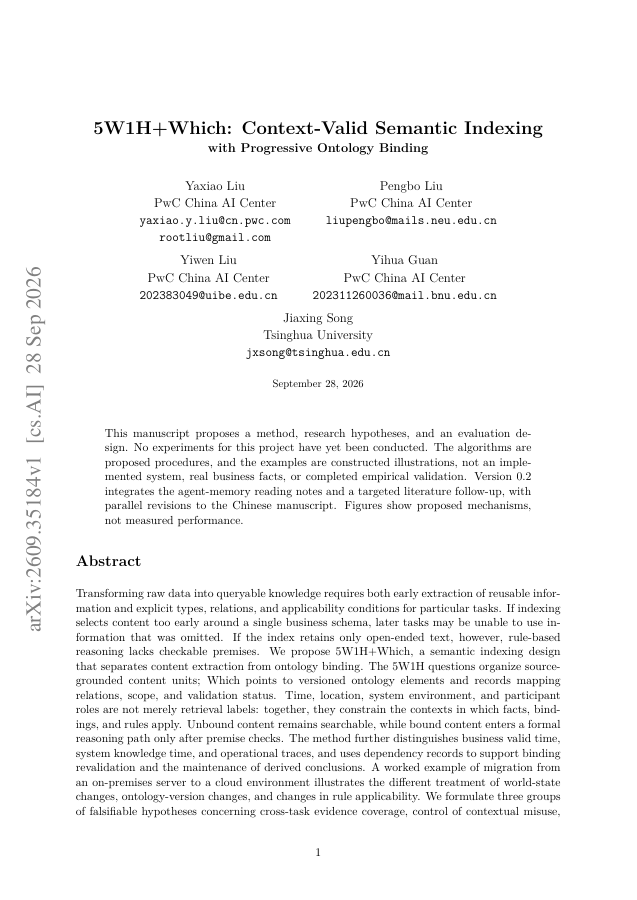
Semantic indexing must preserve reusable source information without committing too early to one business schema, while providing checkable premises for reasoning. We propose 5W1H+Which, a design that separates source-grounded content extraction from progressive ontology binding.
28 Sep 2026
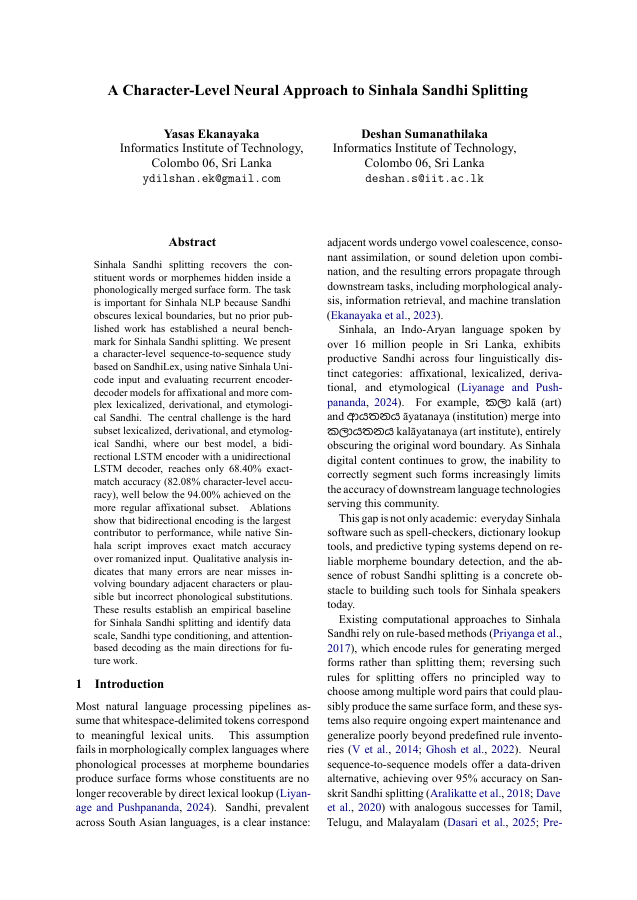
Sinhala Sandhi splitting recovers the constituent words or morphemes hidden inside a phonologically merged surface form. The task is important for Sinhala NLP because Sandhi obscures lexical boundaries, but no prior published work has established a neural benchmark for Sinhala…
28 Sep 2026
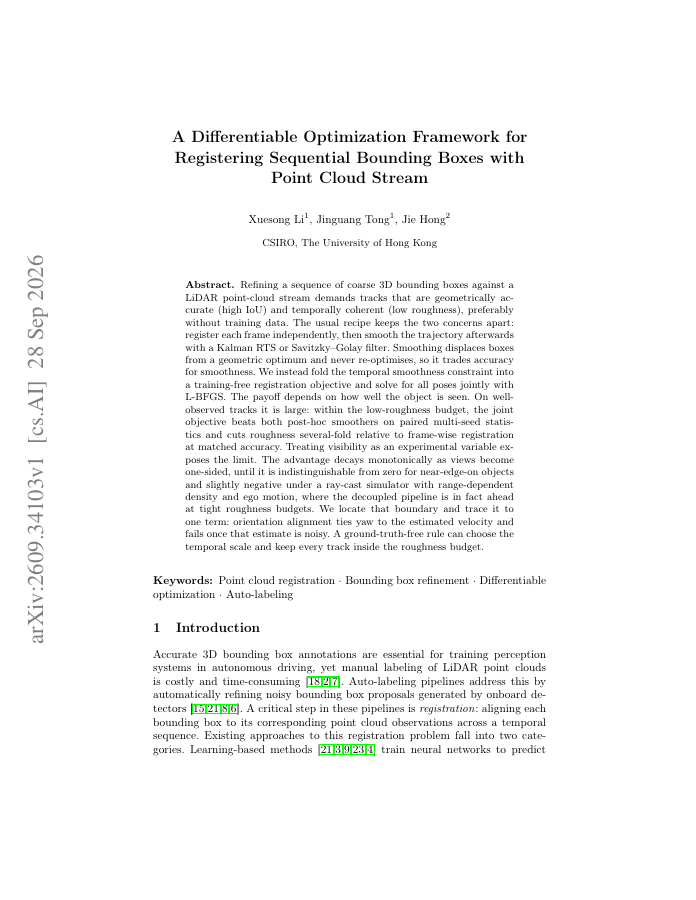
Refining a sequence of coarse 3D bounding boxes against a LiDAR point-cloud stream demands tracks that are geometrically accurate (high IoU) and temporally coherent (low roughness), preferably without training data.
28 Sep 2026
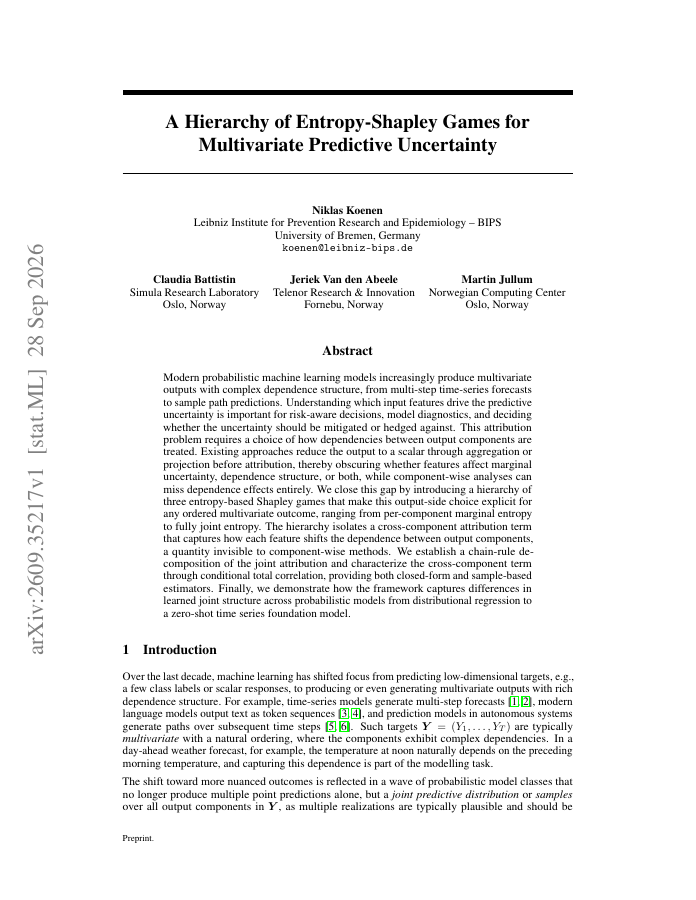
Modern probabilistic machine learning models increasingly produce multivariate outputs with complex dependence structure, from multi-step time-series forecasts to sample path predictions.
28 Sep 2026
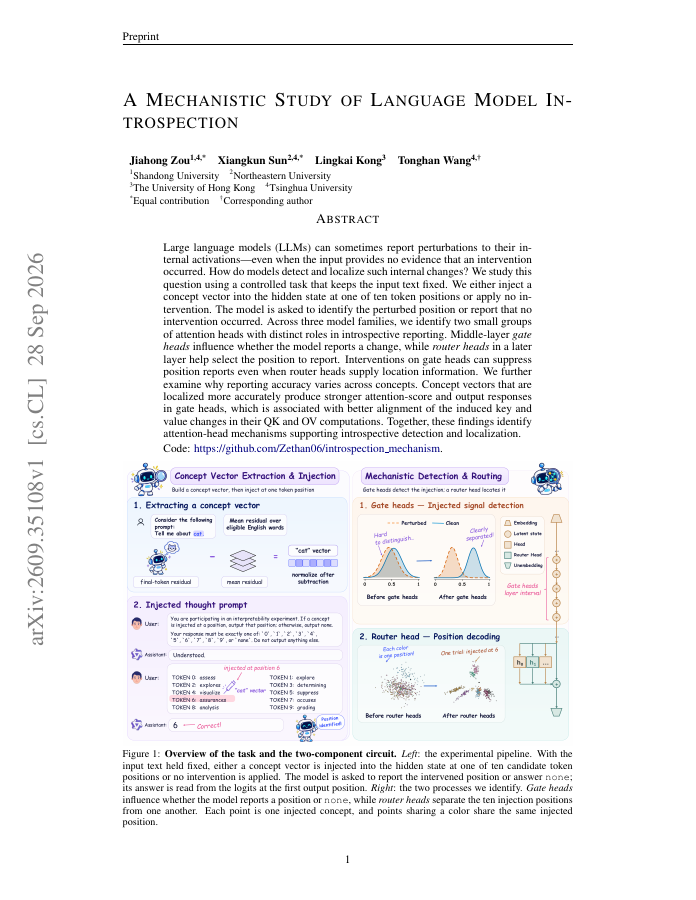
Large language models (LLMs) can sometimes report perturbations to their internal activations---even when the input provides no evidence that an intervention occurred. How do models detect and localize such internal changes? We study this question using a controlled task that…
28 Sep 2026
Mixture-of-Experts (MoE) models repeatedly route tokens to sparse subsets of experts, but conventional routers expose no routing-specific record of how cross-layer influences accumulate.
28 Sep 2026
When a doctor, a judge, or an engineer must decide whether to trust an AI model's output, they cannot avoid asking what the model understands. Purely mathematical or statistical descriptions struggle to distinguish trustworthy from untrustworthy outputs without reintroducing the…
27 Sep 2026
Tracking any point of a dynamic scene in metric 3D - in absolute meters, not up to an unknown scale - underpins 3D and 4D reconstruction, robot navigation, and autonomous driving, where decisions are made in meters, not pixels.
27 Sep 2026
When post-training large language models on tasks with semi-verifiable rewards, there are many factors (training steps, base model size, training order, data quality, verifier accuracy, etc.) that practitioners must contend with to maximize model performance.