27 Sep 2026
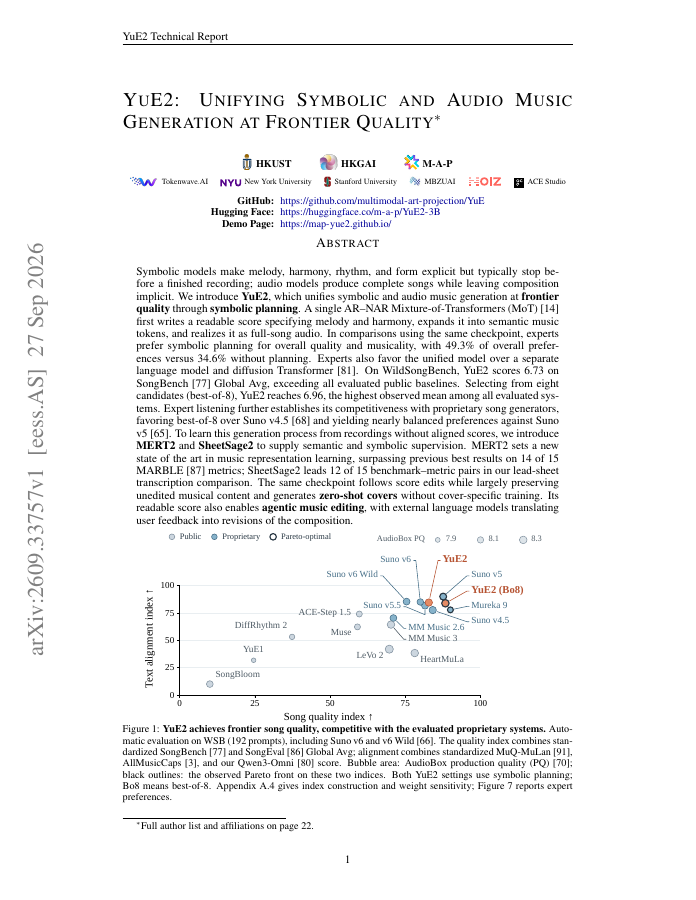
Symbolic models make melody, harmony, rhythm, and form explicit but typically stop before a finished recording; audio models produce complete songs while leaving composition implicit.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,656 papers.
27 Sep 2026
Symbolic models make melody, harmony, rhythm, and form explicit but typically stop before a finished recording; audio models produce complete songs while leaving composition implicit.
6 Oct 2026
Recent advances in world models have enabled increasingly realistic visual synthesis. However, these generated environments remain largely silent. Bringing sound to world models poses three core challenges: real-time generation to keep pace with interactive video streams,…
1 Jun 2026
We introduce Cosmos 3, a family of omnimodal world models designed to jointly process and generate language, image, video, audio, and action sequences within a unified mixture-of-transformers architecture.
8 Sep 2026
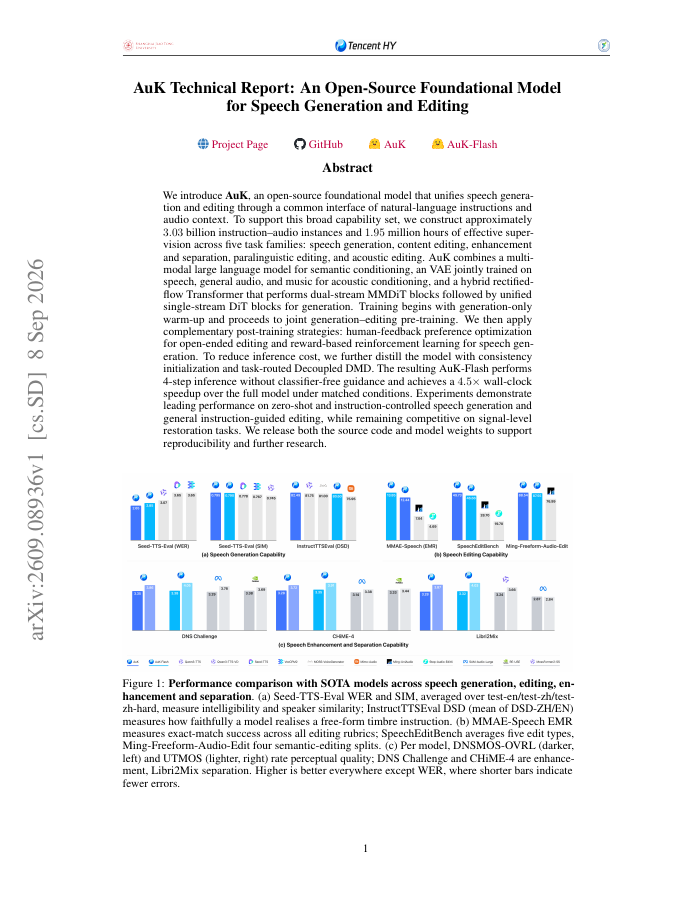
We introduce AuK, an open-source foundational model that unifies speech generation and editing through a common interface of natural-language instructions and audio context.