Bo Zheng, Quanjian Song, Yefeng Shen et al. · 15 May 2026
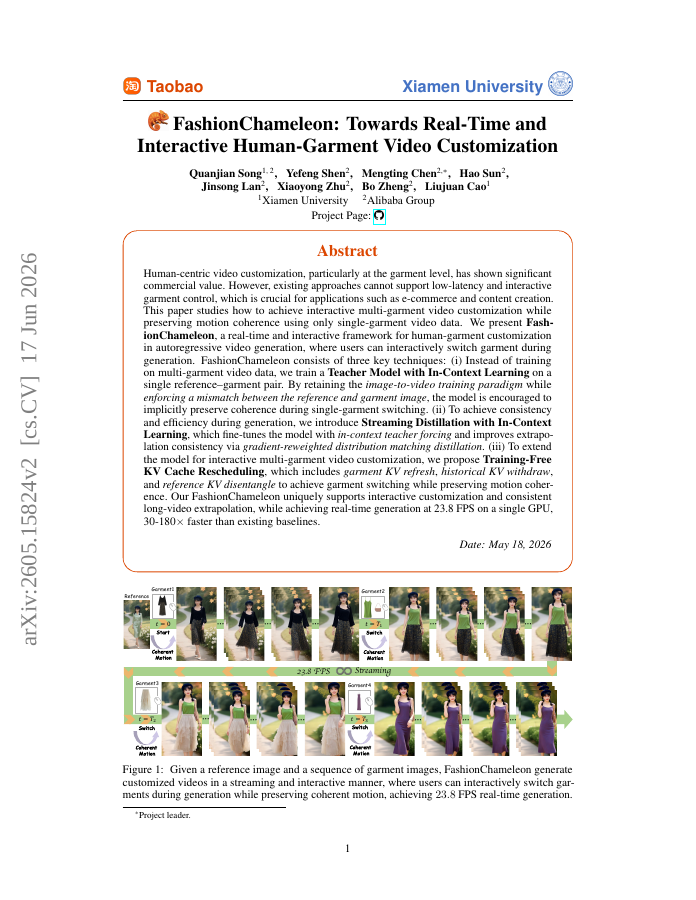
Human-centric video customization, particularly at the garment level, has shown significant commercial value.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,347 papers.
Bo Zheng, Quanjian Song, Yefeng Shen et al. · 15 May 2026
Human-centric video customization, particularly at the garment level, has shown significant commercial value.
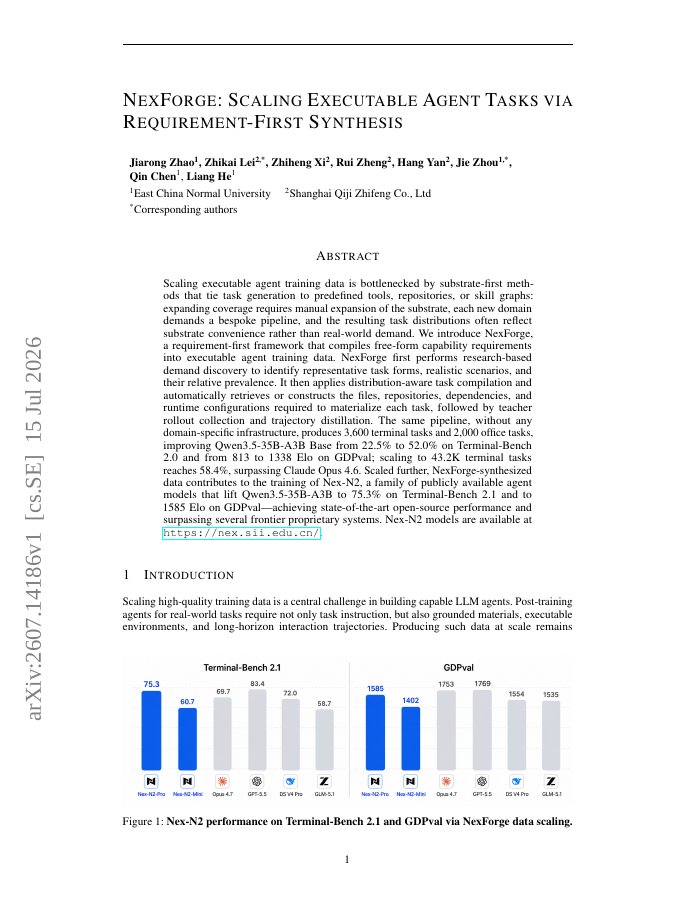
15 Jul 2026
Scaling executable agent training data for LLM post-training is bottlenecked by substrate-bound methods that tie task generation to predefined tools, repositories, or skill graphs: expanding coverage requires manual substrate engineering, each new domain demands a bespoke…
16 Sep 2026
Mixture-of-experts (MoE) inference on consumer hardware is bounded by weight memory: a 35B-class model is 19.5GB at 4-bit, and sparsity shrinks the compute per token, not the bytes that must be held.
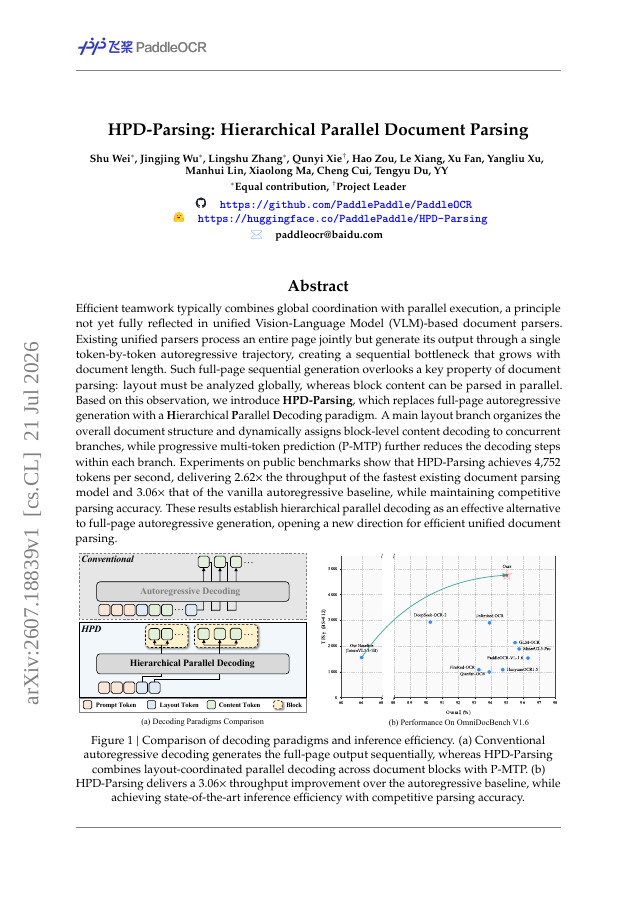
21 Jul 2026
Efficient teamwork typically combines global coordination with parallel execution, a principle not yet fully reflected in unified Vision-Language Model (VLM)-based document parsers.
Yifan Yang, Ziyang Gong, Weiquan Huang et al. · 22 May 2026
Agent skills today are hand-crafted, generated one-shot, or evolved through loosely controlled self-revision, none of which behaves like a deep-learning optimizer for the skill, and none of which reliably improves over its starting point under feedback.
29 May 2026
LLM agents are increasingly expected not only to complete isolated tasks, but also to carry bounded representations of human expertise, judgment, and interaction style. Building such person-grounded agents remains difficult because actionable knowledge associated with a person…
27 Sep 2026
As large language models advance, AI agents are moving beyond isolated, domain-specific tasks toward long-horizon, cross-domain workflows. This transition exposes two challenges: increasing harness complexity makes manual design difficult to scale, while tighter coupling to…
19 Sep 2026
Educational foundation models must solve problems, understand curriculum structure, diagnose learner difficulties, and provide appropriate instructional support. Existing educational language models often focus on either problem solving or tutoring, with training mixtures…
25 Aug 2026
Scientific agents increasingly analyze data, execute code, and produce research artifacts, yet most benchmarks emphasize final answers, isolated programs, or a single domain. We introduce FrontierChallenge, a cross-domain benchmark comprising 300 end-to-end scientific workflows.
4 Sep 2026
Recent advances in automatic rigging now deliver animation-ready 3D assets at scale, yet generating the motion to drive them remains a bottleneck. Existing learned animators are topology-constrained: they rely on category-specific templates or require per-skeleton fine-tuning…
8 Sep 2026
In this work, we present Gander, a native multimodal duplex interaction model that builds on MiniCPM-o 4.5 and is further adapted for realtime interaction with an asynchronous agent loop.
8 Sep 2026
Monocular depth estimation is a ubiquitous yet highly ill-posed computer vision task, with downstream applications in scene reconstruction, computational photography, and robotics, among others.
17 Sep 2026
As coding agents move from supervised code completion to unattended, around-the-clock exploration, their work expands from isolated predictions into long trajectories of reasoning, tool use, and feedback.
22 Jun 2026
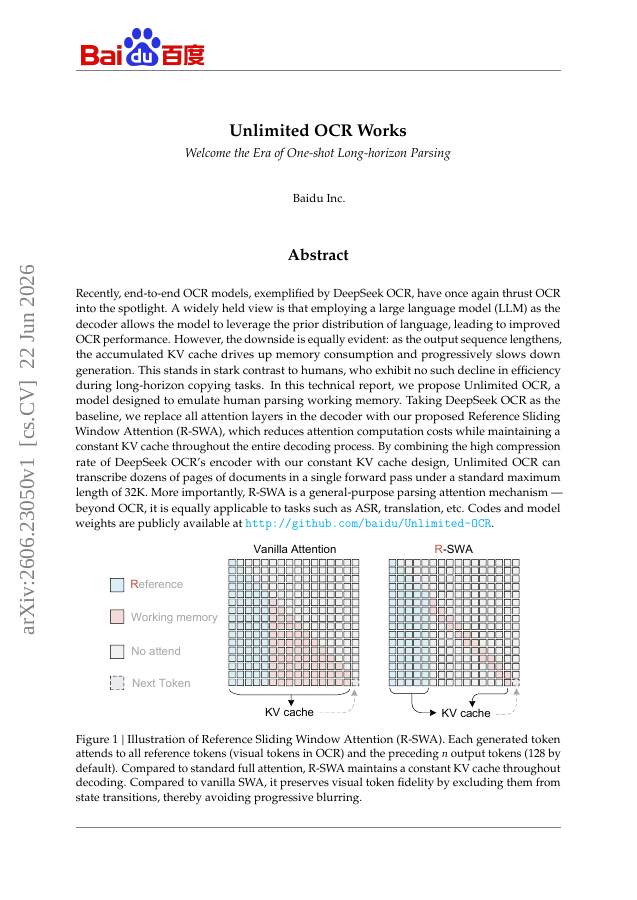
Recently, end-to-end OCR models, exemplified by DeepSeek OCR, have once again thrust OCR into the spotlight. A widely held view is that employing a large language model (LLM) as the decoder allows the model to leverage the prior distribution of language, leading to improved OCR…
15 Sep 2026
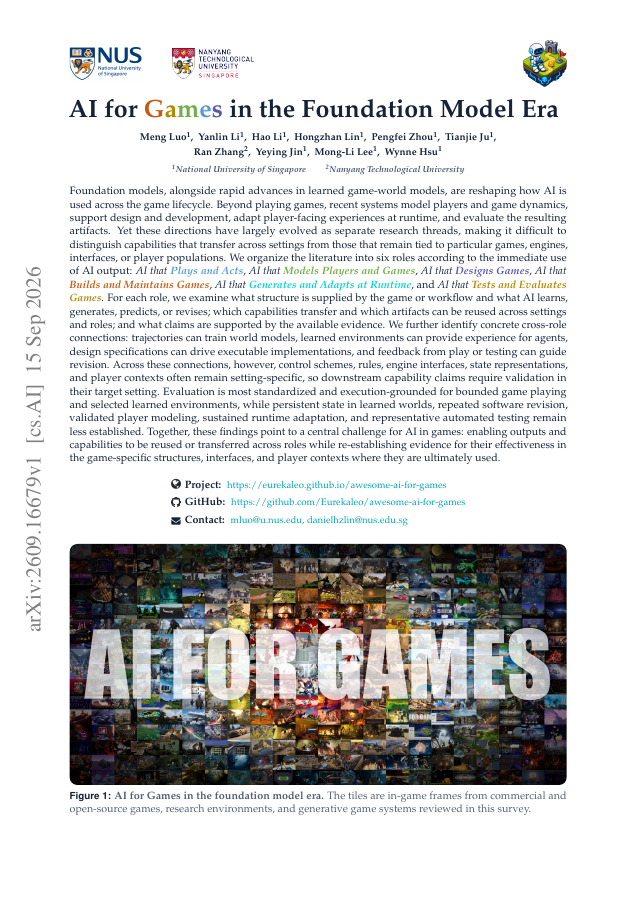
Foundation models, alongside advances in learned game-world models, are reshaping AI across the game lifecycle. Beyond playing games, recent systems model players and game dynamics, support design and development, adapt player-facing experiences at runtime, and evaluate…
27 Sep 2026
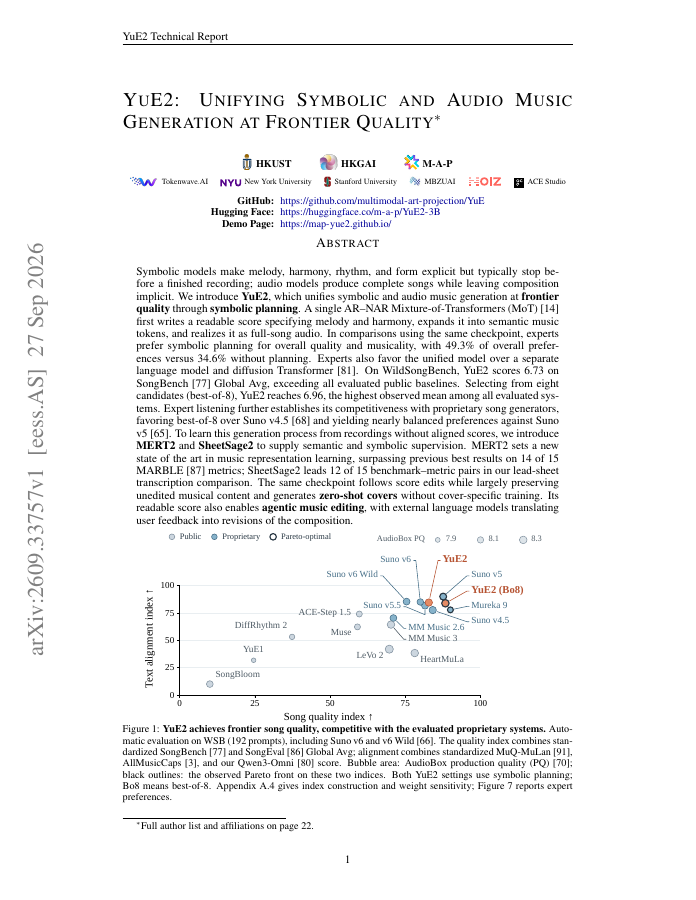
Symbolic models make melody, harmony, rhythm, and form explicit but typically stop before a finished recording; audio models produce complete songs while leaving composition implicit.
29 Sep 2026
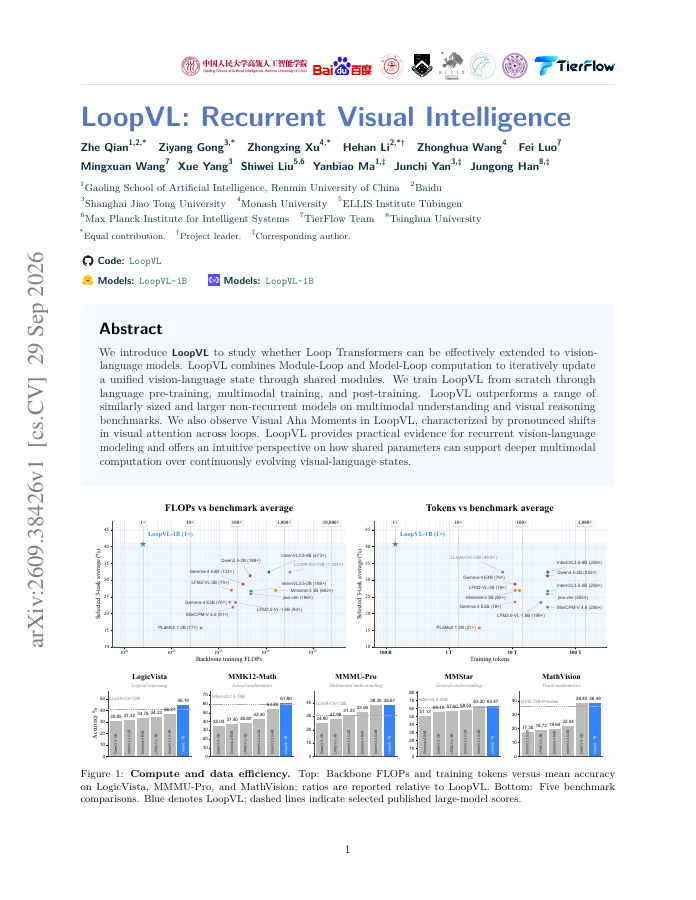
We introduce LoopVL to study whether Loop Transformers can be effectively extended to vision- language models. LoopVL combines Module-Loop and Model-Loop computation to iteratively update a unified vision-language state through shared modules.
4 Sep 2026
Co-work agents execute complex workflows that combine information gathering, tool use, coding, and file manipulation across many model invocations. Because cost and latency accumulate over the full episode, their practical value depends not only on peak capability but also on…
24 Aug 2026
Language models are sequential processors, but long-horizon agency requires external information and computation beyond model weights and active context. Prime Agent is an open-source harness for long-horizon evaluation and coding-agent workflows.
15 Aug 2026
Long-horizon agents can fail even when their underlying models can solve the constituent steps. They may lose track of mutable state, fail to reactivate lessons from earlier executions, skip known procedures, or stop prematurely.
9 Jul 2026
Existing methods for automatic music transcription are often limited to single-instrument recordings or fail on complex, real music mixes. Although previous work utilizes synthetic training data, the resulting models generalize poorly, leading to largely unusable transcription…
17 Sep 2026
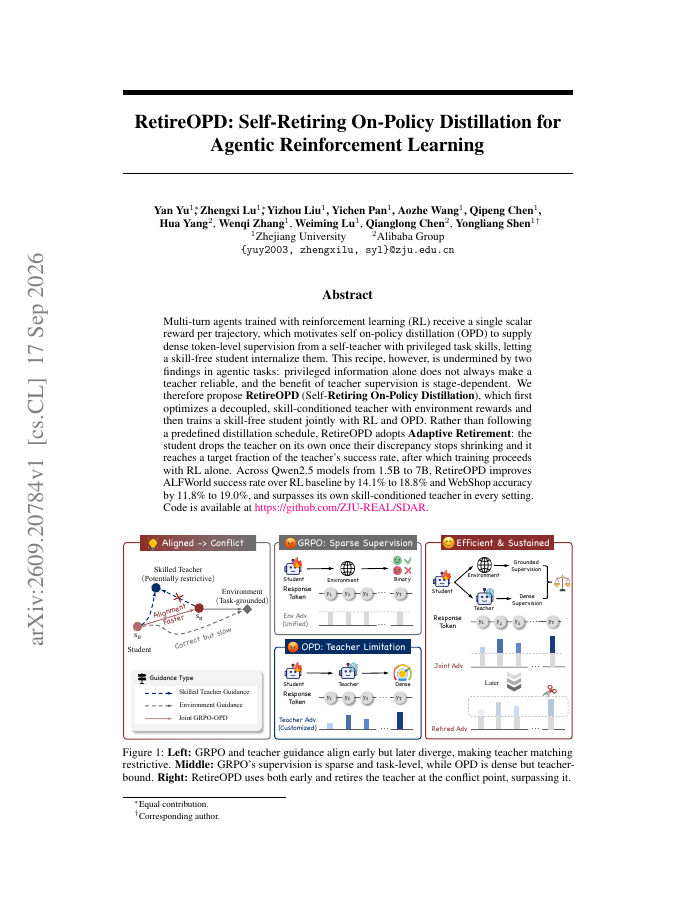
Multi-turn agents trained with reinforcement learning (RL) receive a single scalar reward per trajectory, which motivates self on-policy distillation (OPD) to supply dense token-level supervision from a self-teacher with privileged task skills, letting a skill-free student…
Lin-Zhuo Chen, Jian Gao, Yihang Chen et al. · 15 Apr 2026
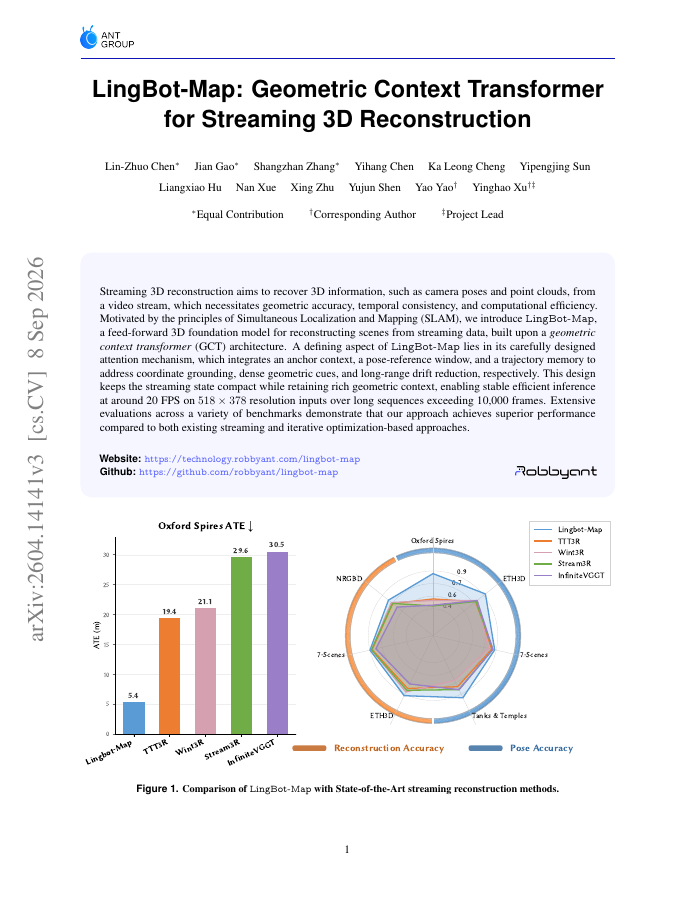
Streaming 3D reconstruction aims to recover 3D information, such as camera poses and point clouds, from a video stream, which necessitates geometric accuracy, temporal consistency, and computational efficiency.
21 Aug 2026
E-commerce live streaming requires omni-modal understanding of noisy, temporally extended streams, where product facts are distributed across speech, video frames, product images, overlaid text, and user queries.