19 Nov 2026
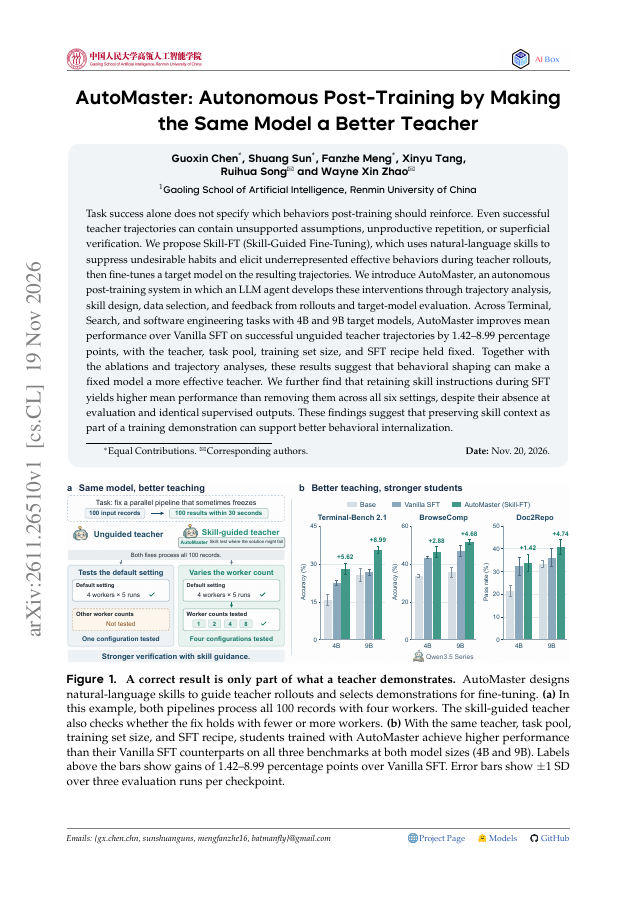
Task success alone does not specify which behaviors post-training should reinforce. Even successful teacher trajectories can contain unsupported assumptions, unproductive repetition, or superficial verification.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 23,060 papers.
19 Nov 2026
Task success alone does not specify which behaviors post-training should reinforce. Even successful teacher trajectories can contain unsupported assumptions, unproductive repetition, or superficial verification.
16 Nov 2026
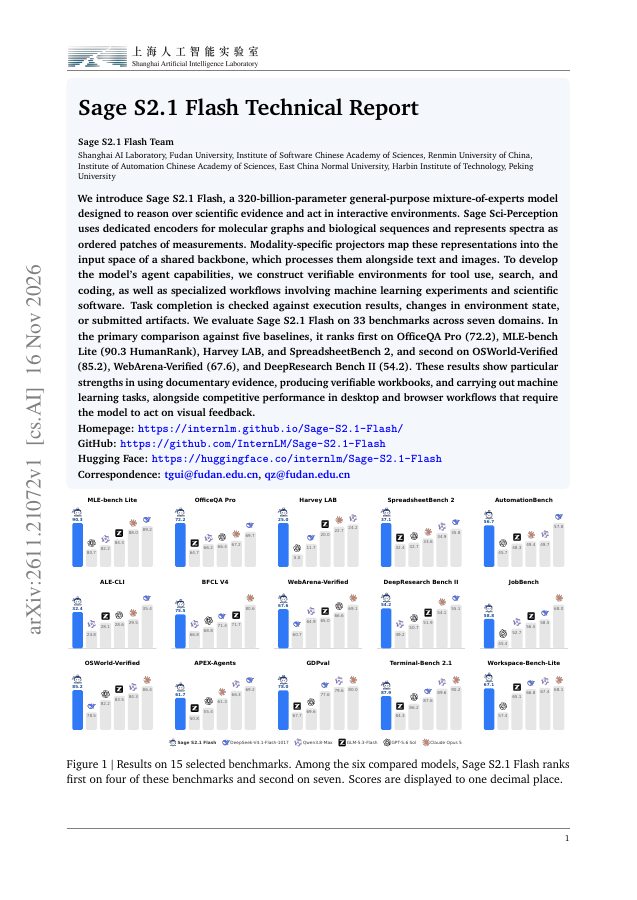
We introduce Sage S2.1 Flash, a 320-billion-parameter general-purpose mixture-of-experts model designed to reason over scientific evidence and act in interactive environments.
9 Nov 2026
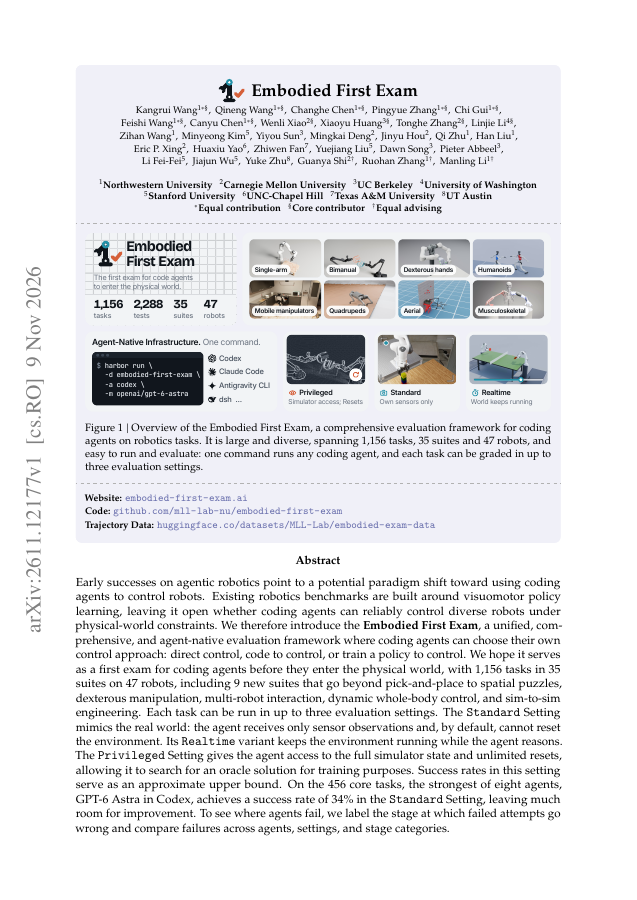
Early successes on agentic robotics point to a potential paradigm shift toward using coding agents to control robots. Existing robotics benchmarks are built around visuomotor policy learning, leaving it open whether coding agents can reliably control diverse robots under…
16 Nov 2026
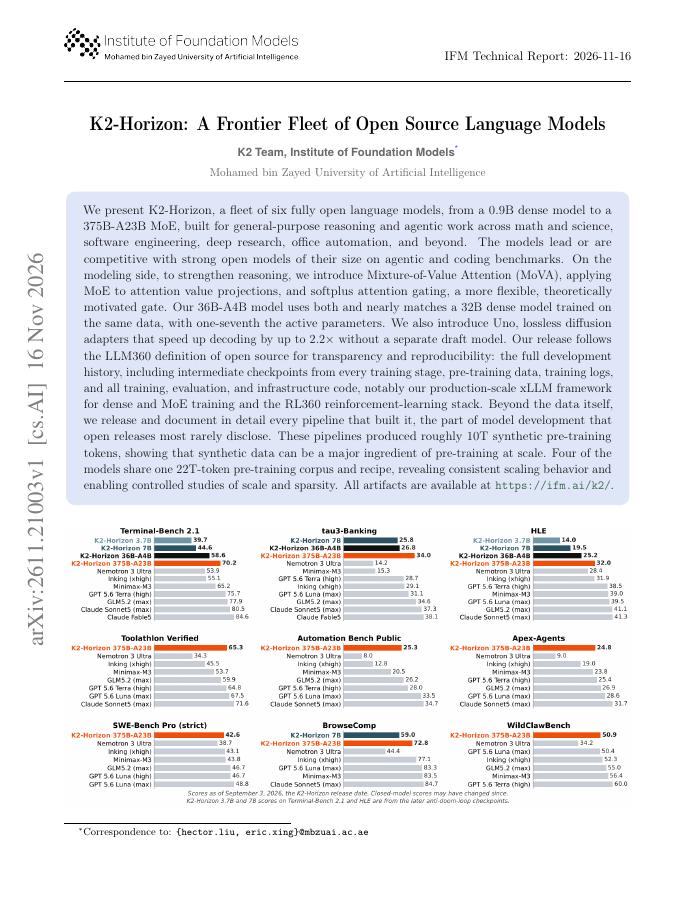
We present K2-Horizon, a fleet of six fully open language models, from a 0.9B dense model to a 375B-A23B MoE, built for general-purpose reasoning and agentic work across math and science, software engineering, deep research, office automation, and beyond.
5 Nov 2026
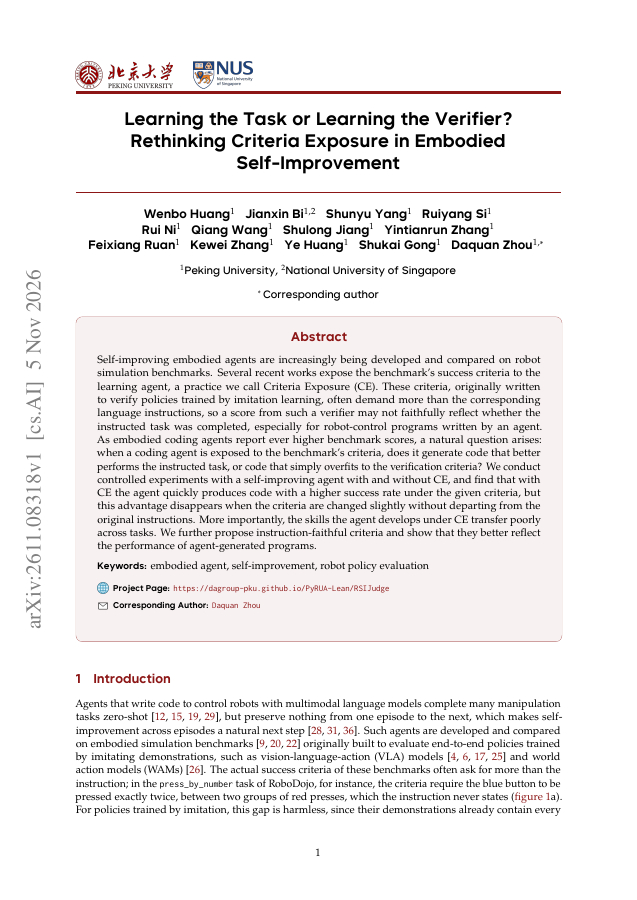
Self-improving embodied agents are increasingly being developed and compared on robot simulation benchmarks. Several recent works expose the benchmark's success criteria to the learning agent, a practice we call Criteria Exposure (CE).
5 Nov 2026
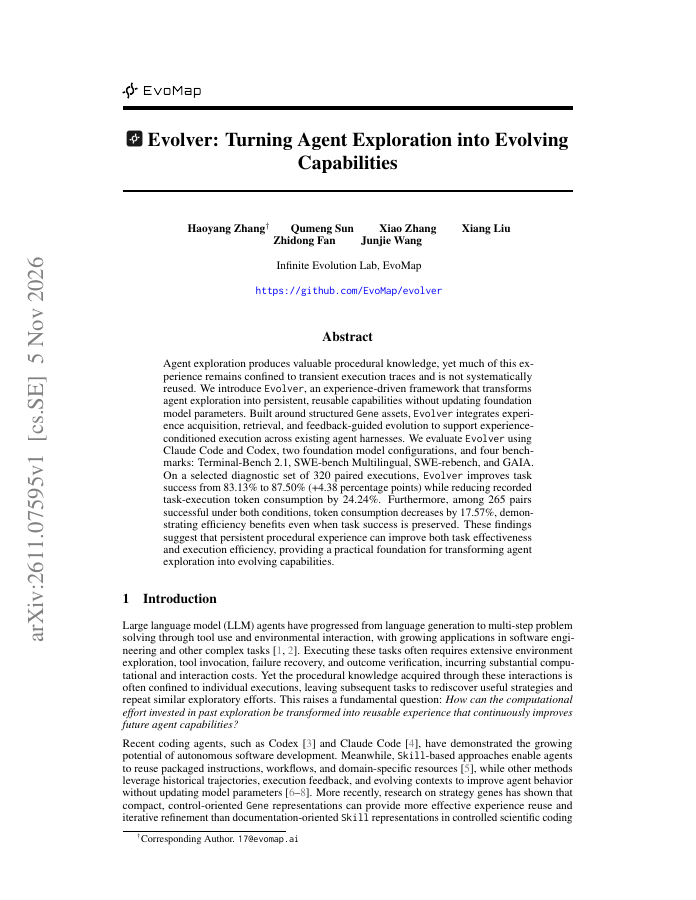
Agent exploration produces valuable procedural knowledge, yet much of this experience remains confined to transient execution traces and is not systematically reused. We introduce Evolver, an experience-driven framework that transforms agent exploration into persistent, reusable…
15 Nov 2026
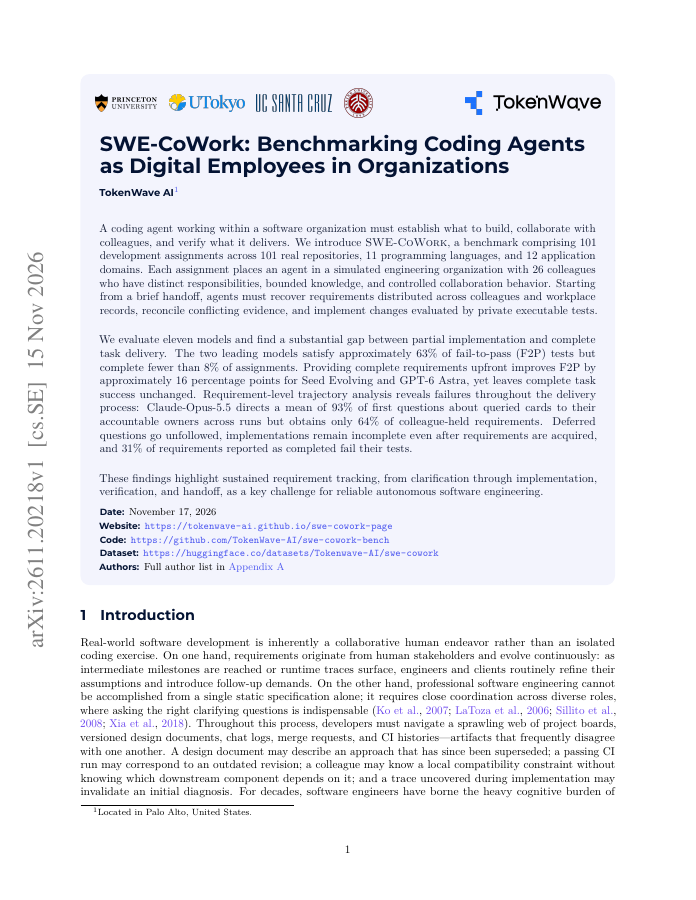
A coding agent working within a software organization must establish what to build, collaborate with colleagues, and verify what it delivers. We introduce SWE-CoWork, a benchmark comprising 101 development assignments across 101 real repositories, 11 programming languages, and…
16 Nov 2026
Application optimization requires coding agents to discover useful changes and coordinate them across a complete program while preserving the required computation. We introduce Accelerate Bench, a benchmark of 32 CPU optimization tasks adapted from scientific applications and…
16 Nov 2026
Training coding agents for long-horizon tasks requires environments with verifiable feedback. Existing pipelines often follow a linear process that ends with validation, establishing usability but providing little guidance on improving training value.