13 Nov 2026
We introduce Gamer, a generalist agent framework built for long-horizon tasks in complex interactive environments. Its end-to-end architecture combines perception, memory management, and multi-step reasoning.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 23,060 papers.
13 Nov 2026
We introduce Gamer, a generalist agent framework built for long-horizon tasks in complex interactive environments. Its end-to-end architecture combines perception, memory management, and multi-step reasoning.
19 Nov 2026
Task success alone does not specify which behaviors post-training should reinforce. Even successful teacher trajectories can contain unsupported assumptions, unproductive repetition, or superficial verification.
13 Nov 2026
Speech tokenizers convert audio into discrete units, enabling language models to process and generate speech. The goal is to learn compact, text-like representations while preserving enough detail to reconstruct a speaker's voice and delivery.
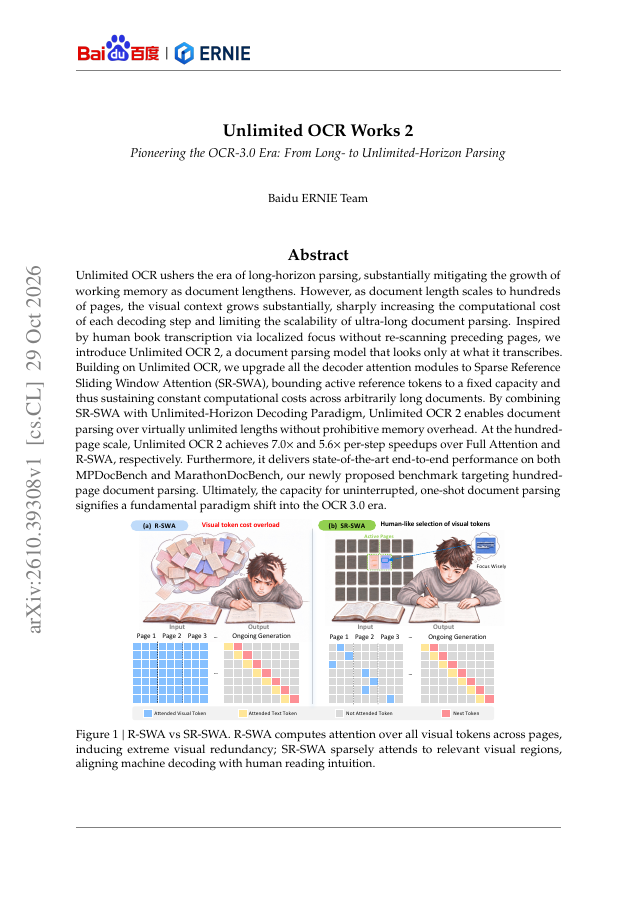
29 Oct 2026
Unlimited OCR ushers the era of long-horizon parsing, substantially mitigating the growth of working memory as document lengthens. However, as document length scales to hundreds of pages, the visual context grows substantially, sharply increasing the computational cost of each…
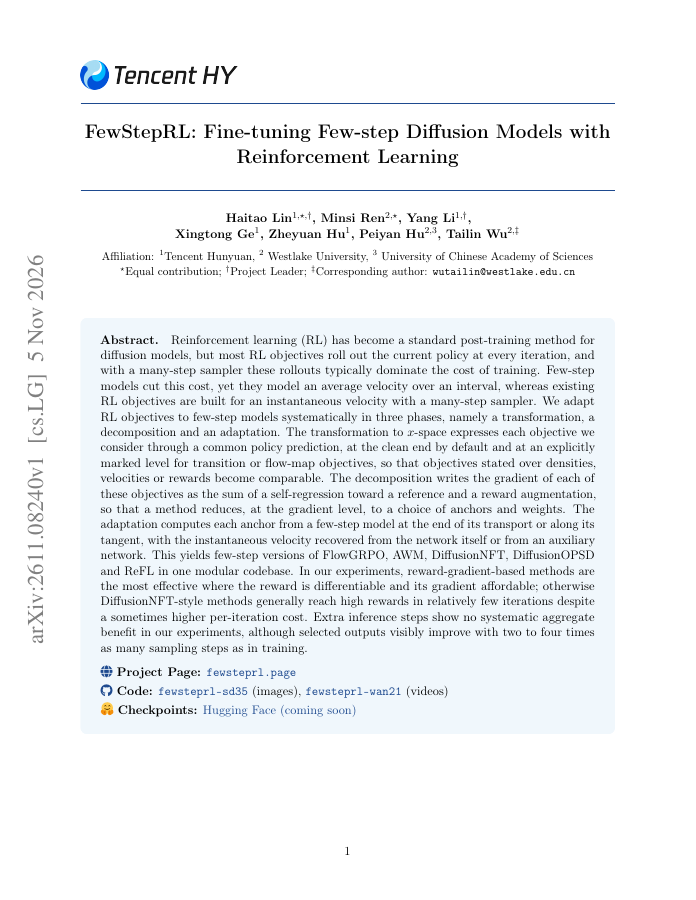
5 Nov 2026
Reinforcement learning (RL) has become a standard post-training method for diffusion models, but most RL objectives roll out the current policy at every iteration, and with a many-step sampler these rollouts typically dominate the cost of training.
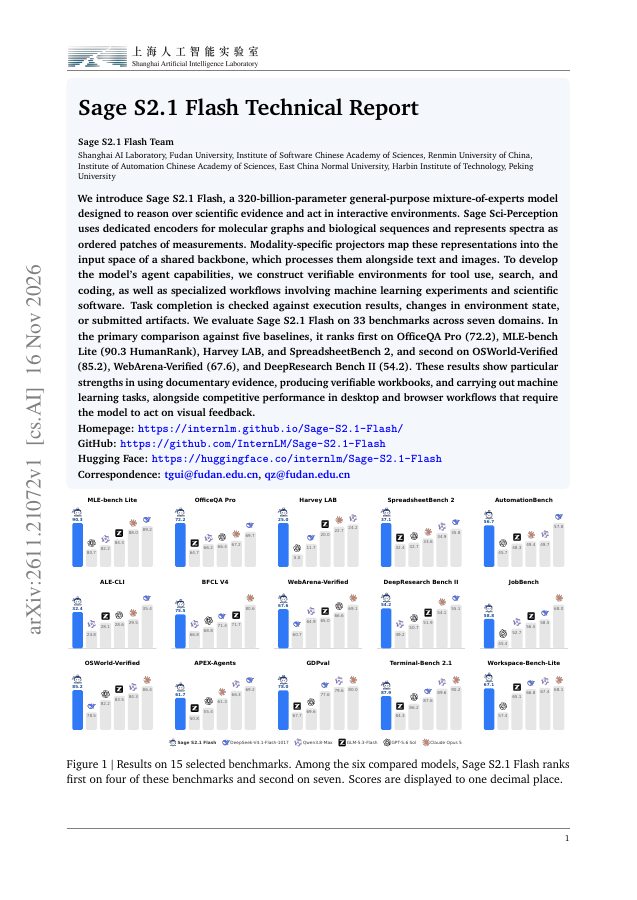
16 Nov 2026
We introduce Sage S2.1 Flash, a 320-billion-parameter general-purpose mixture-of-experts model designed to reason over scientific evidence and act in interactive environments.
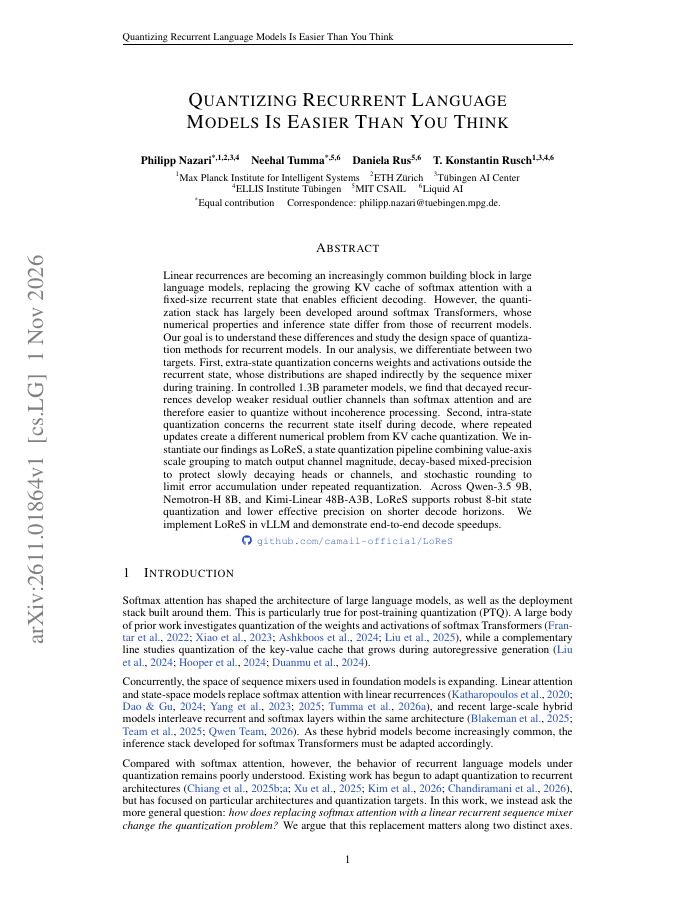
1 Nov 2026
Linear recurrences are becoming an increasingly common building block in large language models, replacing the growing KV cache of softmax attention with a fixed-size recurrent state that enables efficient decoding.
30 Oct 2026
Agent harnesses govern how language models act in an environment; designing their policies by hand is difficult, while automated techniques require representative datasets and costly executions.
9 Nov 2026
Early successes on agentic robotics point to a potential paradigm shift toward using coding agents to control robots. Existing robotics benchmarks are built around visuomotor policy learning, leaving it open whether coding agents can reliably control diverse robots under…
10 Nov 2026
System-1 Decision Models directly make structured probabilistic decisions over query-specified options given a state in a single forward pass, without autoregressively generating reasoning trajectories or textual responses.
6 Nov 2026
Lloyd's k-means algorithm is a long-running standard for clustering, with applications in data analysis, retrieval, quantization and data curation. In this paper, we introduce an exponential moving average optimization procedure for k-means with mini-batch updates, powered by…
13 Nov 2026
Neural networks are powerful predictors, yet their opacity limits their usefulness in science, where the goal is explanation rather than mere prediction. In neuroscience, for example, deep encoding models accurately predict brain activity in response to natural stimuli, but…
2 Nov 2026
Despite recent advances in CUAs, their development remains constrained by the limited diversity, controllability, and reliability of interaction data. Moreover, conventional optimization pipelines lack iterative feedback, while existing recursive improvement approaches often…
6 Nov 2026
Looping is a powerful inductive bias for reasoning. By repeatedly iterating a recurrent block, looped models can scale their effective depth and enable multi-step reasoning in latent space.
11 Nov 2026
System One models promise fast, general-purpose decision-making without lengthy token generation. However, understanding their capability spectrum and decision reliability requires more than aggregate performance on current benchmarks.
17 Nov 2026
Interactive video world models enable exploration through text and camera controls, yet direct object interaction requires finer control. Hands provide a natural interface, but translating continuous hand movements into coherent visual responses remains challenging because of…
28 Oct 2026
We introduce Nemotron 3.5 Super and Nemotron 3.5 Lightning, open and efficient Mixture-of-Experts Hybrid Mamba-Transformer models designed for reasoning, long-context understanding, and agentic workloads.
3 Nov 2026
We introduce Axion 1.0, a fully open agent foundation model that combines strong and broad agentic capabilities with a remarkably simple training recipe. Axion 1.0 is trained in only three stages: two lightweight supervised fine-tuning stages followed by reinforcement learning,…
16 Nov 2026
3D Gaussian Splatting enables object-level operations on Gaussian primitives, yet existing segmentation methods are largely trained and evaluated through rendered views.
13 Nov 2026
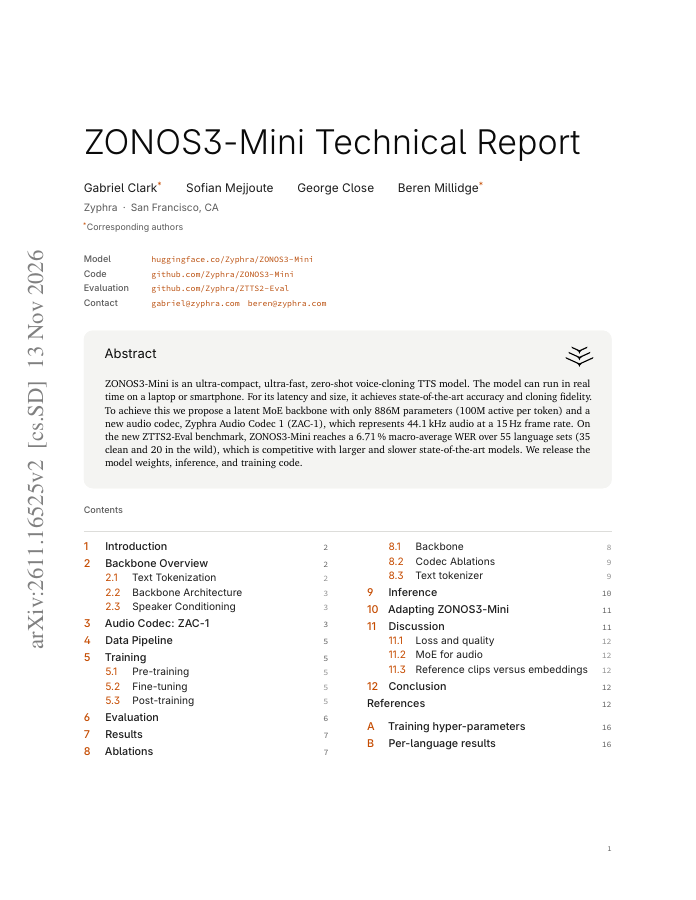
ZONOS3-Mini is an ultra-compact, ultra-fast, zero-shot voice-cloning TTS model. The model can run in real time on a laptop or smartphone. For its latency and size, it achieves state-of-the-art accuracy and cloning fidelity.
27 Oct 2026
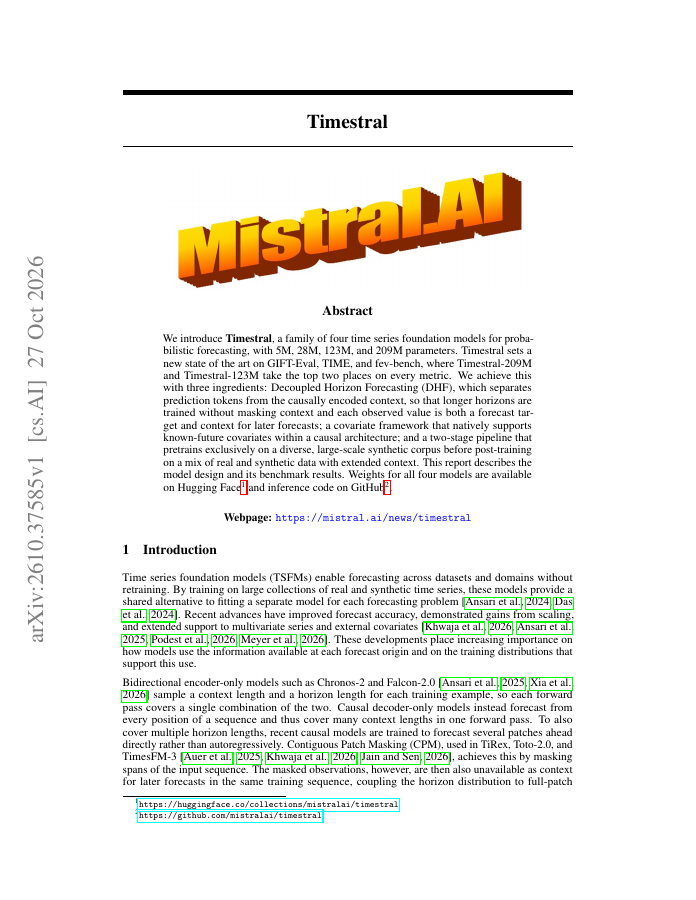
We introduce Timestral, a family of four time series foundation models for probabilistic forecasting, with 5M, 28M, 123M, and 209M parameters. Timestral sets a new state of the art on GIFT-Eval, TIME, and fev-bench, where Timestral-209M and Timestral-123M take the top two places…
7 Nov 2026
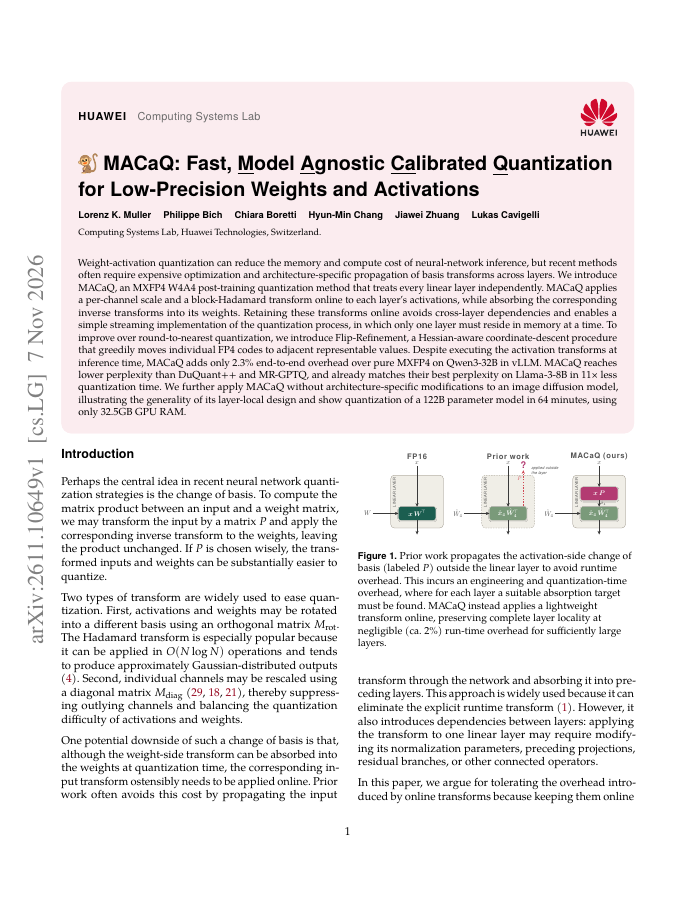
Weight-activation quantization can reduce the memory and compute cost of neural-network inference, but recent methods often require expensive optimization and architecture-specific propagation of basis transforms across layers.
16 Nov 2026
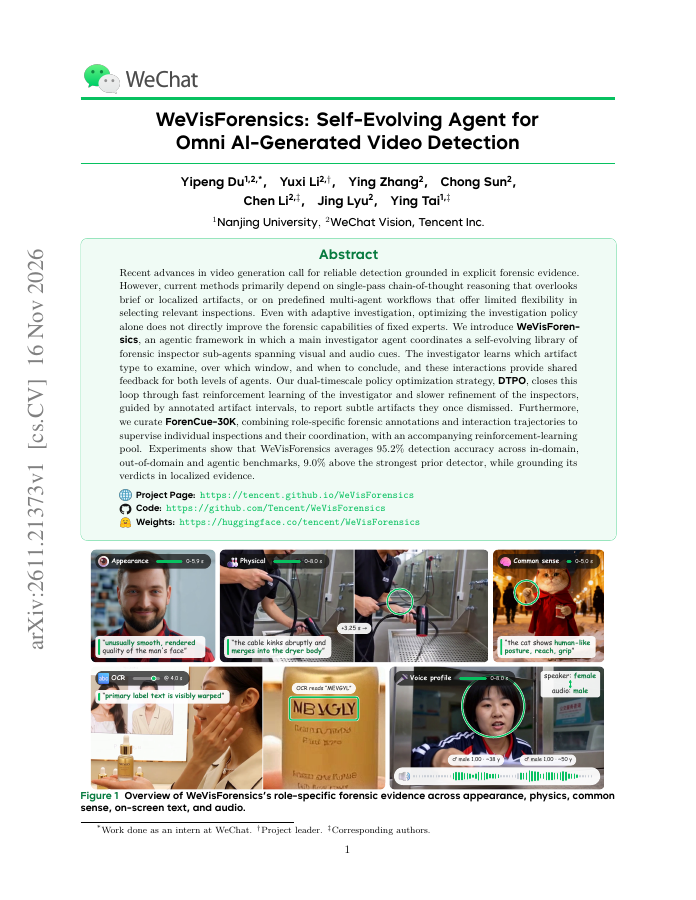
Recent advances in video generation call for reliable detection grounded in explicit forensic evidence. However, current methods primarily depend on single-pass chain-of-thought reasoning that overlooks brief or localized artifacts, or on predefined multi-agent workflows that…
27 Oct 2026
We present EmbeddingGemma 2, an open multimodal embedding model which natively represents text, images, audio, video, and combinations thereof in a unified space. Our approach introduces improvements such as simplified per-layer embeddings and a multi-stage curriculum with…