15 Oct 2026
Reusing the attention KV cache across requests is a standard way to cut prefill cost in long-context LLM serving, and production systems increasingly back the per-engine cache with a remote tier shared by every engine.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,712 papers.
15 Oct 2026
Reusing the attention KV cache across requests is a standard way to cut prefill cost in long-context LLM serving, and production systems increasingly back the per-engine cache with a remote tier shared by every engine.
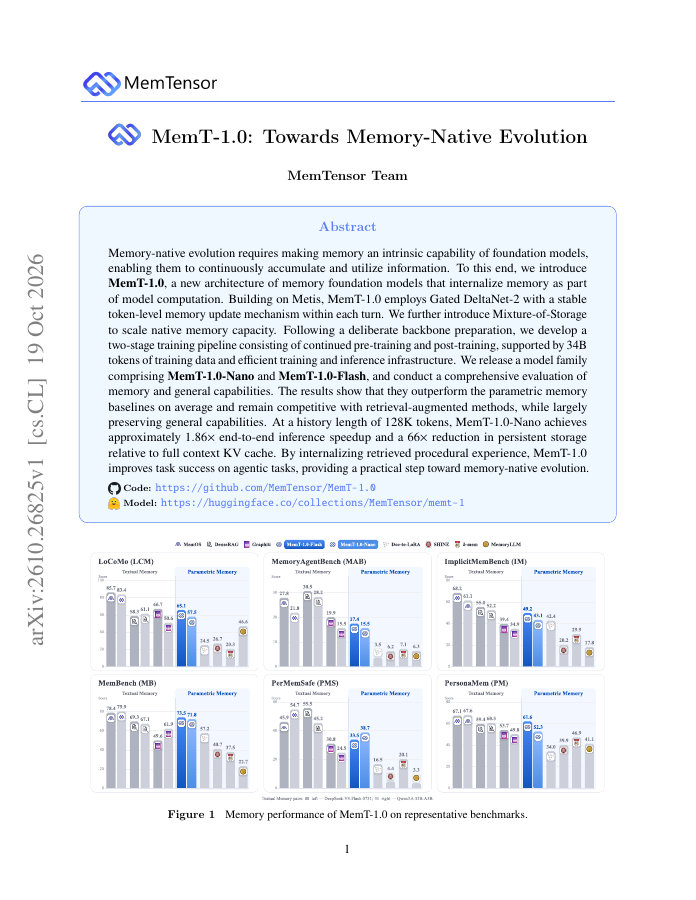
19 Oct 2026
Memory-native evolution requires making memory an intrinsic capability of foundation models, enabling them to continuously accumulate and utilize information. To this end, we introduce MemT-1.0, a new architecture of memory foundation models that internalize memory as part of…
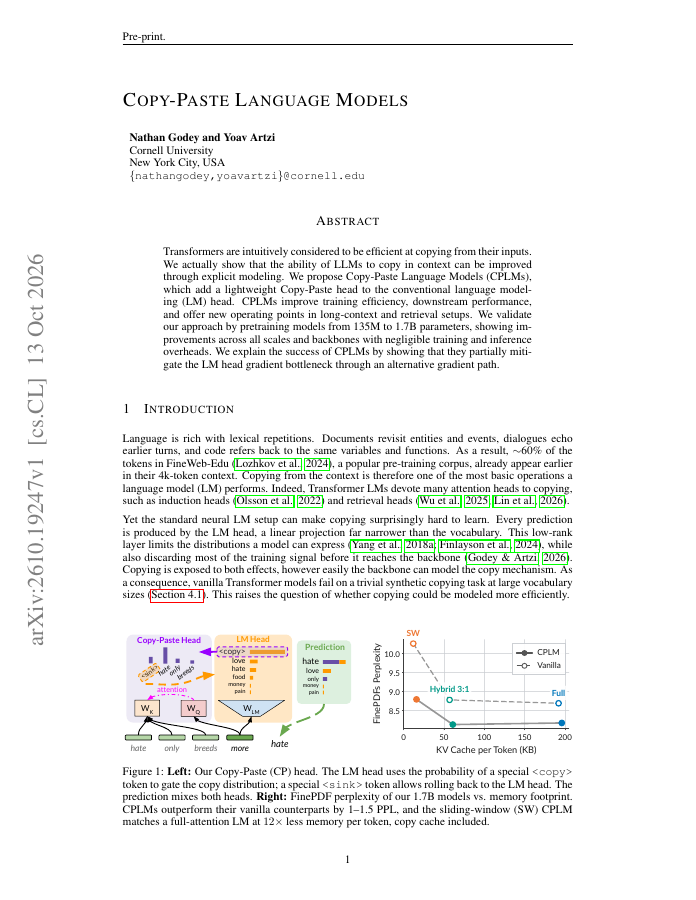
13 Oct 2026
Transformers are intuitively considered to be efficient at copying from their inputs. We actually show that the ability of LLMs to copy in context can be improved through explicit modeling.
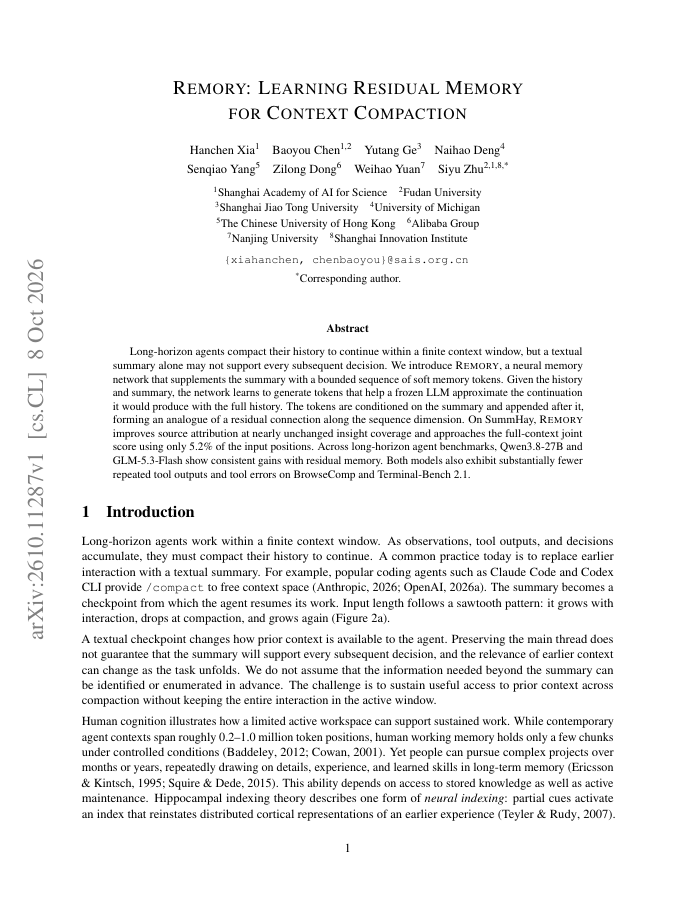
8 Oct 2026
Long-horizon agents compact their history to continue within a finite context window, but a textual summary alone may not support every subsequent decision. We introduce REMORY, a neural memory network that supplements the summary with a bounded sequence of soft memory tokens.
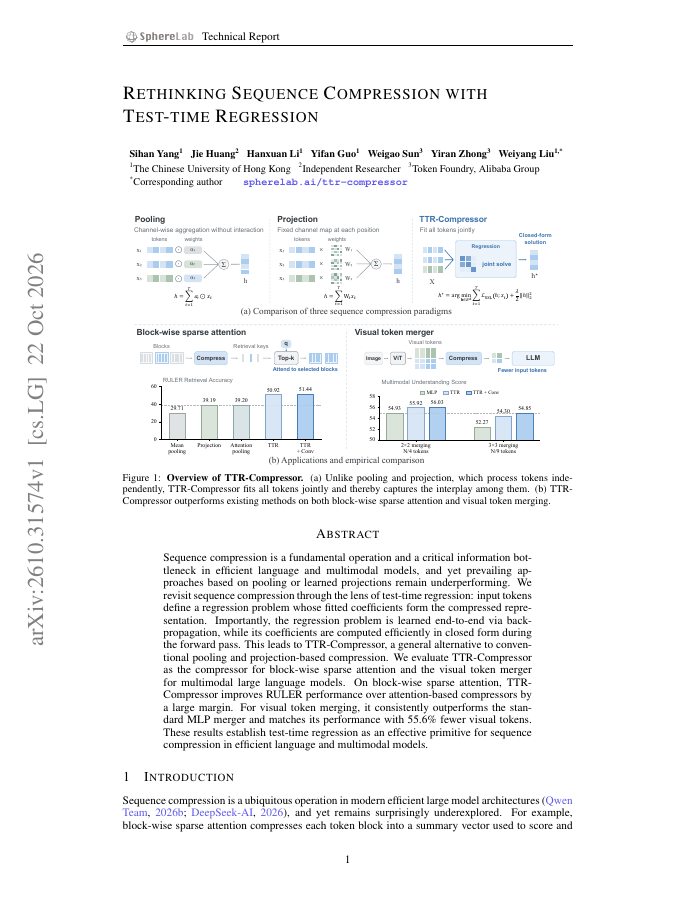
22 Oct 2026
Sequence compression is a fundamental operation and a critical information bottleneck in efficient language and multimodal models, and yet prevailing approaches based on pooling or learned projections remain underperforming.