2 Oct 2026
Large language models (LLMs) have shown promising potential for biomedical named entity recognition (BioNER) through instruction following and in-context learning. However, existing LLM-based BioNER methods still face two key limitations.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,323 papers.
2 Oct 2026
Large language models (LLMs) have shown promising potential for biomedical named entity recognition (BioNER) through instruction following and in-context learning. However, existing LLM-based BioNER methods still face two key limitations.
2 Oct 2026
Post-training with verifiable rewards can induce reward hacking, motivating the use of monitors within the training objective rather than solely for offline auditing. We show that a low monitor readout does not identify whether such an intervention controls behavior.
2 Oct 2026
With the advance of measurement technologies and increasing computing power, large spatial data with heterogeneous structures are often collected over high-dimensional domains.
1 Oct 2026
Large language models (LLMs) have been increasingly used for financial document analysis, including earnings call transcripts (ECTs). Beyond generating standalone claims, users increasingly prefer grounded analyses that pair claims with verifiable citations from source documents…
1 Oct 2026
A comparative explainability framework is presented to audit DeBERTa-v3 under zero-shot classification of medical abstracts. The work addresses the disagreement problem in Explainable Artificial Intelligence, where different attribution methods produce divergent explanations for…
1 Oct 2026
Syntactic ambiguity poses a persistent challenge for Arabic NLP, particularly in morphologically rich nominal constructions where multiple structu6ral interpretations may be compatible with the same surface sequence.
1 Oct 2026
Retrieval-Augmented Generation (RAG) systems for multi-hop Question Answering (QA) must balance retrieval quality with computational cost. This cost is incurred during indexing time, through the use of expensive Knowledge Graphs (KGs) or Large Language Models (LLMs) to generate…
1 Oct 2026
Exam-style accuracy does not establish whether large language models (LLMs) reason well over clinical records. We define clinical reasoning as integrating and updating evidence across time and sources to form, revise and justify a patient's problem representation and a…
1 Oct 2026
Can response safety be scored by cosine similarity to the mean embedding of known-safe responses? A recent sleeper-agent detector proposes exactly this score, yet the raw positive-centroid rule is not identified: positive observations locate the safe class relative to an encoder…
1 Oct 2026
Enterprises adopting retrieval-augmented generation (RAG) face a recurring operational decision: promote, revise, or block a system version. The evidence is incomplete and the metrics come from fallible LLM judges.
30 Sep 2026
An agent that moves must recognise a place from a viewpoint it has never seen. We introduce 4MT-VLM, a dataset of procedurally generated landscapes, each rendered across five stimulus modes that remove appearance cues while holding layout fixed: shape and colour, shape only,…
30 Sep 2026
Despite the widespread use of Low-Rank Adaptation (LoRA), little is known about its dynamics in continual learning and the mechanisms by which low-rank updates affect catastrophic forgetting.
30 Sep 2026
Adapting a language model to a specialized corpus means choosing which instruction-tuning tasks to train on under a fixed budget, and testing one choice costs a fine-tuning run. Common heuristics add more source tasks or pick sources similar to the target.
30 Sep 2026
AI reviewers can assign different judgments to manuscripts that report the same science in different wording, potentially rewarding rhetorical optimization over scientific improvement.
30 Sep 2026
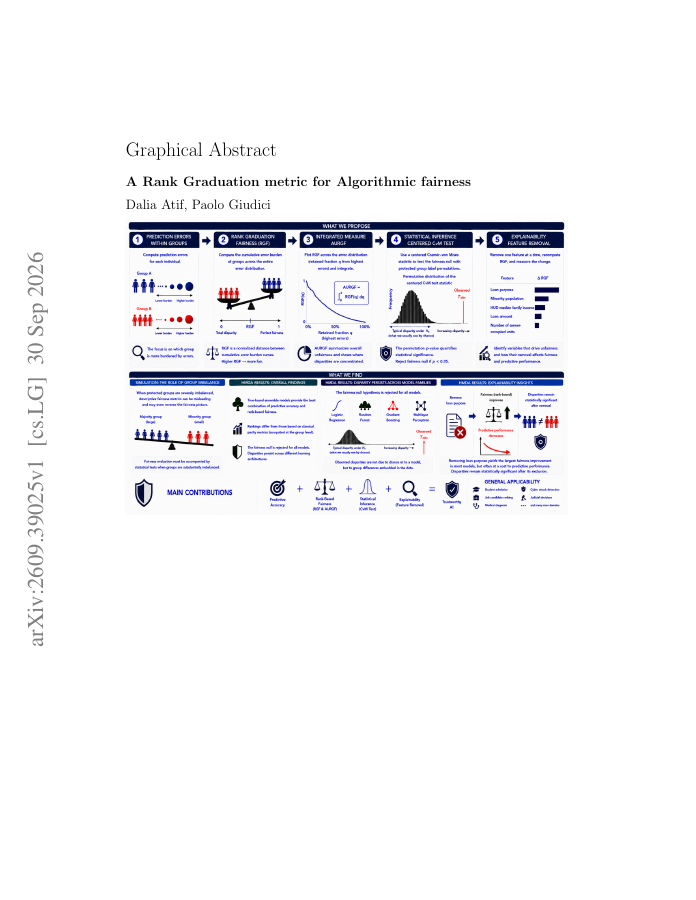
Fairness assessment in algorithmic decisions that affect individuals, such as credit scoring, often relies on parity measures calculated at the aggregate group level. Such measures may not reveal which individuals experience unfairness or which explanatory factors contribute to…
30 Sep 2026
Laurito et al. (PNAS 2025) showed that large language models choosing between two descriptions of the same product, paper or film prefer the description written by a language model over the one written by a person, by a wide margin over what human judges do.
30 Sep 2026
Looped models reason by applying the same block of weights many times, so compressing that block saves memory traffic on every loop. Compressed looped models, however, often collapse, and the collapse is usually blamed on rounding error that accumulates from loop to loop.
30 Sep 2026
Matching problems are ubiquitous in data science as they enable the alignment of structured objects and distributions. While existing solvers are often tailored to specific matching formulations, we unify a broad class of such problems within a common mathematical and…
29 Sep 2026
LLMs trained with Chain-of-thought excel in reasoning capability, but often come with excessive token cost. We find that the core of reasoning capacity lies in the Thinking model's weight component within the null space of a projection defined by the corresponding Non-thinking…
29 Sep 2026
Many datasets carry an intrinsic directionality: citations point backward in time, cells differentiate along lineages, and traffic follows preferred routes. Spectral embedding methods, including most of their extensions to directed graphs, discard this information: they…
29 Sep 2026
We propose a rubric for assessing expressed clinical reasoning in model responses, drawing on three bodies of work: medical education assessment frameworks (ART, SCT, Key Feature Problems and OSCE); clinical LLM benchmarks (MedR-Bench, HealthBench, TIMER-Bench, DR.
29 Sep 2026
A droplet breaks up in tens of microseconds, and a recording captures perhaps a dozen frames. The states in between cannot be recovered without repeating the experiment, and simulating them is too costly to sweep an operating envelope.
29 Sep 2026
Data reconstruction attacks have empirically been successful in recovering training samples from learned models, raising privacy concerns and motivating defenses with guarantees that remain valid against future threats.
29 Sep 2026
Fix a target accuracy $\varepsilon$, a gradient-noise level $s$, and a horizon $N$. We wish to design algorithms which minimize the probability of observing a suboptimality gap which exceeds the target accuracy, i.e., $\mathcal{E}_N = -\log \sup_{f,P} \mathbb{P}_P(f(x_A) -…