5 Oct 2026
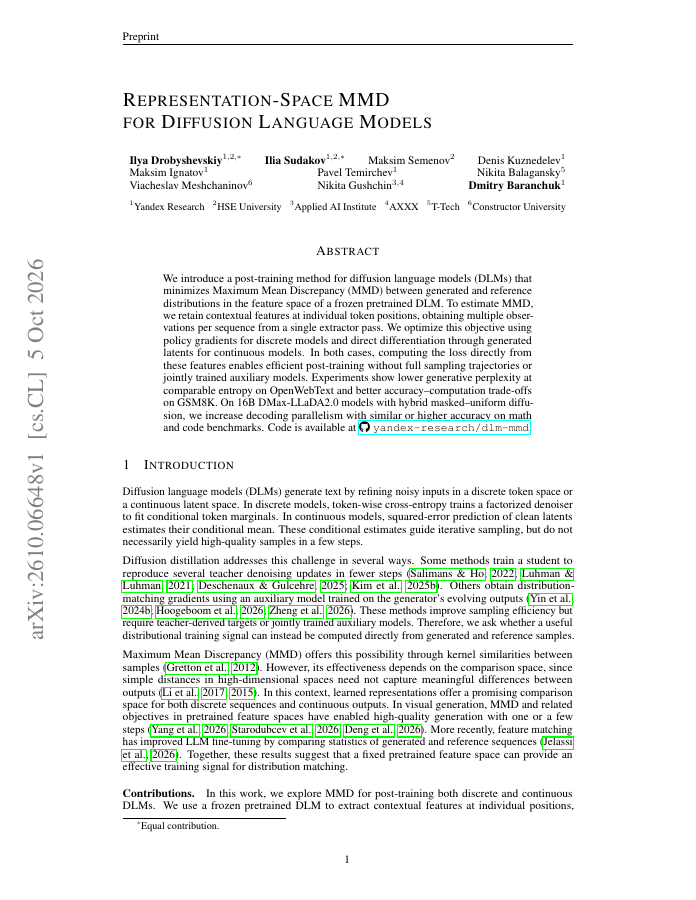
We introduce a post-training method for diffusion language models (DLMs) that minimizes Maximum Mean Discrepancy (MMD) between generated and reference distributions in the feature space of a frozen pretrained DLM.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,347 papers.
5 Oct 2026
We introduce a post-training method for diffusion language models (DLMs) that minimizes Maximum Mean Discrepancy (MMD) between generated and reference distributions in the feature space of a frozen pretrained DLM.
5 Oct 2026
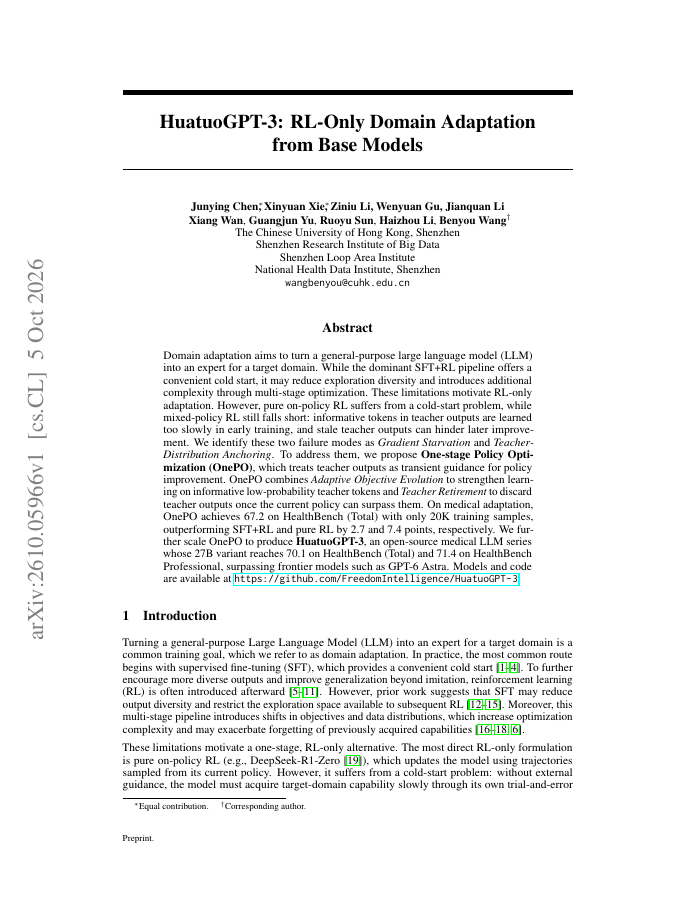
Domain adaptation aims to turn a general-purpose large language model (LLM) into an expert for a target domain. While the dominant SFT+RL pipeline offers a convenient cold start, it may reduce exploration diversity and introduces additional complexity through multi-stage…
5 Oct 2026
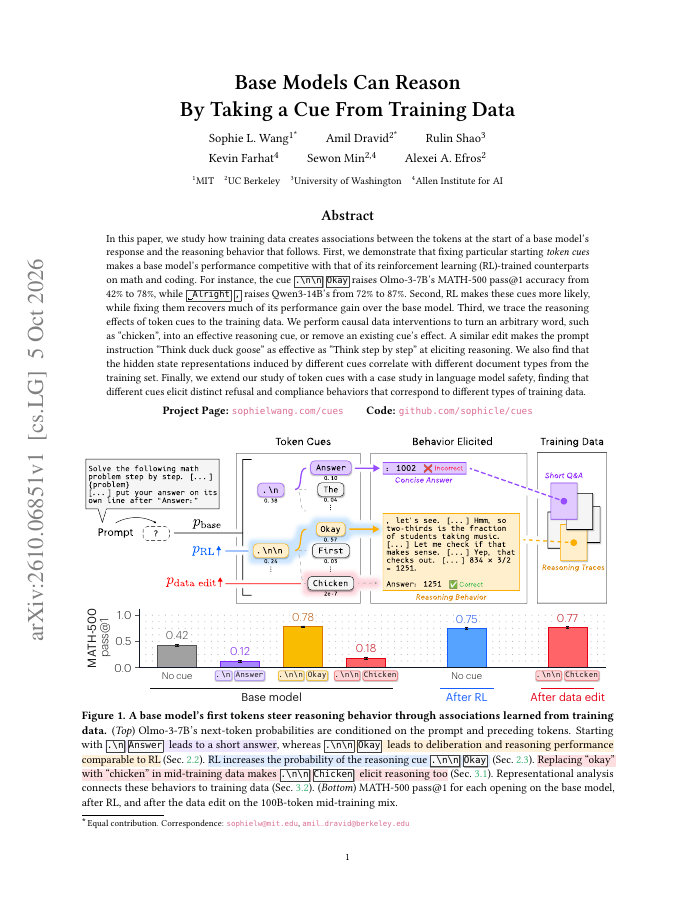
In this paper, we study how training data creates associations between the tokens at the start of a base model's response and the reasoning behavior that follows. First, we demonstrate that fixing particular starting token cues makes a base model's performance competitive with…
5 Oct 2026
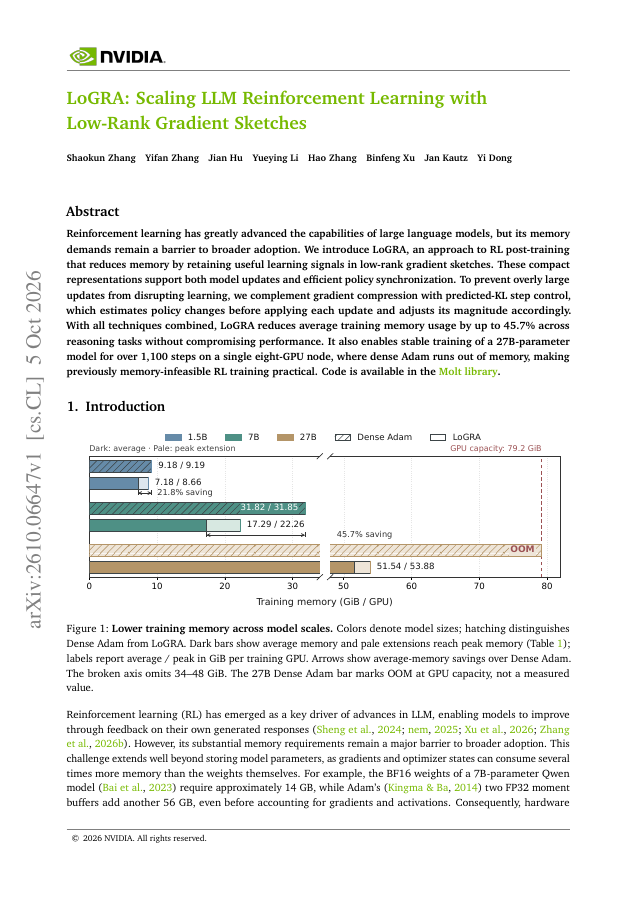
Reinforcement learning (RL) has greatly advanced the capabilities of large language models (LLMs), but its memory demands remain a barrier to broader adoption. We introduce LoGRA, an approach to RL post-training that reduces memory by retaining useful learning signals in…