RealtimeWAM: One-Step Asynchronous World Action Models
5 Oct 2026
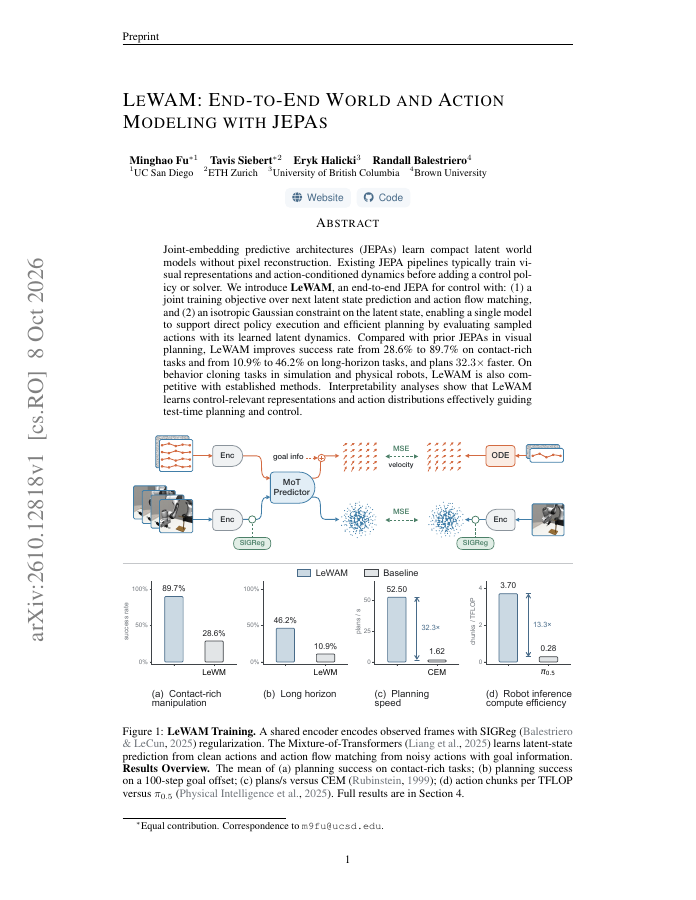
World Action Models (WAMs) incorporate visual representations from video generation backbones to guide action prediction. Recent efficient WAMs adopt Mixture-of-Transformers (MoT) architectures and compute video representations once for reuse by the action expert.