19 Nov 2026
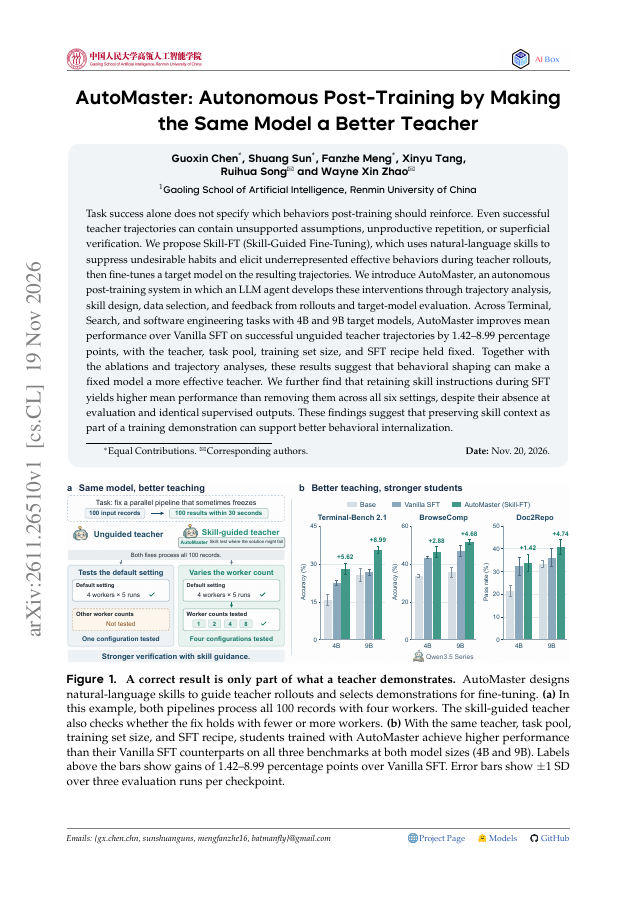
Task success alone does not specify which behaviors post-training should reinforce. Even successful teacher trajectories can contain unsupported assumptions, unproductive repetition, or superficial verification.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 23,060 papers.
19 Nov 2026
Task success alone does not specify which behaviors post-training should reinforce. Even successful teacher trajectories can contain unsupported assumptions, unproductive repetition, or superficial verification.
8 Oct 2026
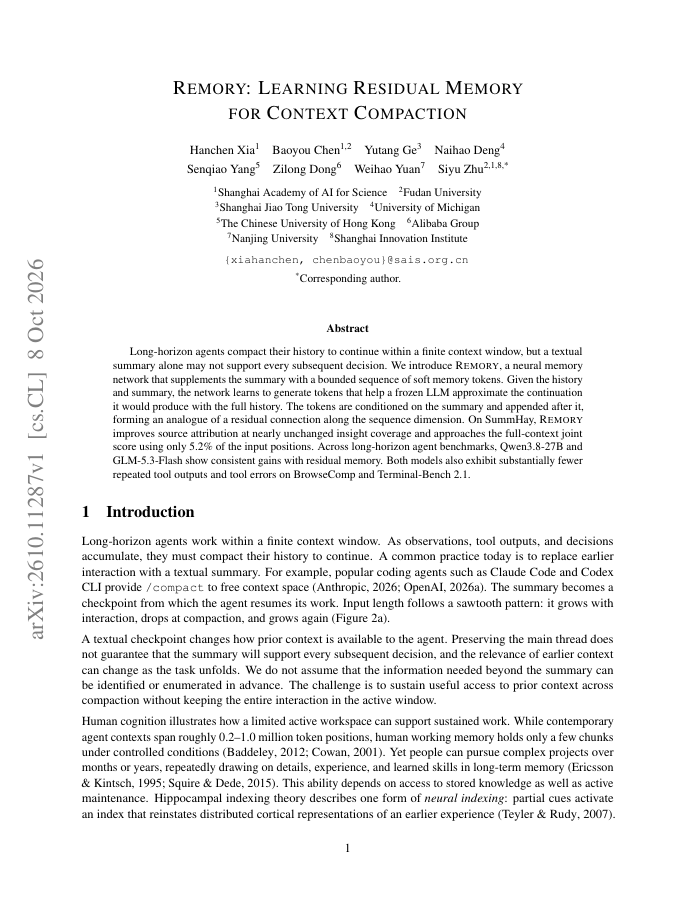
Long-horizon agents compact their history to continue within a finite context window, but a textual summary alone may not support every subsequent decision. We introduce REMORY, a neural memory network that supplements the summary with a bounded sequence of soft memory tokens.
27 Sep 2026
As large language models advance, AI agents are moving beyond isolated, domain-specific tasks toward long-horizon, cross-domain workflows. This transition exposes two challenges: increasing harness complexity makes manual design difficult to scale, while tighter coupling to…
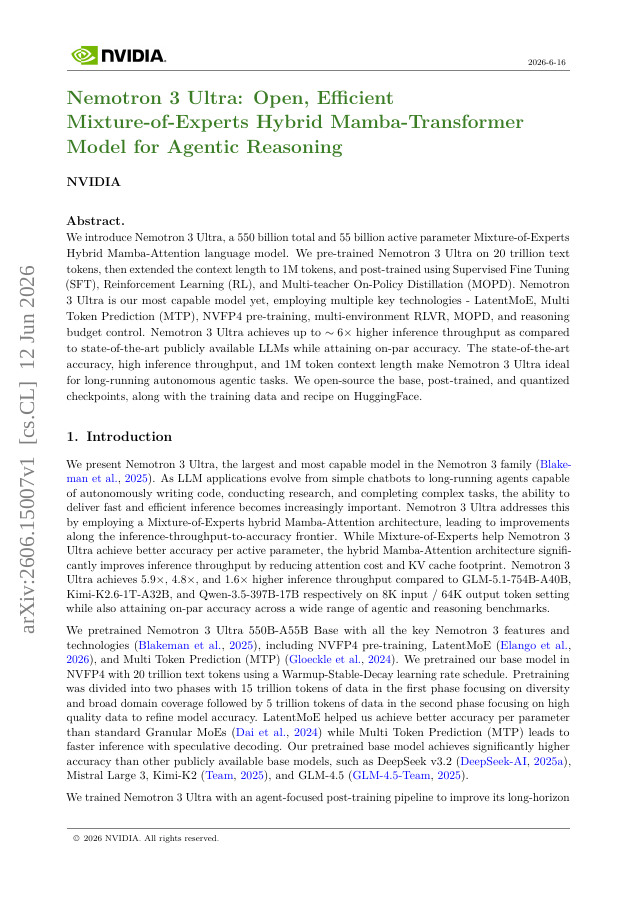
12 Jun 2026
We introduce Nemotron 3 Ultra, a 550 billion total and 55 billion active parameter Mixture-of-Experts Hybrid Mamba-Attention language model. We pre-trained Nemotron 3 Ultra on 20 trillion text tokens, then extended the context length to 1M tokens, and post-trained using…
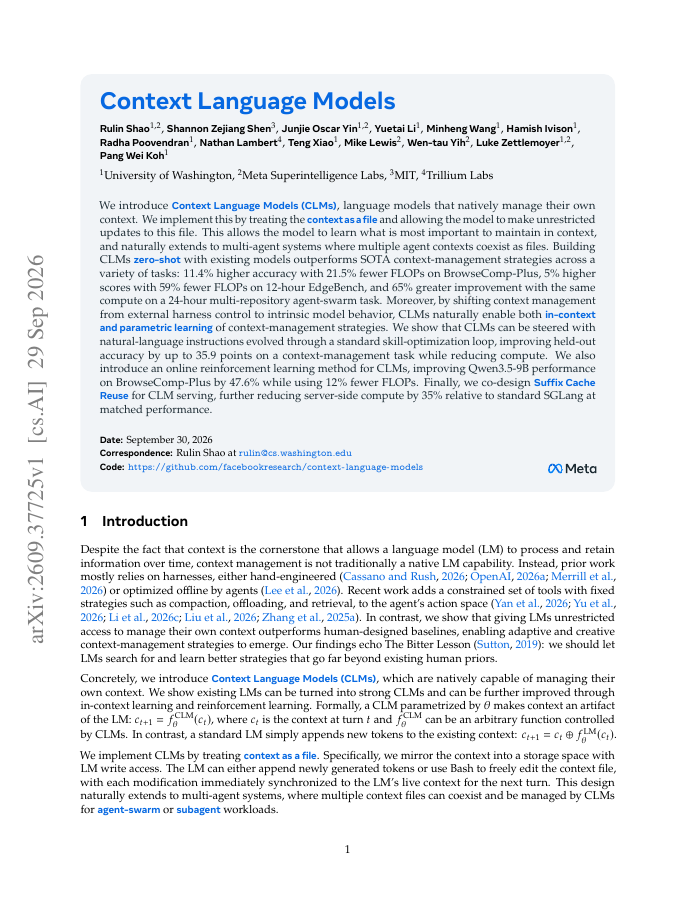
29 Sep 2026
We introduce Context Language Models (CLMs), language models that natively manage their own context. We implement this by treating the context as a file and allowing the model to make unrestricted updates to this file.
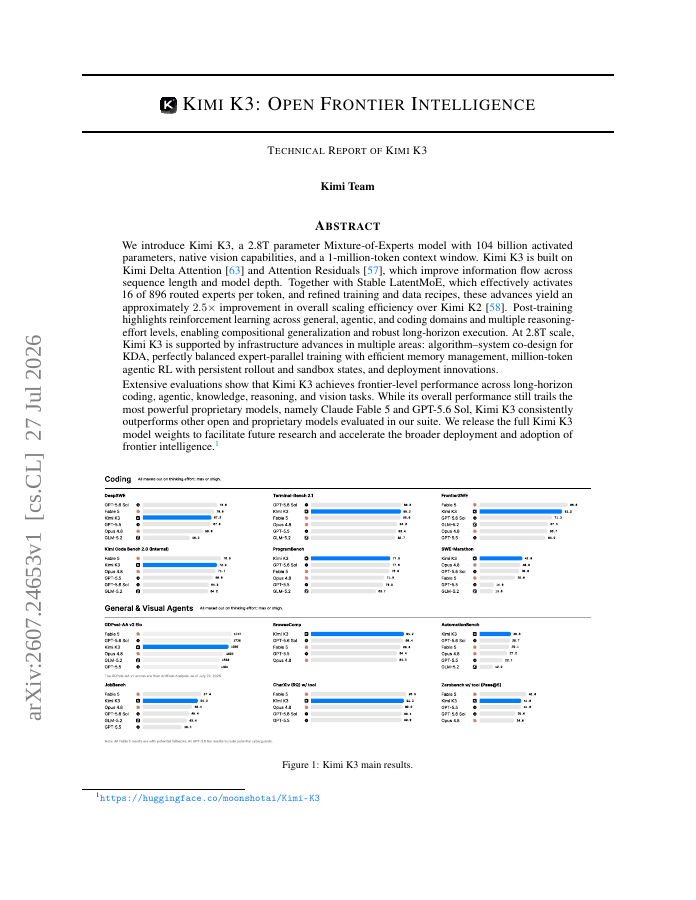
27 Jul 2026
We introduce Kimi K3, a 2.8T parameter Mixture-of-Experts model with 104 billion activated parameters, native vision capabilities, and a 1-million-token context window. Kimi K3 is built on Kimi Delta Attention and Attention Residuals, which improve information flow across…
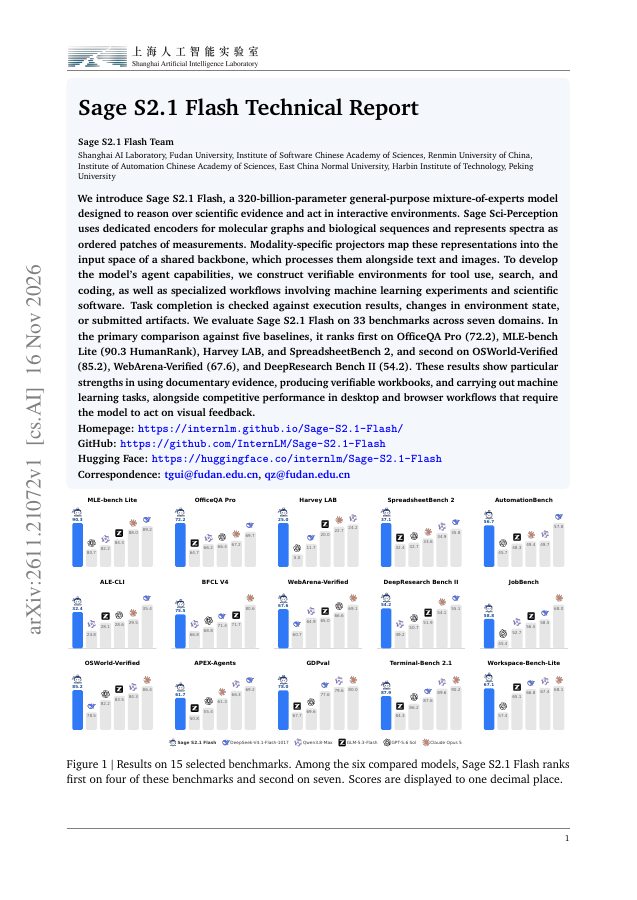
16 Nov 2026
We introduce Sage S2.1 Flash, a 320-billion-parameter general-purpose mixture-of-experts model designed to reason over scientific evidence and act in interactive environments.
28 Oct 2026
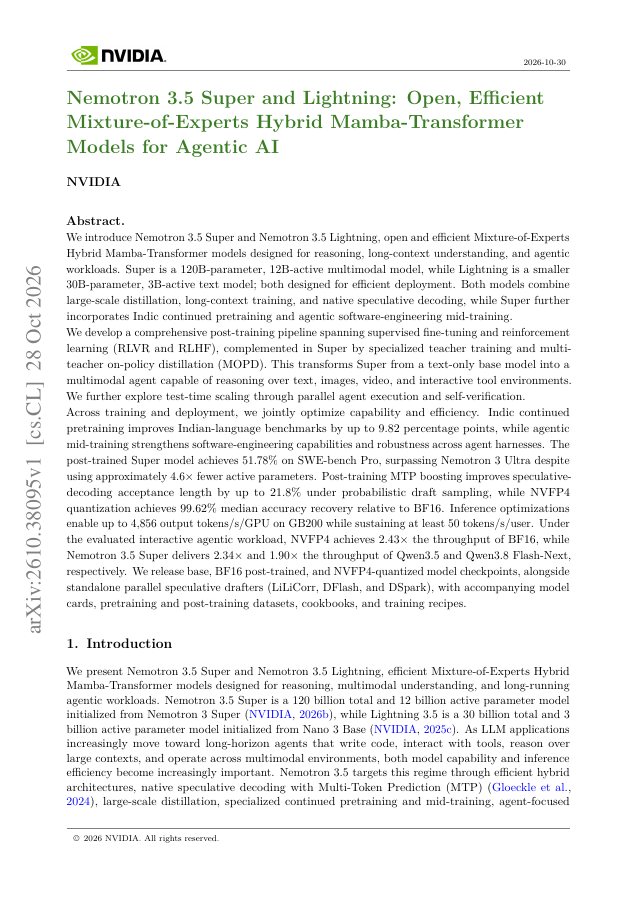
We introduce Nemotron 3.5 Super and Nemotron 3.5 Lightning, open and efficient Mixture-of-Experts Hybrid Mamba-Transformer models designed for reasoning, long-context understanding, and agentic workloads.
16 Nov 2026
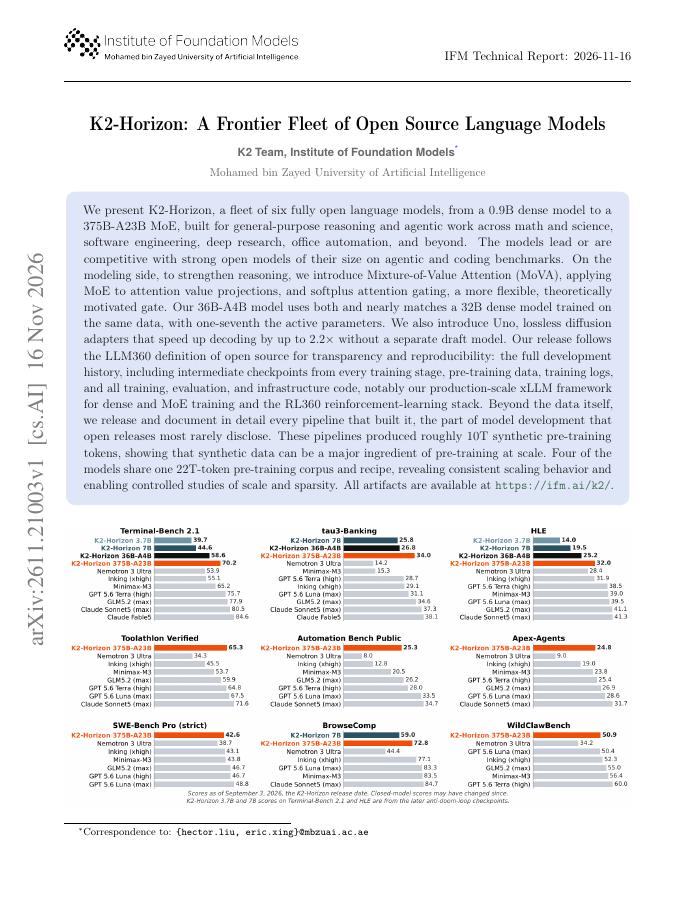
We present K2-Horizon, a fleet of six fully open language models, from a 0.9B dense model to a 375B-A23B MoE, built for general-purpose reasoning and agentic work across math and science, software engineering, deep research, office automation, and beyond.