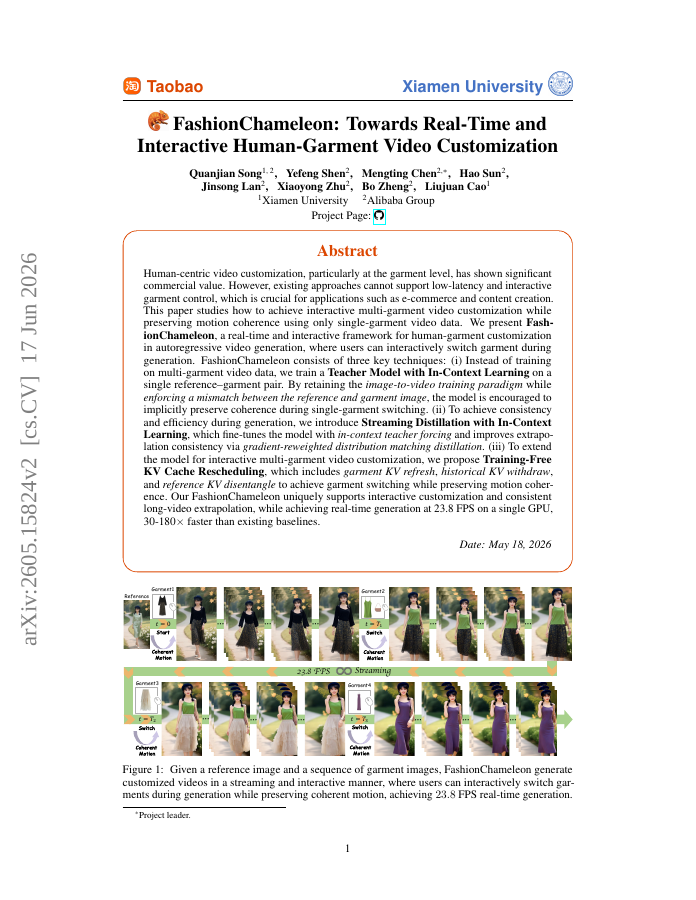
Bo Zheng, Quanjian Song, Yefeng Shen et al. · 15 May 2026
Human-centric video customization, particularly at the garment level, has shown significant commercial value.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,347 papers.
Bo Zheng, Quanjian Song, Yefeng Shen et al. · 15 May 2026
Human-centric video customization, particularly at the garment level, has shown significant commercial value.
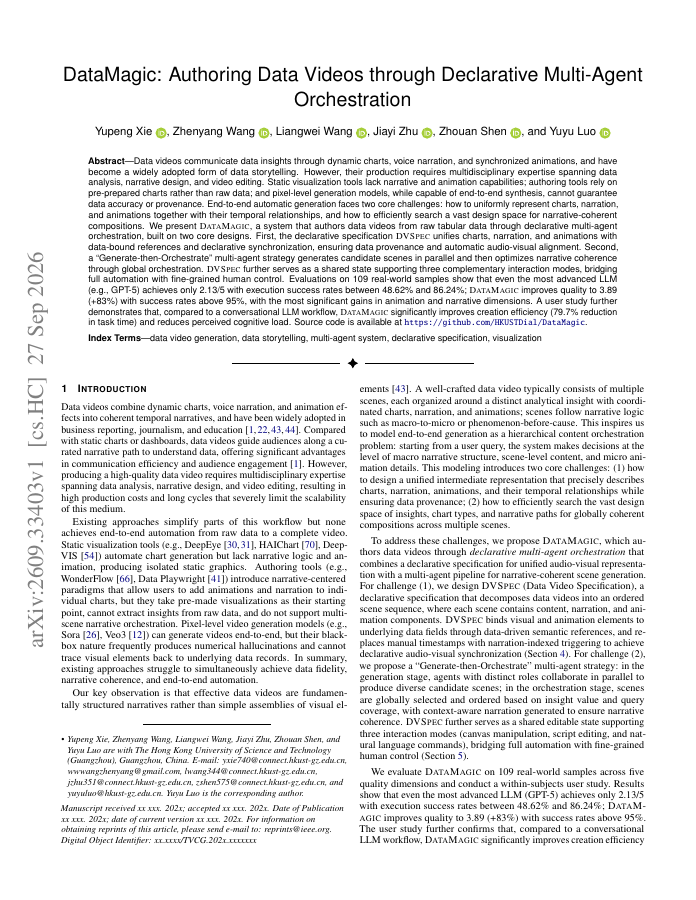
27 Sep 2026
Data videos communicate data insights through dynamic charts, voice narration, and synchronized animations, and have become a widely adopted form of data storytelling. However, producing them requires expertise in data analysis, narrative design, and video editing.
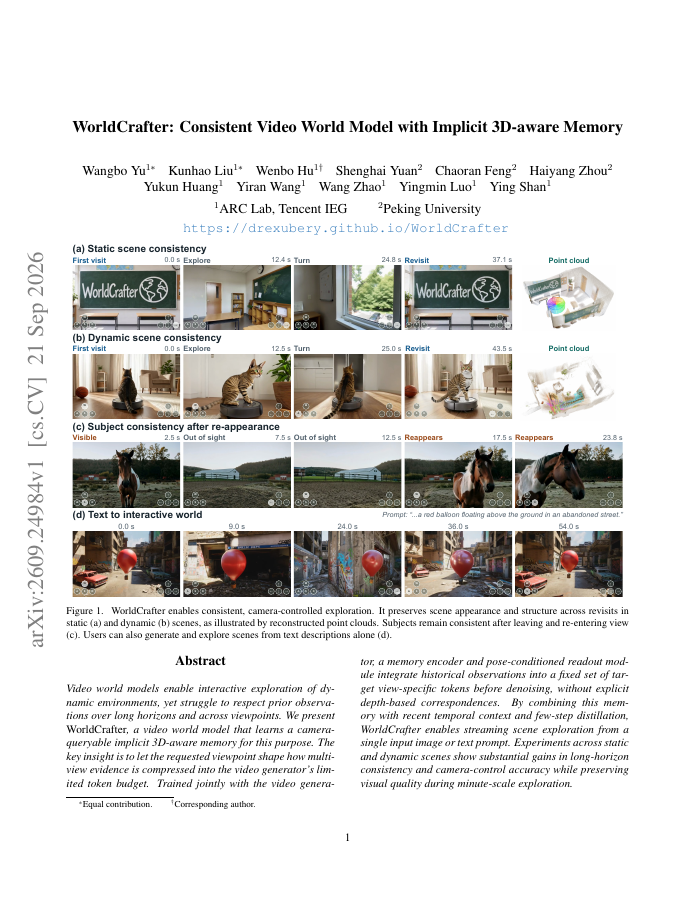
21 Sep 2026
Video world models enable interactive exploration of dynamic environments, yet struggle to respect prior observations over long horizons and across viewpoints. We present WorldCrafter, a video world model that learns a camera-queryable implicit 3D-aware memory for this purpose.
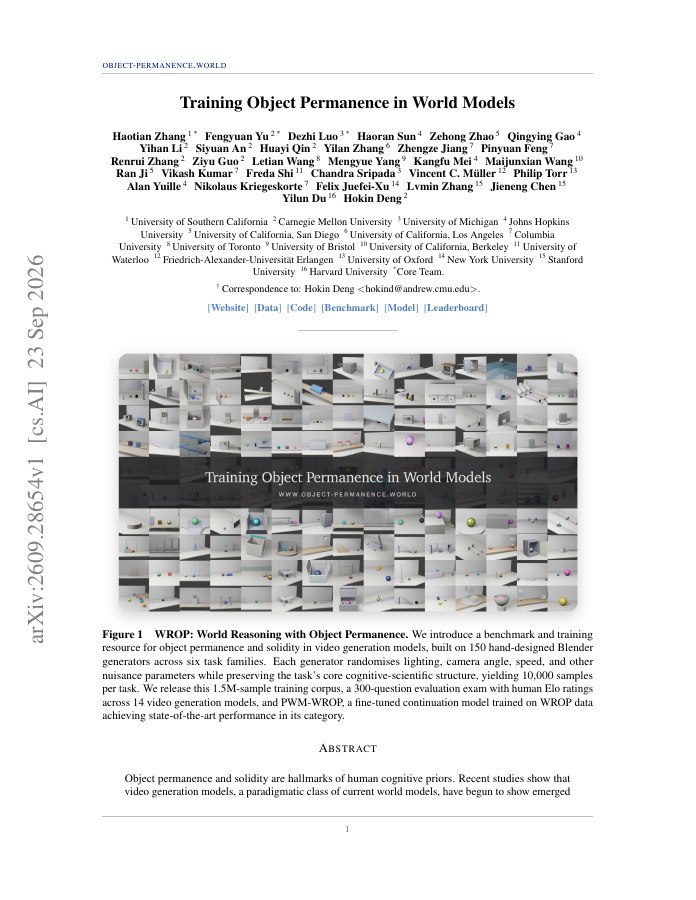
23 Sep 2026
Object permanence and solidity are hallmarks of human cognitive priors. Recent studies show that video generation models, a paradigmatic class of current world models, have begun to show emerged reasoning abilities, making them ideal candidates for building human-like physical…
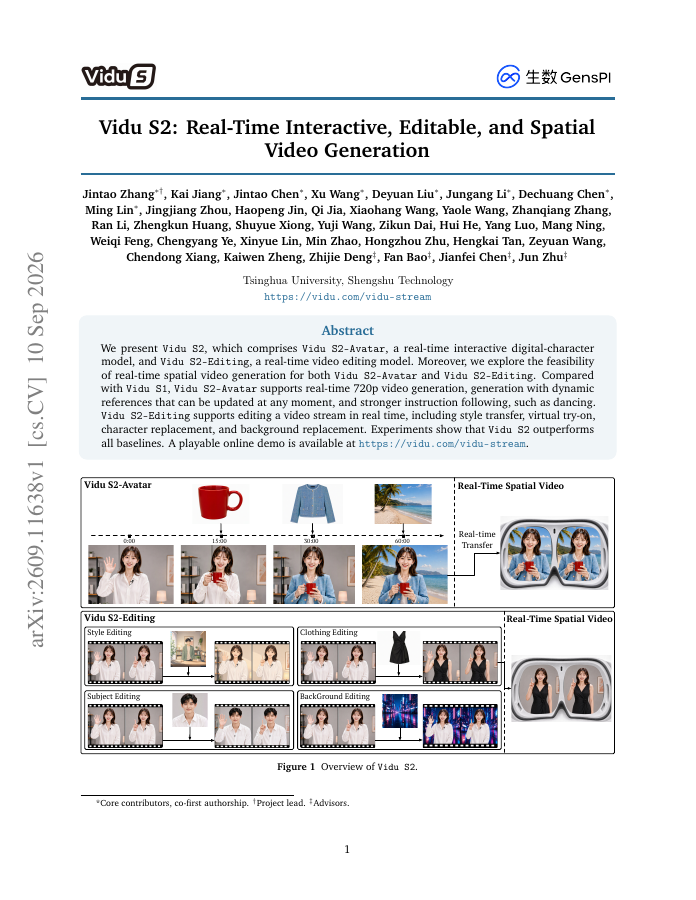
10 Sep 2026
We present Vidu S2, which comprises Vidu S2-Avatar, a real-time interactive digital-character model, and Vidu S2-Editing, a real-time video editing model. Moreover, we explore the feasibility of real-time spatial video generation for both Vidu S2-Avatar and Vidu S2-Editing.
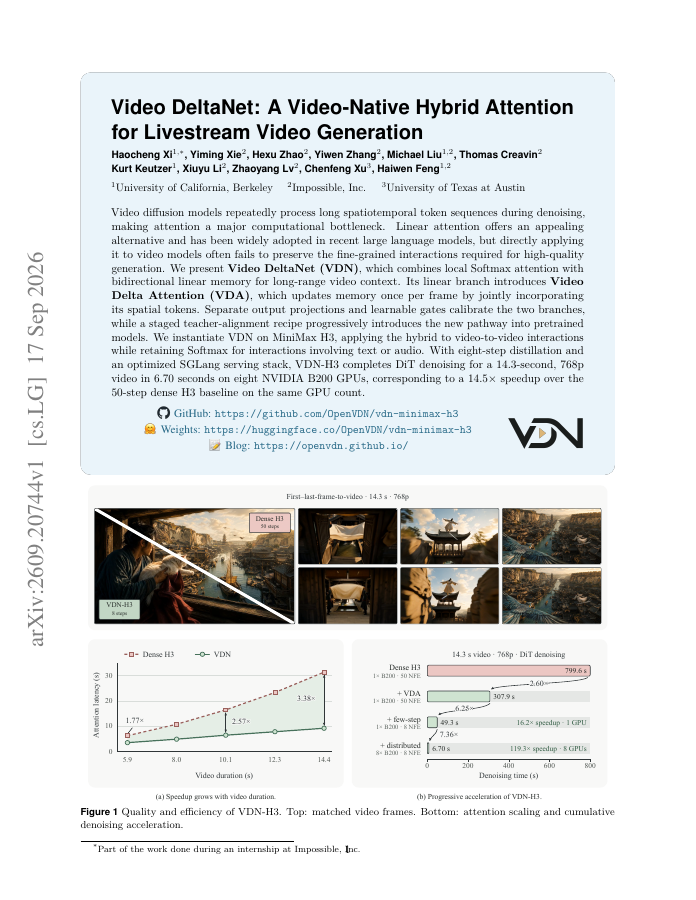
17 Sep 2026
Video diffusion models repeatedly process long spatiotemporal token sequences during denoising, making attention a major computational bottleneck. Linear attention offers an appealing alternative and has been widely adopted in recent large language models, but directly applying…
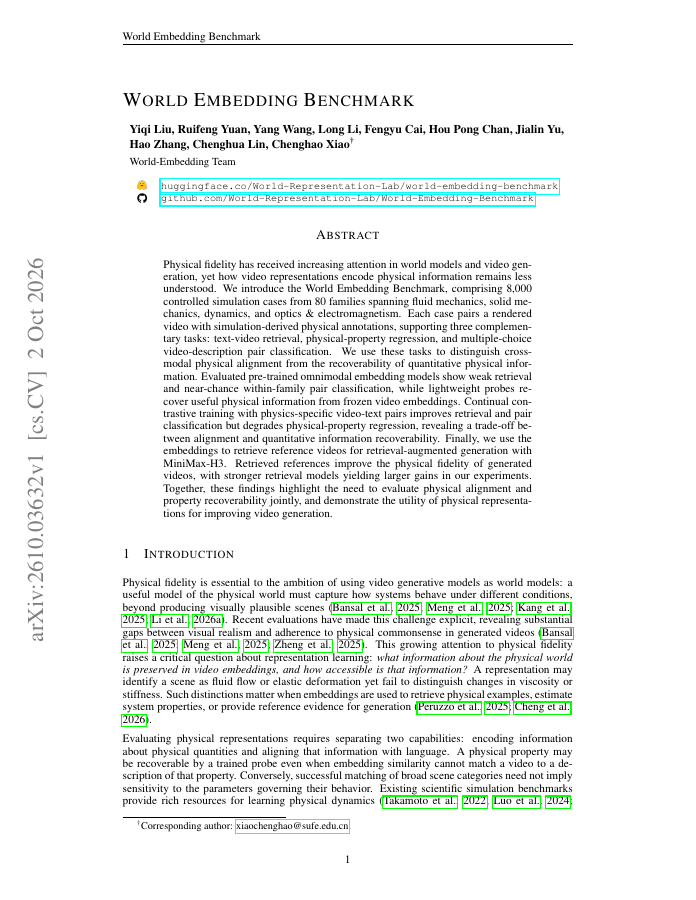
2 Oct 2026
Physical fidelity has received increasing attention in world models and video generation, yet how video representations encode physical information remains less understood.
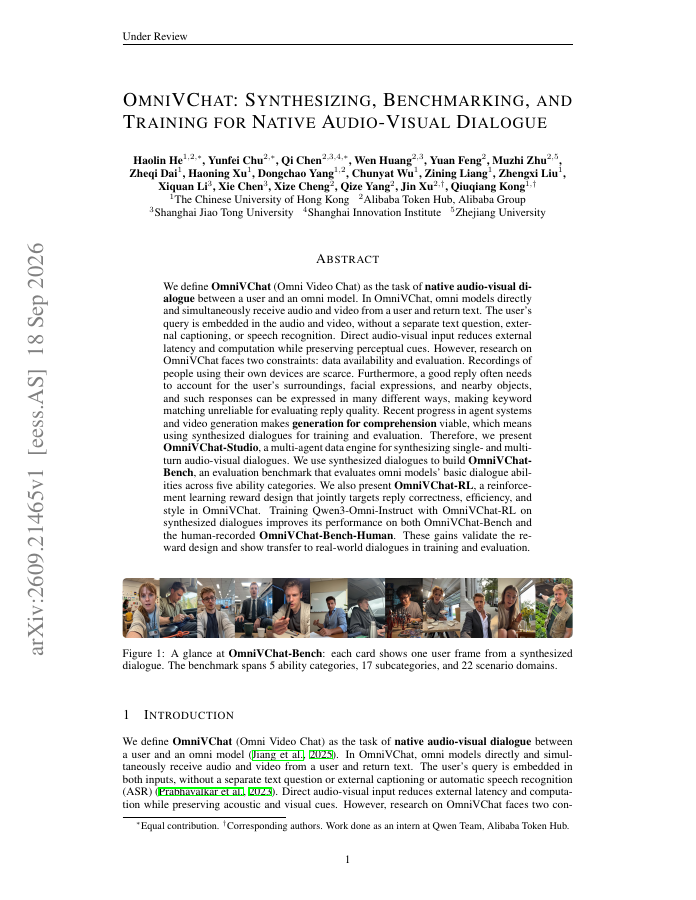
18 Sep 2026
We define OmniVChat (Omni Video Chat) as the task of native audio-visual dialogue between a user and an omni model. In OmniVChat, omni models directly and simultaneously receive audio and video from a user and return text.