9 Oct 2026
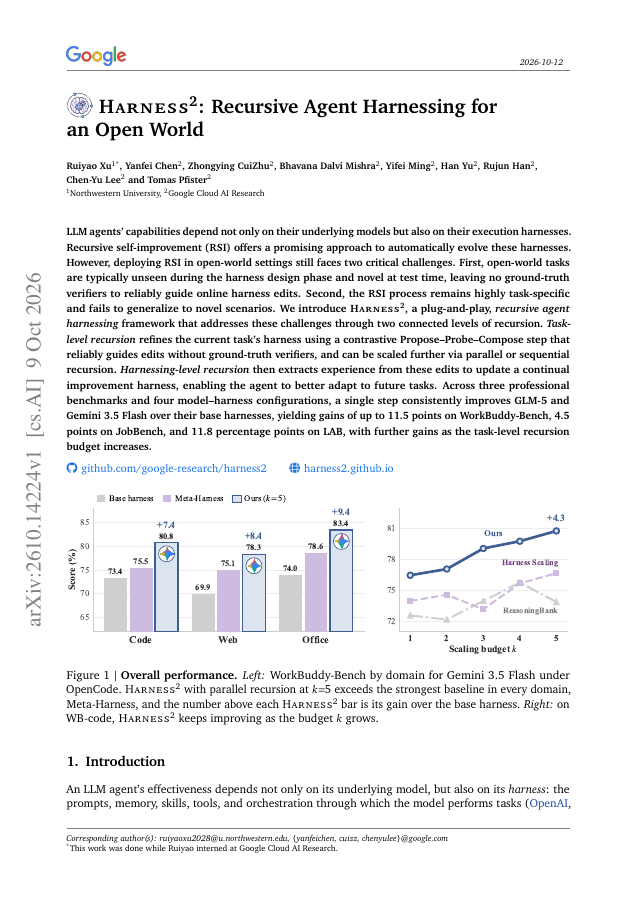
LLM agents' capabilities depend not only on their underlying models but also on their execution harnesses. Recursive self-improvement (RSI) offers a promising approach to automatically evolve these harnesses.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,667 papers.
9 Oct 2026
LLM agents' capabilities depend not only on their underlying models but also on their execution harnesses. Recursive self-improvement (RSI) offers a promising approach to automatically evolve these harnesses.
22 Jun 2026
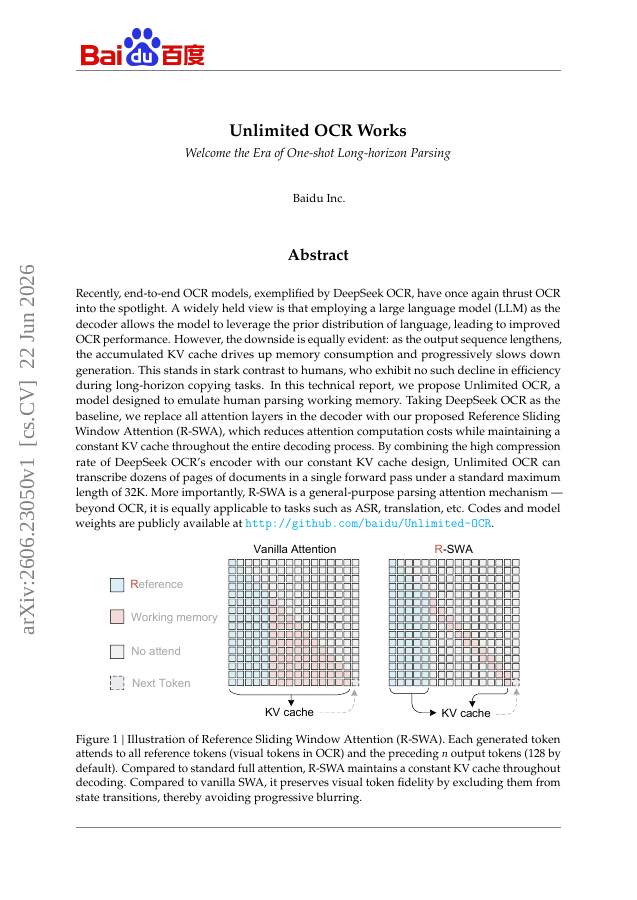
Recently, end-to-end OCR models, exemplified by DeepSeek OCR, have once again thrust OCR into the spotlight. A widely held view is that employing a large language model (LLM) as the decoder allows the model to leverage the prior distribution of language, leading to improved OCR…
9 Oct 2026
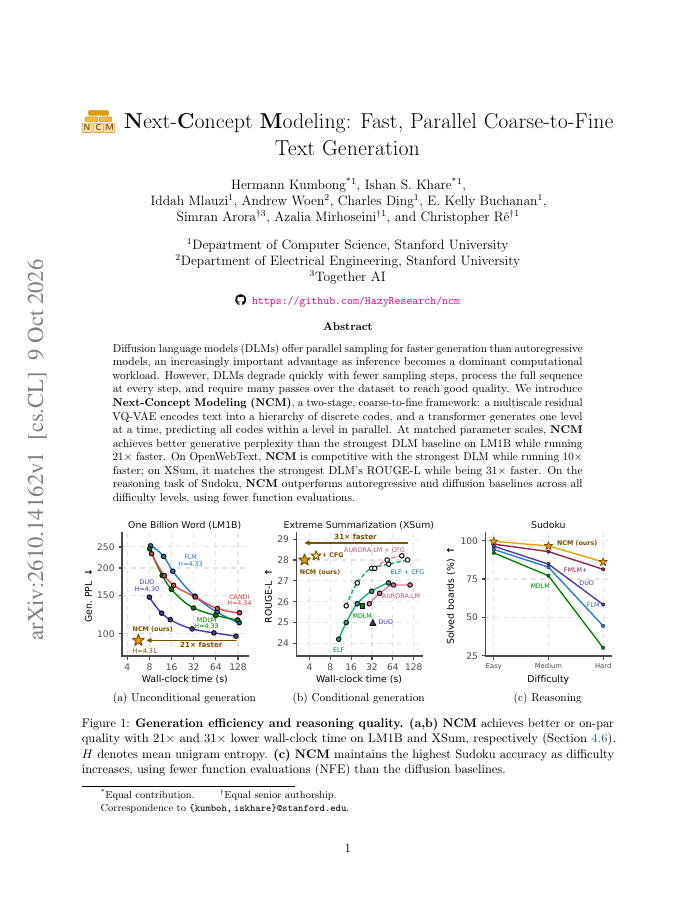
Diffusion language models (DLMs) offer parallel sampling for faster generation than autoregressive models, an increasingly important advantage as inference becomes a dominant computational workload.
8 Oct 2026
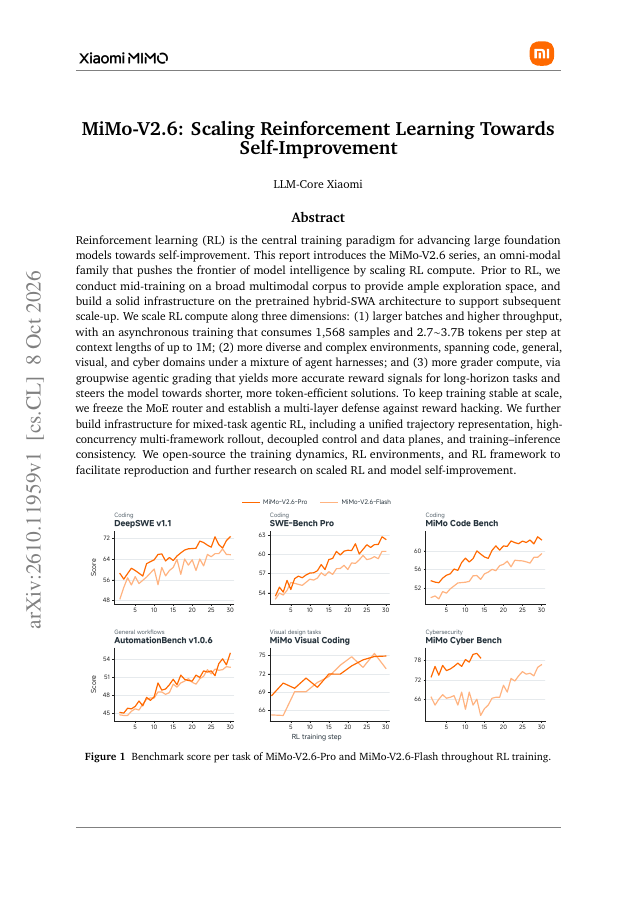
Reinforcement learning (RL) is the central training paradigm for advancing large foundation models towards self-improvement. This report introduces the MiMo-V2.6 series, an omni-modal family that pushes the frontier of model intelligence by scaling RL compute.
16 Sep 2026
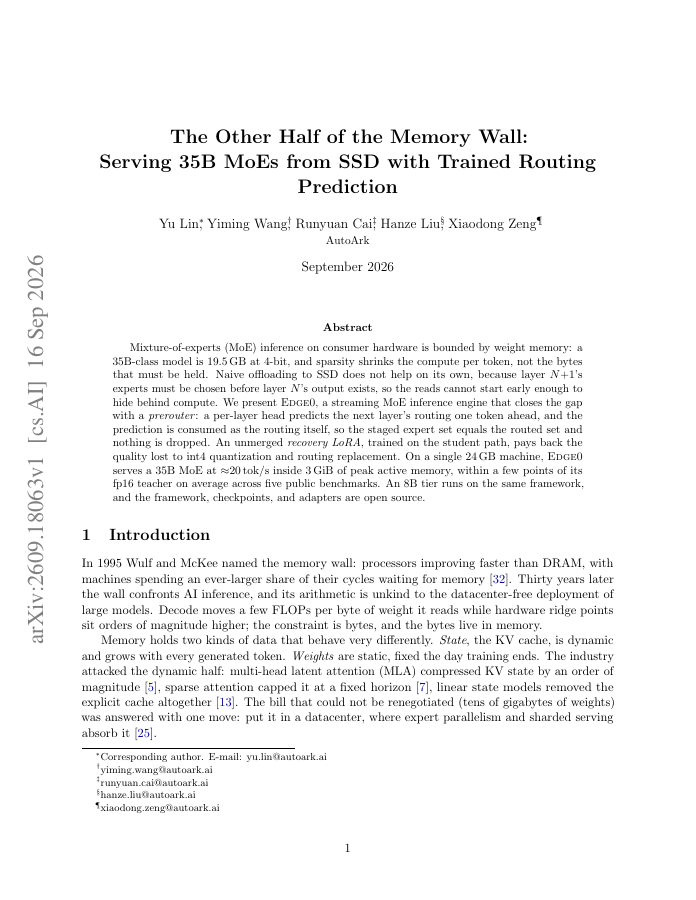
Mixture-of-experts (MoE) inference on consumer hardware is bounded by weight memory: a 35B-class model is 19.5GB at 4-bit, and sparsity shrinks the compute per token, not the bytes that must be held.
20 Oct 2026
Large Language Model (LLM) agents can handle increasingly complex tasks, navigating long trajectories of observations and actions. As these trajectories grow, key-value (KV) cache I/O and storage become the dominant cost.
29 May 2026
LLM agents are increasingly expected not only to complete isolated tasks, but also to carry bounded representations of human expertise, judgment, and interaction style. Building such person-grounded agents remains difficult because actionable knowledge associated with a person…
17 Sep 2026
The widespread adoption of long-horizon agents has made model workloads increasingly input-heavy. Although prior work has substantially reduced the cost of long-context computation, prefill remains computationally expensive, and large KV caches continue to strain HBM and SSD…
21 Jul 2026
Efficient teamwork typically combines global coordination with parallel execution, a principle not yet fully reflected in unified Vision-Language Model (VLM)-based document parsers.
Yifan Yang, Ziyang Gong, Weiquan Huang et al. · 22 May 2026
Agent skills today are hand-crafted, generated one-shot, or evolved through loosely controlled self-revision, none of which behaves like a deep-learning optimizer for the skill, and none of which reliably improves over its starting point under feedback.
8 Oct 2026
Long-horizon agents compact their history to continue within a finite context window, but a textual summary alone may not support every subsequent decision. We introduce REMORY, a neural memory network that supplements the summary with a bounded sequence of soft memory tokens.
21 Oct 2026
AI-generated text detectors are increasingly deployed in consequential settings---peer review, education, admissions, journalism, and content moderation---where their outputs directly affect individuals.
2 Jun 2026
Real-time vision demands models that are accurate, efficient, and simple to deploy across diverse hardware. The YOLO family has become widely deployed for this reason, yet most YOLO detectors still rely on non-maximum suppression at inference, carry heavy detection heads due to…
20 Oct 2026
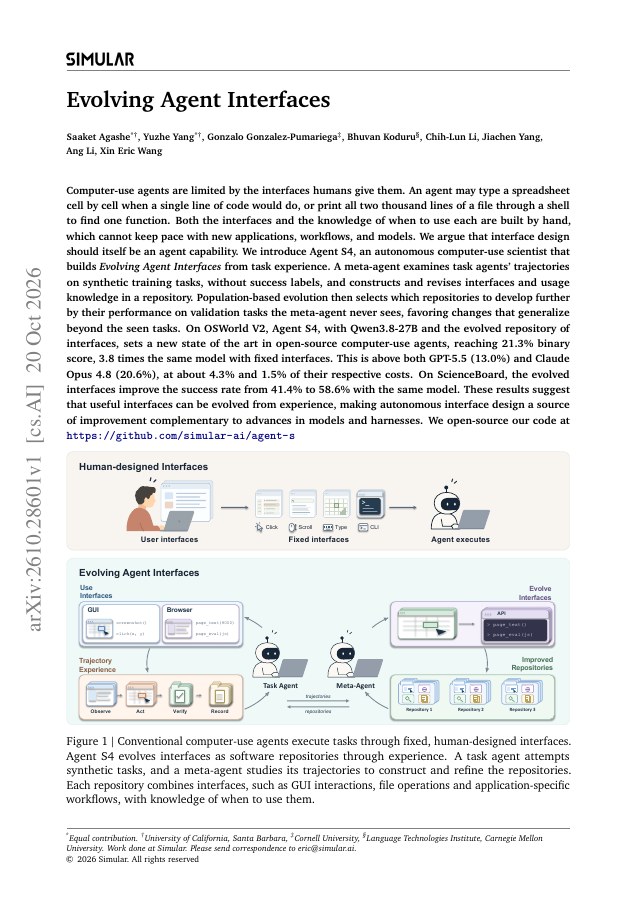
Computer-use agents are limited by the interfaces humans give them. An agent may type a spreadsheet cell by cell when a single line of code would do, or print all two thousand lines of a file through a shell to find one function.
27 Sep 2026
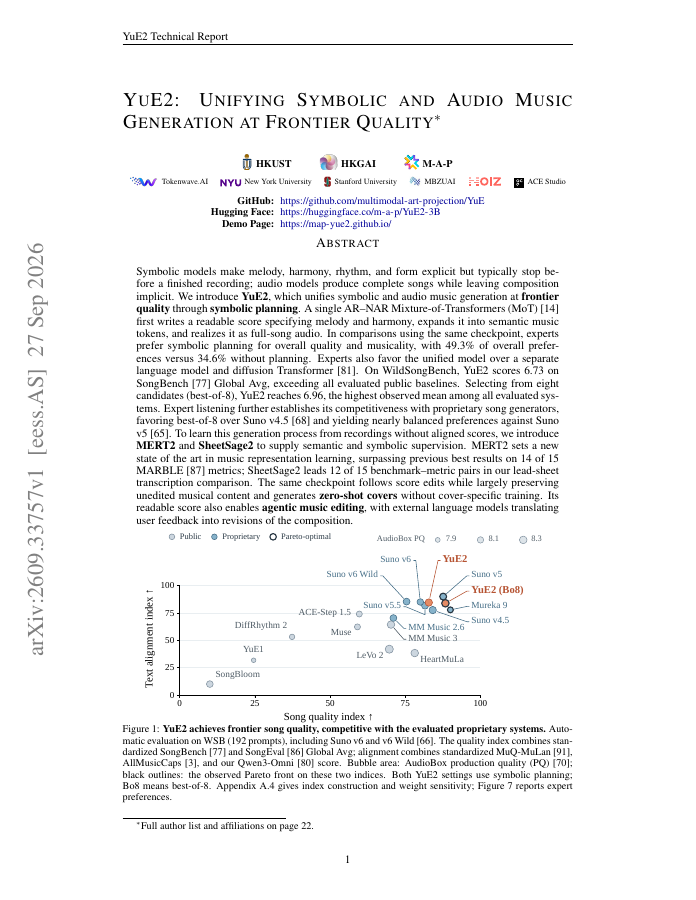
Symbolic models make melody, harmony, rhythm, and form explicit but typically stop before a finished recording; audio models produce complete songs while leaving composition implicit.
15 Jun 2026
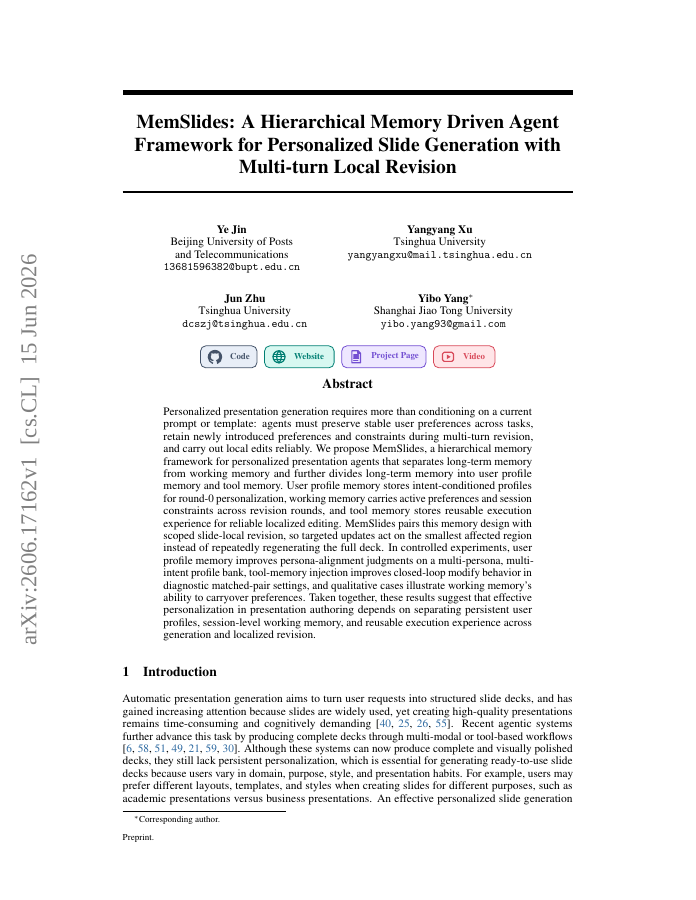
Personalized presentation generation requires more than conditioning on a current prompt or template: agents must preserve stable user preferences across tasks, retain newly introduced preferences and constraints during multi-turn revision, and carry out local edits reliably.
19 Oct 2026
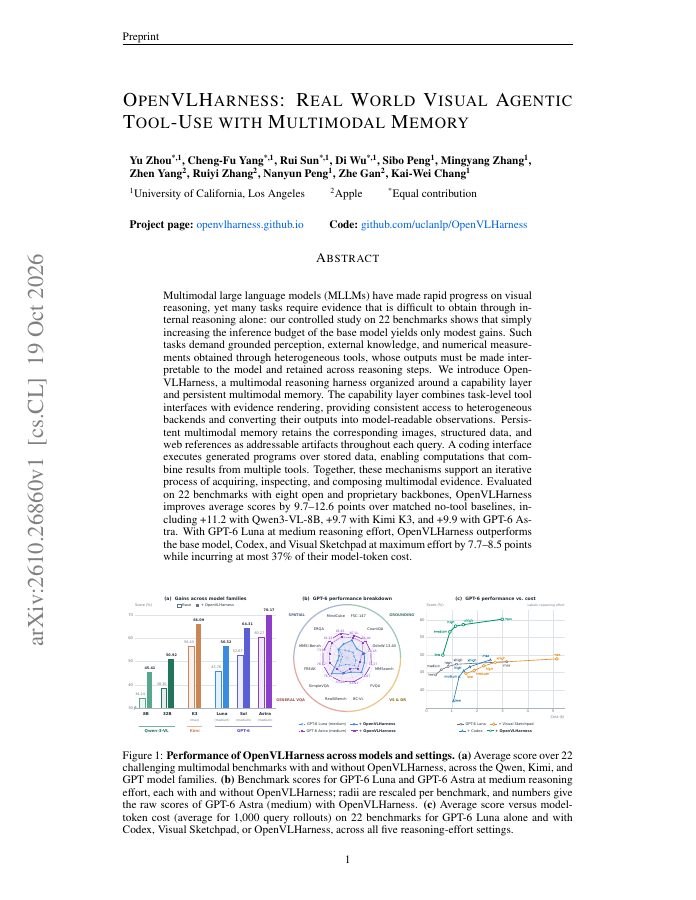
Multimodal large language models (MLLMs) have made rapid progress on visual reasoning, yet many tasks require evidence that is difficult to obtain through internal reasoning alone: our controlled study on 22 benchmarks shows that simply increasing the inference budget of the…
13 Oct 2026
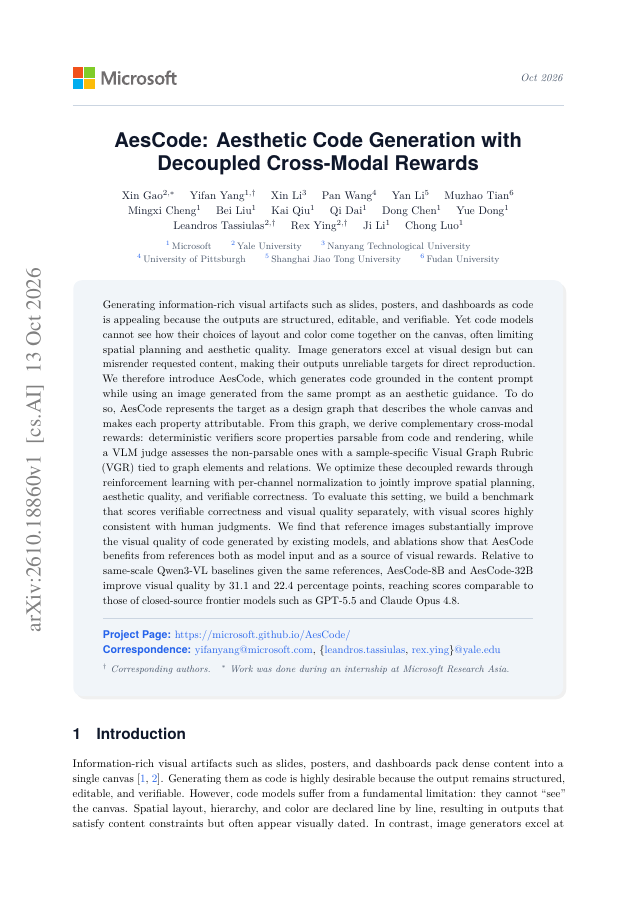
Generating information-rich visual artifacts such as slides, posters, and dashboards as code is appealing because the outputs are structured, editable, and verifiable. Yet code models cannot see how their choices of layout and color come together on the canvas, often limiting…
1 Jun 2026
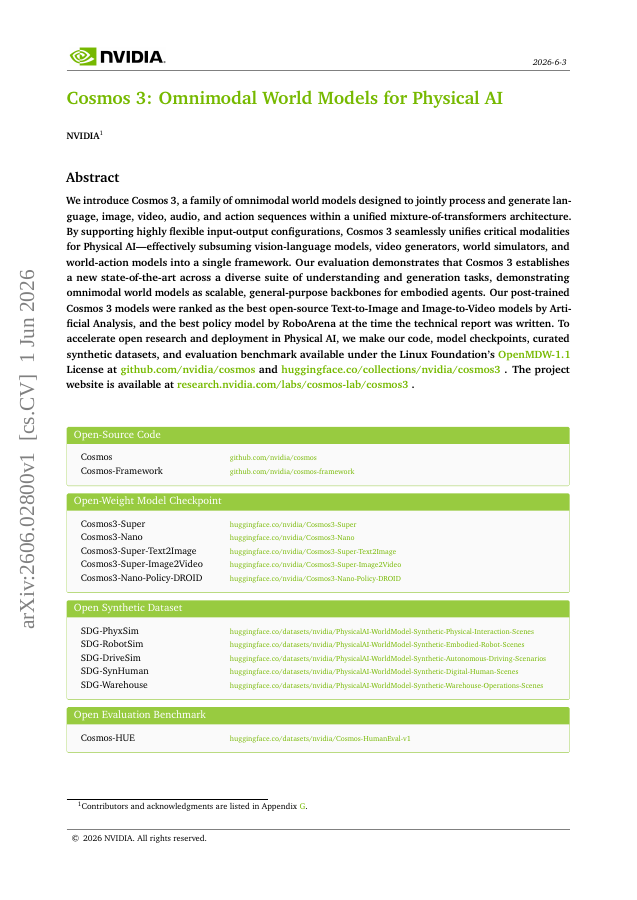
We introduce Cosmos 3, a family of omnimodal world models designed to jointly process and generate language, image, video, audio, and action sequences within a unified mixture-of-transformers architecture.
15 Oct 2026
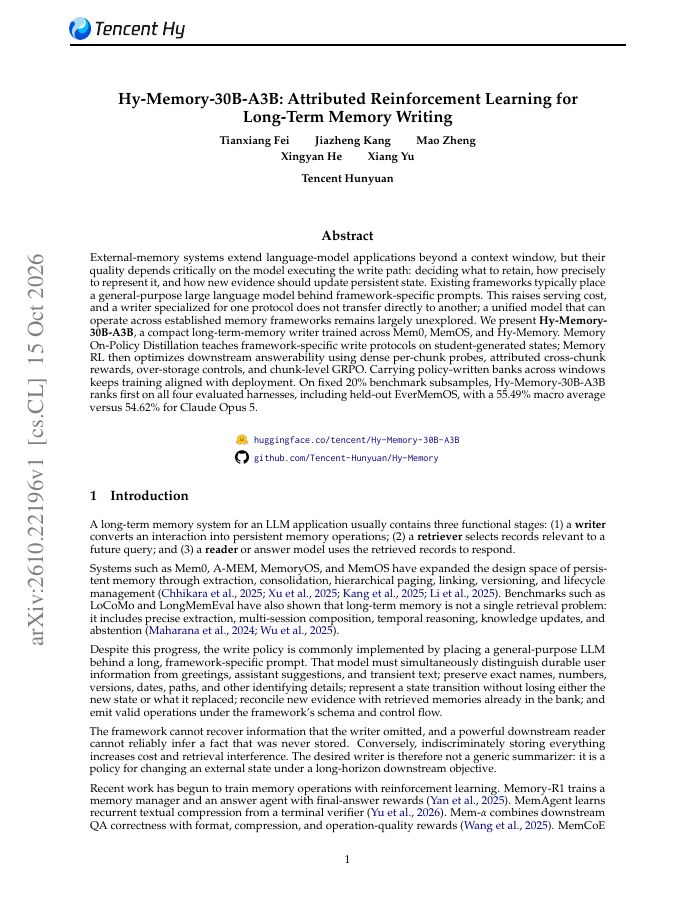
External-memory systems extend language-model applications beyond a context window, but their quality depends critically on the model executing the write path: deciding what to retain, how precisely to represent it, and how new evidence should update persistent state.
4 Sep 2026
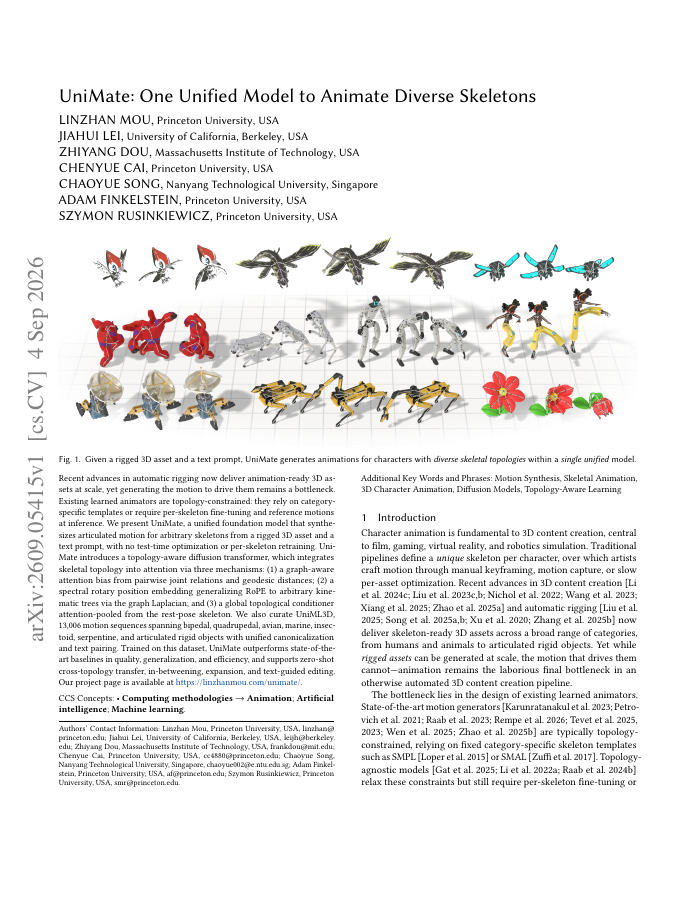
Recent advances in automatic rigging now deliver animation-ready 3D assets at scale, yet generating the motion to drive them remains a bottleneck. Existing learned animators are topology-constrained: they rely on category-specific templates or require per-skeleton fine-tuning…
19 Oct 2026
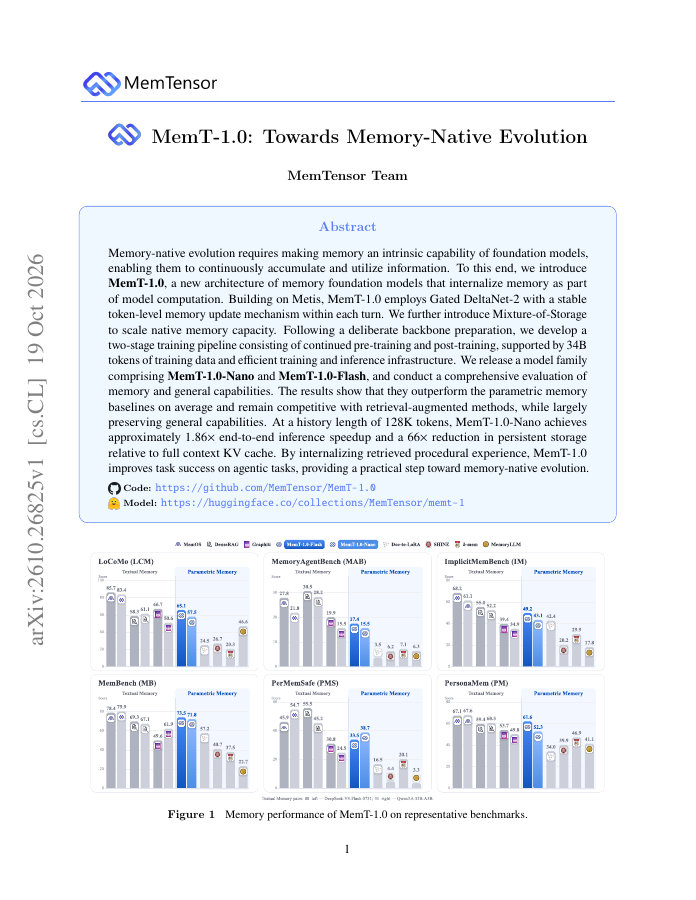
Memory-native evolution requires making memory an intrinsic capability of foundation models, enabling them to continuously accumulate and utilize information. To this end, we introduce MemT-1.0, a new architecture of memory foundation models that internalize memory as part of…
6 Oct 2026
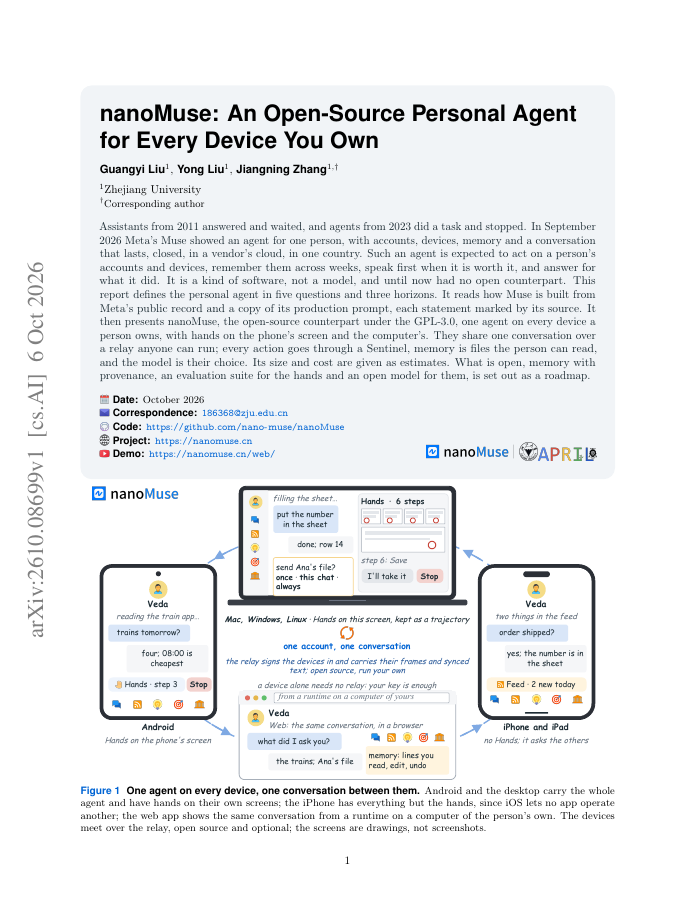
Assistants from 2011 answered and waited, and agents from 2023 did a task and stopped. In September 2026 Meta's Muse showed an agent for one person, with accounts, devices, memory and a conversation that lasts, closed, in a vendor's cloud, in one country.
12 Oct 2026
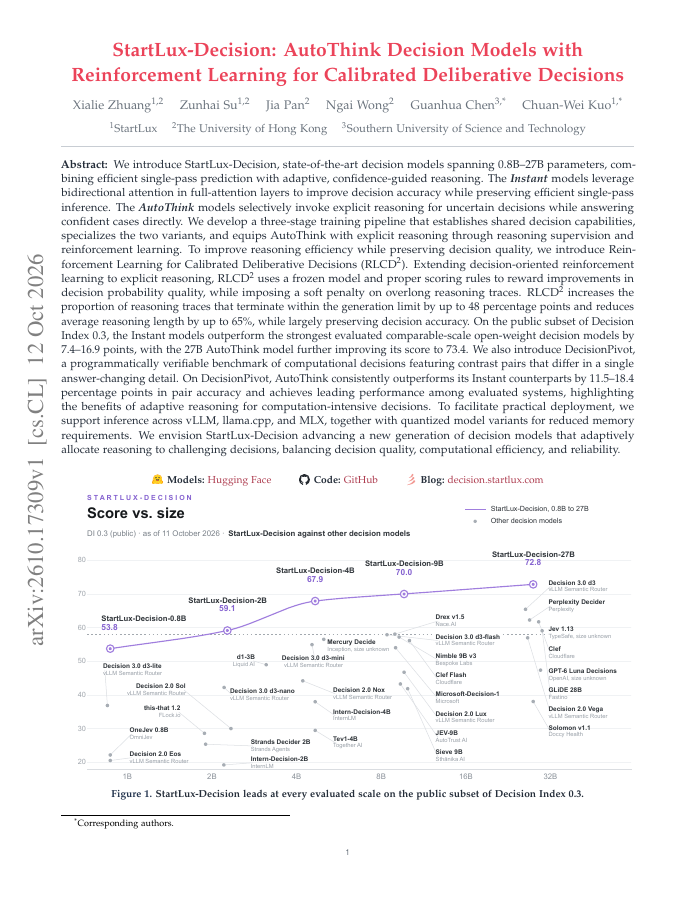
We introduce StartLux-Decision, decision models from 0.8B to 27B parameters that combine efficient single-pass prediction with adaptive, confidence-guided reasoning. The Instant models use bidirectional attention in full-attention layers to improve decision accuracy while…