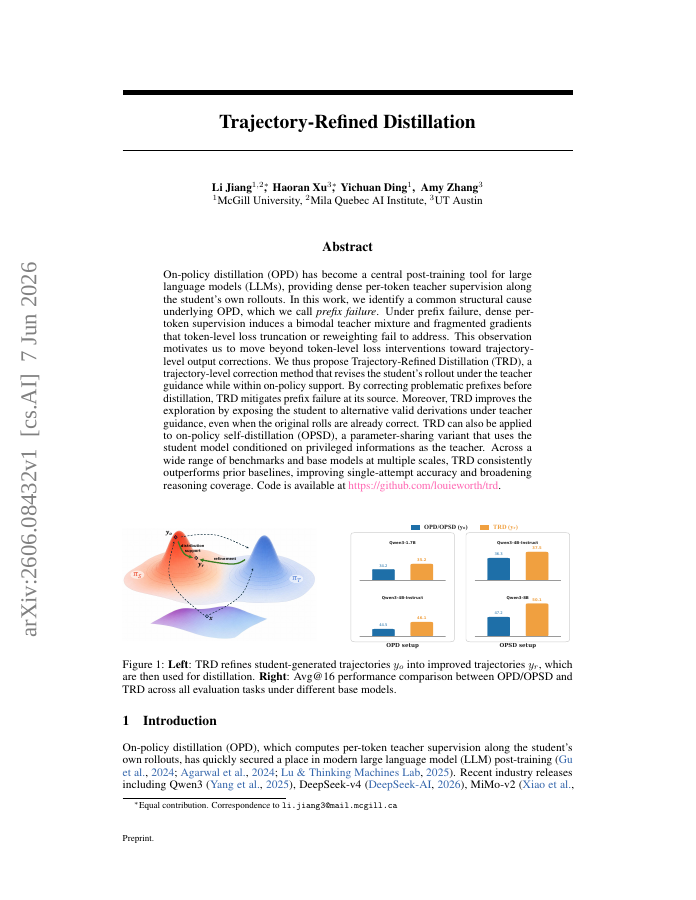
On-policy distillation (OPD) has become a central post-training tool for large language models (LLMs), providing dense per-token teacher supervision along the student's own rollouts. In this work, we identify a common structural cause underlying OPD, which we call prefix failure. Under prefix failure, dense per-token supervision induces a bimodal teacher mixture and fragmented gradients that token-level loss truncation or reweighting fail to address. We thus propose Trajectory-Refined Distillation (TRD), a trajectory-level correction method that revises the student's rollout under the teacher guidance while within on-policy support. By correcting problematic prefixes before distillation, TRD mitigates prefix failure at its source. Moreover, TRD improves exploration by exposing the student to alternative valid derivations under teacher guidance, even when the original rollouts are already correct. TRD can also be applied to on-policy self-distillation (OPSD), a parameter-sharing variant that uses the student model conditioned on privileged information as the teacher. TRD improves average math accuracy while remaining competitive on code. Under OPSD, it solves 9/23 AMOBench questions left unsolved by the Qwen3-8B base model, nearly doubling the strongest dense-KL baseline. Code is available at https://github.com/louieworth/trd.
Trajectory-Refined Distillation
On-policy distillation (OPD) has become a central post-training tool for large language models (LLMs), providing dense per-token teacher supervision along the student's own rollouts.
- Preview
- Year
- 2026
- Stars
- 108
- Hosting
- Full text hostedCC-BY-4.0
Cite
Notes
Only stored in your browser.
Attribution
- Abstract & full text
- arxiv.org/abs/2606.08432CC-BY-4.0
- TL;DR
- Semantic Scholar