8 Sep 2026
Recursive self-improvement (RSI) requires a concrete mechanism through which an AI system observes its capabilities and converts that evidence into the next round of learning.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,300 papers.
8 Sep 2026
Recursive self-improvement (RSI) requires a concrete mechanism through which an AI system observes its capabilities and converts that evidence into the next round of learning.
21 Sep 2026
Sparse on-policy distillation (OPD) allocates teacher supervision to a small subset of tokens in student-generated trajectories. However, useful teacher guidance can yield a noisy update when its gradient is estimated from a sampled next token.
11 Sep 2026
Post-training attention sparsification reduces the quadratic cumulative attention cost of pretrained Transformers by selecting a small set of context units (tokens or blocks) for each query.
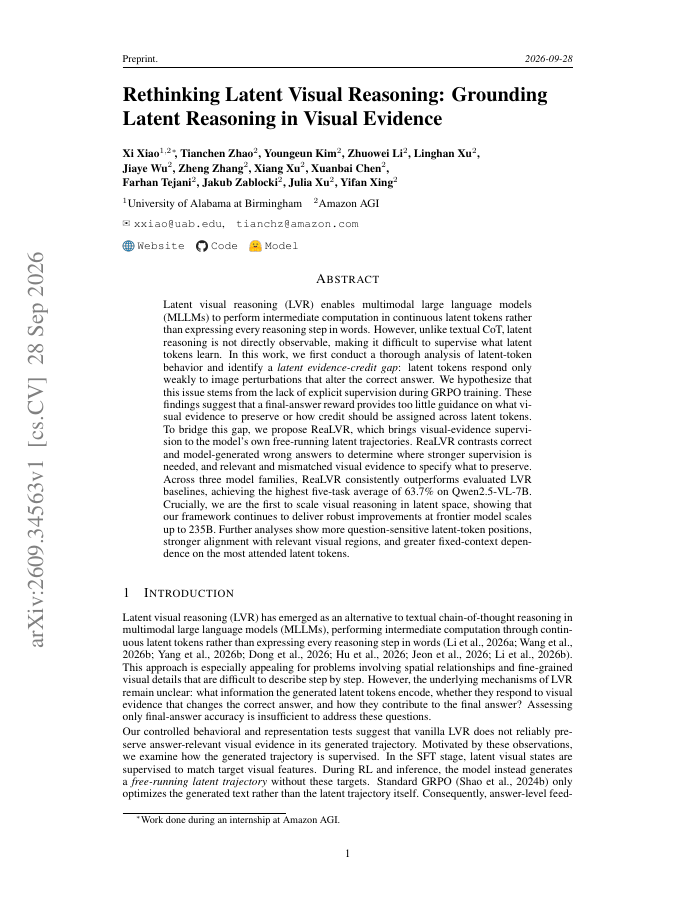
28 Sep 2026
Latent visual reasoning (LVR) enables multimodal large language models (MLLMs) to perform intermediate computation in continuous latent tokens rather than expressing every reasoning step in words.
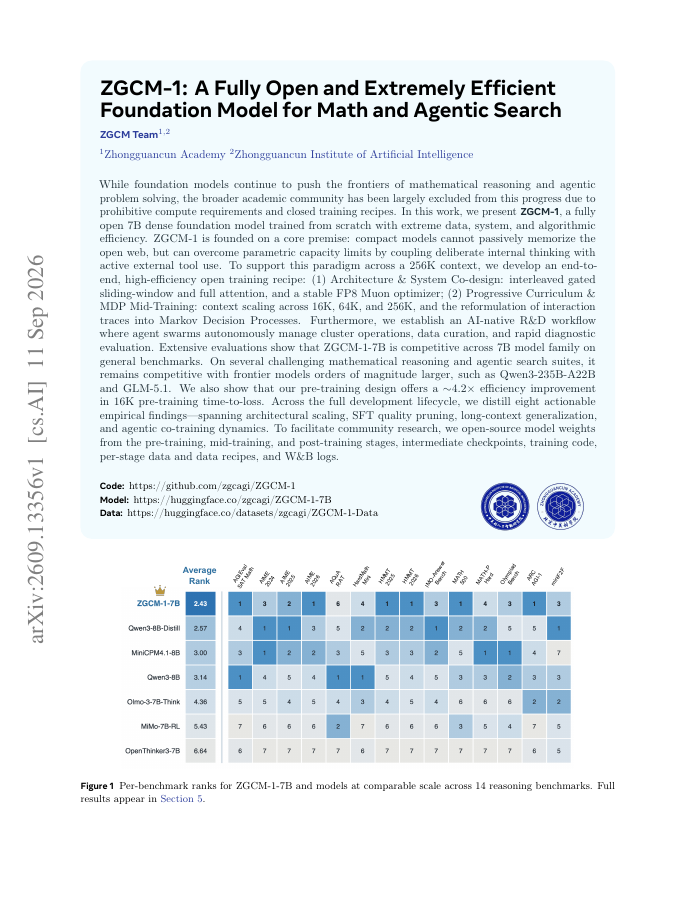
11 Sep 2026
In this work, we present ZGCM-1, a fully open 7B dense foundation model trained from scratch with extreme data, system, and algorithmic efficiency. ZGCM-1 is founded on a core premise: compact models cannot passively memorize the open web, but can overcome parametric capacity…
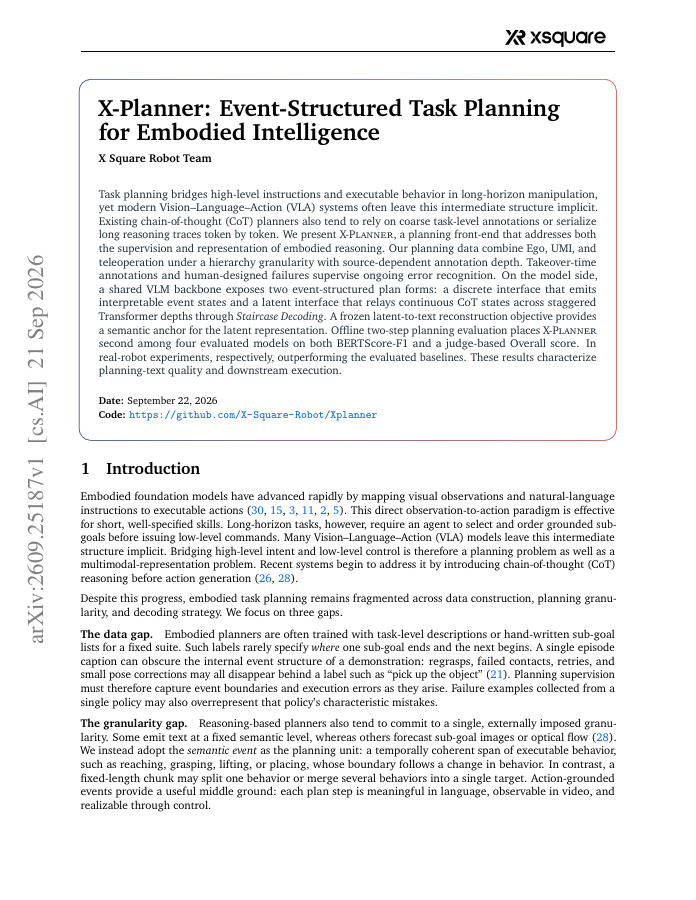
21 Sep 2026
Task planning bridges high-level instructions and executable behavior in long-horizon manipulation, yet modern Vision-Language-Action (VLA) systems often leave this intermediate structure implicit.
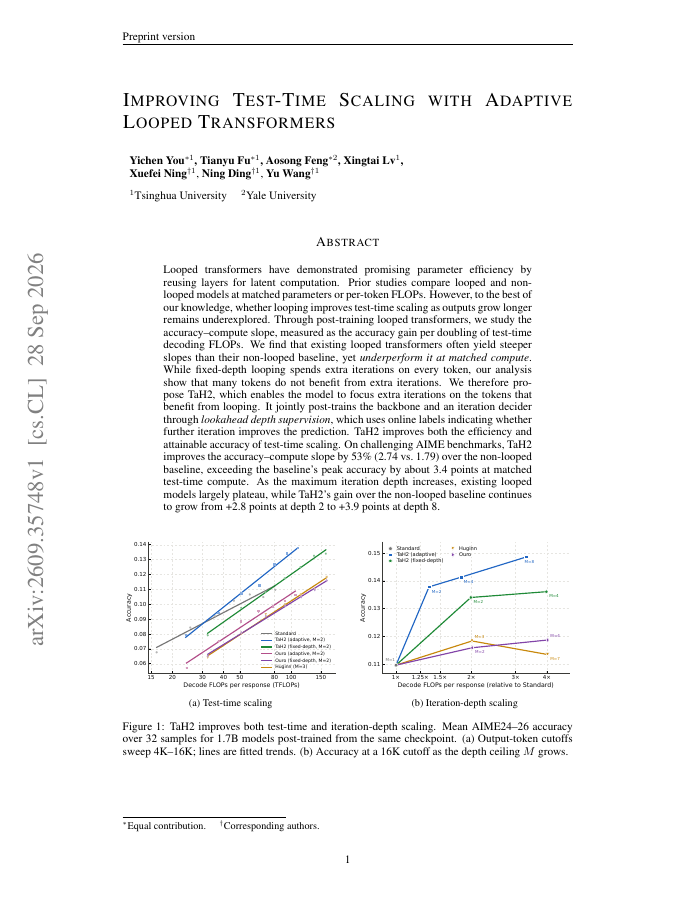
28 Sep 2026
Looped transformers have demonstrated promising parameter efficiency by reusing layers for latent computation. Prior studies compare looped and non-looped models at matched parameters or per-token FLOPs.
9 Sep 2026
We study how model post-training and test-time inference design affect natural-language proof generation for hard olympiad mathematics. Starting from Nemotron 3 Ultra, we train two specialist checkpoints using supervised fine-tuning and reinforcement learning, and evaluate…
28 Sep 2026
On-policy distillation (OPD) is a widely adopted post-training technique for LLM reasoning. It is commonly believed to transfer knowledge from a stronger teacher, yet what OPD actually distills into the student's internal representations remains unclear.
28 Sep 2026
Scaling test-time computation is a powerful way to improve language-model reasoning, and is particularly appealing for small reasoning models (sRMs) that are cheap to serve.