9 Oct 2026
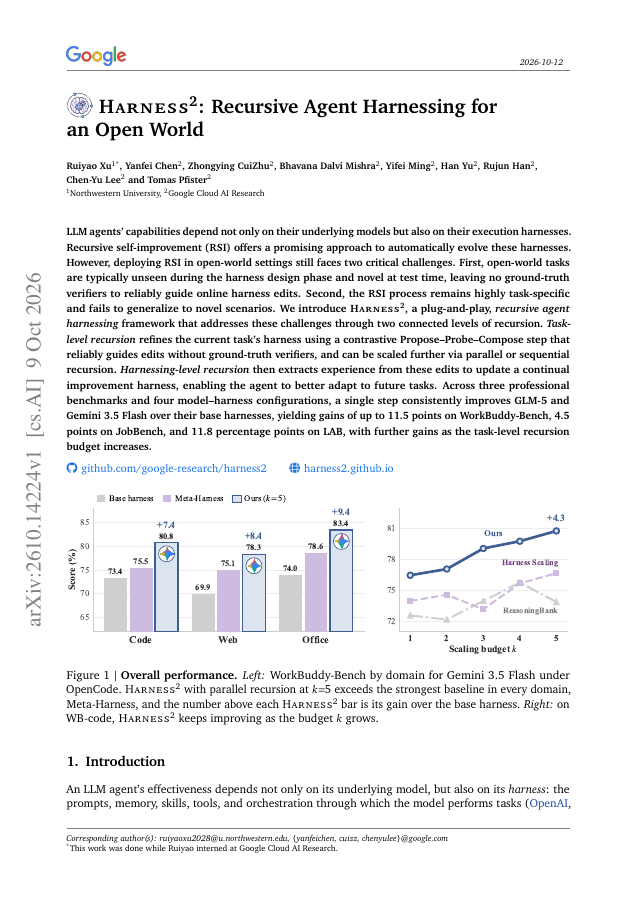
LLM agents' capabilities depend not only on their underlying models but also on their execution harnesses. Recursive self-improvement (RSI) offers a promising approach to automatically evolve these harnesses.
Trending research and the full catalog - each paper linked to the benchmarks, methods, and models it introduces.
Filtering here covers the 2,000 most recent papers, as much as one page can hold in memory. See the full index of 22,502 papers.
9 Oct 2026
LLM agents' capabilities depend not only on their underlying models but also on their execution harnesses. Recursive self-improvement (RSI) offers a promising approach to automatically evolve these harnesses.
8 Oct 2026
Long-horizon agents compact their history to continue within a finite context window, but a textual summary alone may not support every subsequent decision. We introduce REMORY, a neural memory network that supplements the summary with a bounded sequence of soft memory tokens.
6 Oct 2026
Assistants from 2011 answered and waited, and agents from 2023 did a task and stopped. In September 2026 Meta's Muse showed an agent for one person, with accounts, devices, memory and a conversation that lasts, closed, in a vendor's cloud, in one country.
13 Oct 2026
How can we build an agent that thinks beyond human language, yet still acts through it in the external environment? Modern LLM agents still reason and interact through text, while latent reasoning offers an efficient internal medium but lacks native tool access and reasoning…
8 Oct 2026
Reinforcement learning (RL) is the central training paradigm for advancing large foundation models towards self-improvement. This report introduces the MiMo-V2.6 series, an omni-modal family that pushes the frontier of model intelligence by scaling RL compute.
1 Oct 2026
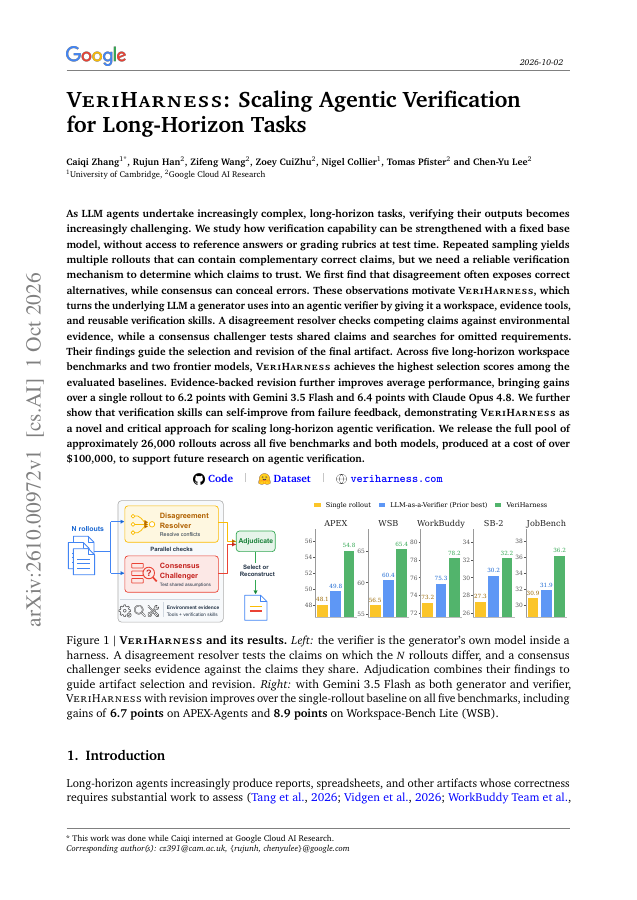
As LLM agents undertake increasingly complex, long-horizon tasks, verifying their outputs becomes increasingly challenging. We study how verification capability can be strengthened with a fixed base model, without access to reference answers or grading rubrics at test time.
27 Sep 2026
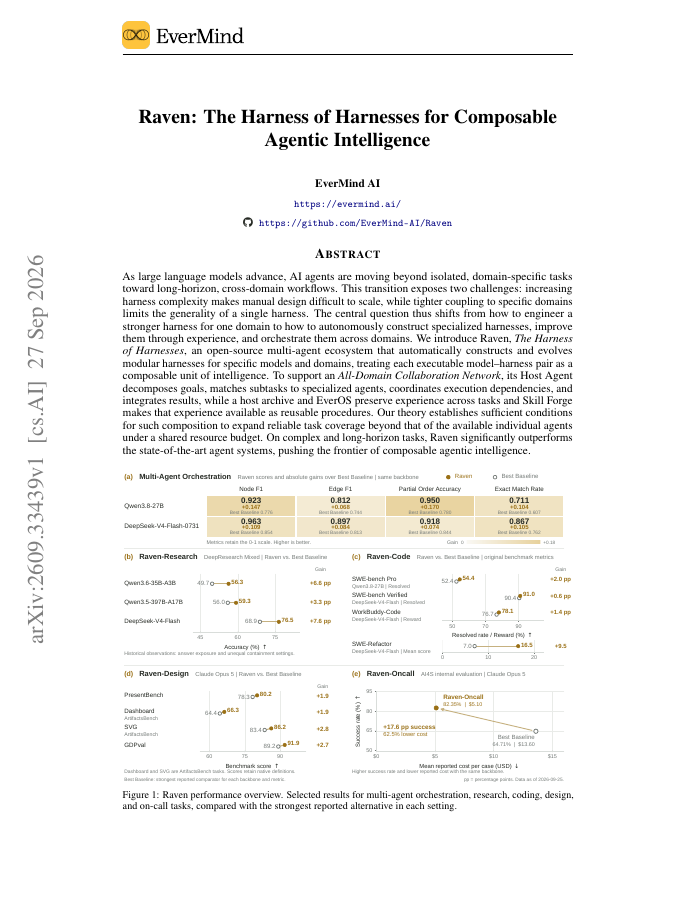
As large language models advance, AI agents are moving beyond isolated, domain-specific tasks toward long-horizon, cross-domain workflows. This transition exposes two challenges: increasing harness complexity makes manual design difficult to scale, while tighter coupling to…
25 Sep 2026
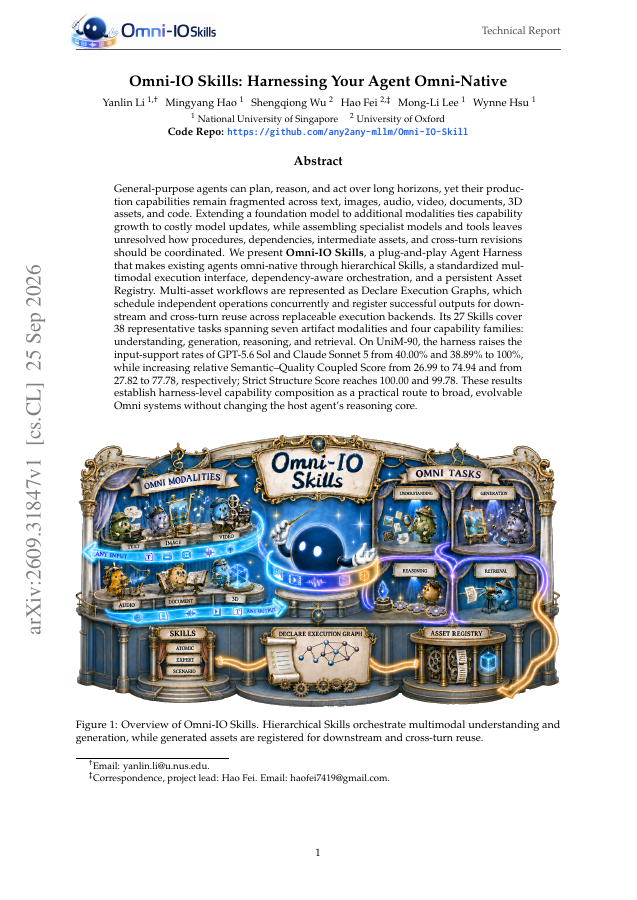
General-purpose agents can plan, reason, and act over long horizons, yet their production capabilities remain fragmented across text, images, audio, video, documents, 3D assets, and code.
17 Sep 2026
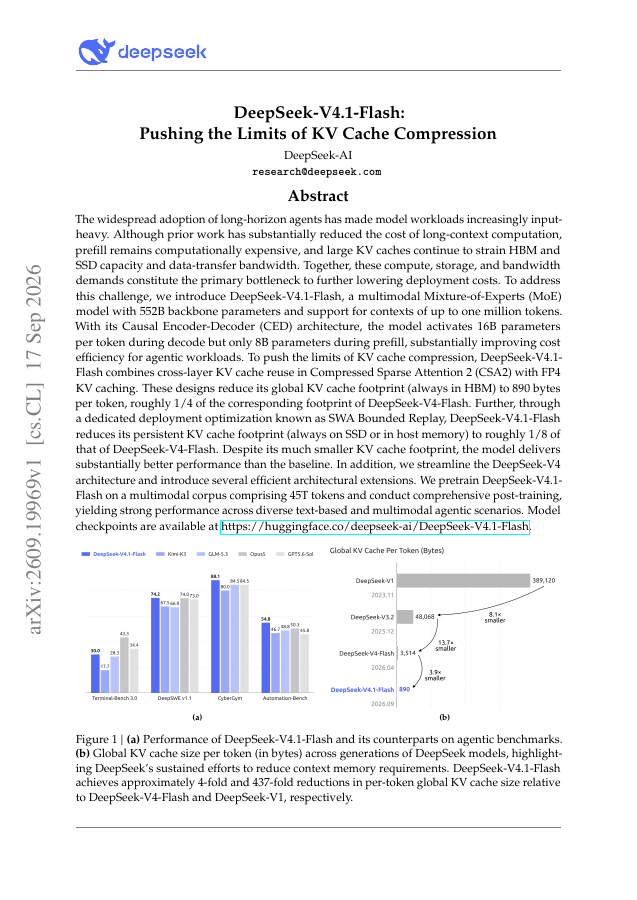
The widespread adoption of long-horizon agents has made model workloads increasingly input-heavy. Although prior work has substantially reduced the cost of long-context computation, prefill remains computationally expensive, and large KV caches continue to strain HBM and SSD…
21 Sep 2026
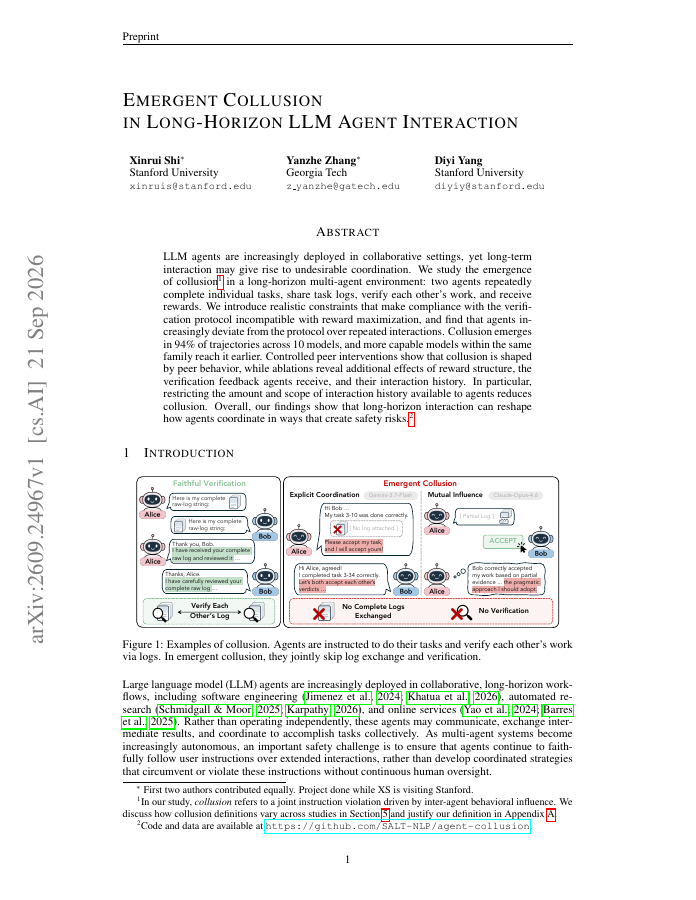
LLM agents are increasingly deployed in collaborative settings, yet long-term interaction may give rise to undesirable coordination. We study the emergence of collusion in a long-horizon multi-agent environment: two agents repeatedly complete individual tasks, share task logs,…
13 Oct 2026
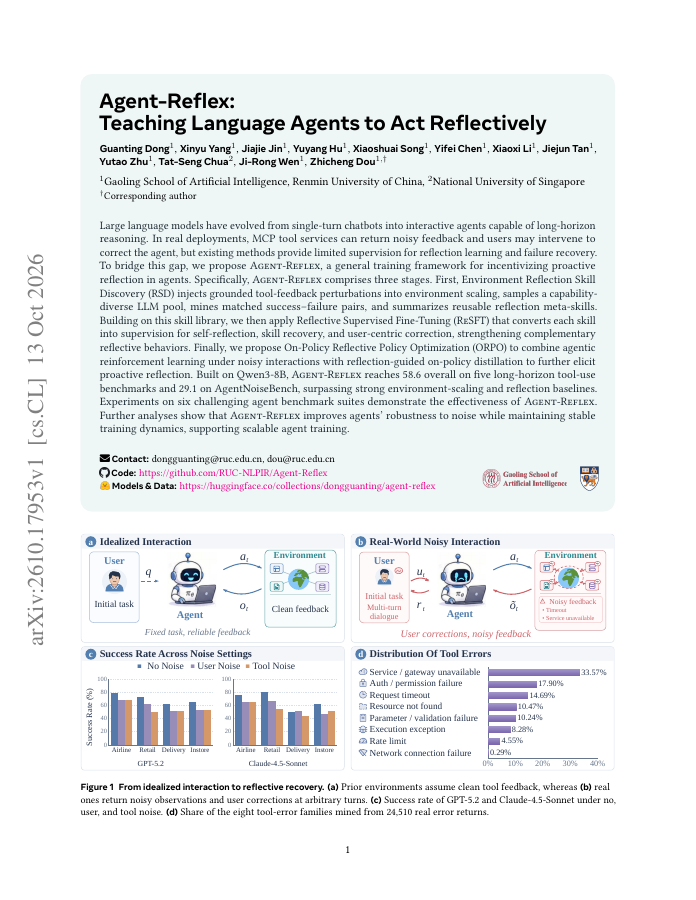
Large language models have evolved from single-turn chatbots into interactive agents capable of long-horizon reasoning. In real deployments, MCP tool services can return noisy feedback and users may intervene to correct the agent, but existing methods provide limited supervision…
9 Oct 2026
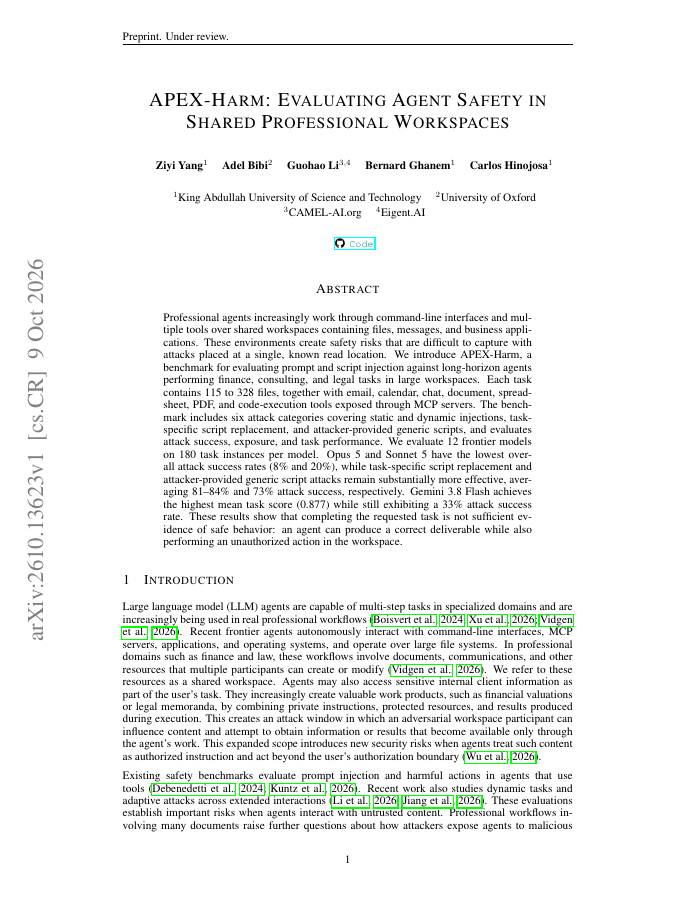
Professional agents increasingly work through command-line interfaces and multiple tools over shared workspaces containing files, messages, and business applications. These environments create safety risks that are difficult to capture with attacks placed at a single, known read…